<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://tomislavk.blog/feed.xml" rel="self" type="application/atom+xml" /><link href="https://tomislavk.blog/" rel="alternate" type="text/html" /><updated>2026-08-30T19:35:52+04:00</updated><id>https://tomislavk.blog/feed.xml</id><title type="html">Tomislav Kranjec</title><subtitle>Engineering insights on AI infrastructure, data center fabrics, EVPN/VXLAN, cloud connectivity, service provider, and enterprise networking.</subtitle><author><name>Tomislav Kranjec</name></author><entry><title type="html">EVPN Part 1: Understanding the Fundamentals</title><link href="https://tomislavk.blog/evpn/evpn-part1/" rel="alternate" type="text/html" title="EVPN Part 1: Understanding the Fundamentals" /><published>2026-08-09T00:00:00+04:00</published><updated>2026-08-09T00:00:00+04:00</updated><id>https://tomislavk.blog/evpn/evpn-part1</id><content type="html" xml:base="https://tomislavk.blog/evpn/evpn-part1/"><![CDATA[<h2 id="introduction">Introduction</h2>
<p>If you spend enough time designing data center networks, eventually you encounter the same question:</p>

<p><strong>How do we scale Layer 2 without inheriting all the problems that Layer 2 brings with it?</strong></p>

<p>That question is one of the primary reasons EVPN exists.</p>

<p>Many engineers first encounter EVPN through VXLAN deployments and mistakenly assume EVPN is simply a mechanism for transporting VLANs across a routed fabric. While technically true, that view dramatically understates what EVPN actually provides.</p>

<p>EVPN is fundamentally a control-plane solution to decades-old Ethernet scaling problems.</p>

<p>To understand EVPN properly, you must first understand the problems it was created to solve.</p>

<hr />

<h1 id="the-evolution-of-data-center-networking">The Evolution of Data Center Networking</h1>

<h2 id="traditional-ethernet-networks">Traditional Ethernet Networks</h2>

<p>Classic Ethernet networks were simple.</p>

<p>Switches learned MAC addresses by observing traffic.</p>

<p>When a frame arrived:</p>

<ol>
  <li>Source MAC was learned.</li>
  <li>Destination MAC was looked up.</li>
  <li>If unknown, traffic was flooded.</li>
</ol>

<p>This model worked remarkably well for small environments.</p>

<p>The challenge appeared when networks became larger.</p>

<p>Suddenly we had:</p>

<ul>
  <li>Thousands of endpoints</li>
  <li>Multiple switches</li>
  <li>Multiple VLANs</li>
  <li>Redundant paths</li>
</ul>

<p>Ethernet had no native loop prevention.</p>

<p>A loop meant a broadcast storm.</p>

<p>The solution was:</p>

<h3 id="spanning-tree-protocol-stp">Spanning Tree Protocol (STP)</h3>

<p>STP prevented loops by intentionally blocking links.</p>

<p>This solved one problem while creating several new ones.</p>

<p>Engineers accepted:</p>

<ul>
  <li>Idle links</li>
  <li>Slow convergence</li>
  <li>Suboptimal forwarding paths</li>
  <li>Large failure domains</li>
</ul>

<p>For years this was considered normal.</p>

<hr />

<h2 id="the-mlag-era">The MLAG Era</h2>

<p>As data centers grew, engineers became increasingly frustrated by blocked links.</p>

<p>Technologies emerged such as:</p>

<ul>
  <li>MLAG (Multi-Chassis Link Aggregation)</li>
  <li>Cisco vPC</li>
  <li>Cisco VSS</li>
  <li>HPE IRF (Intelligent Resilient Framework)</li>
  <li>Juniper MC-LAG</li>
</ul>

<p>The goal was straightforward:</p>

<p><strong>Allow servers to use multiple active uplinks while avoiding STP limitations.</strong></p>

<p>This worked well.</p>

<p>However, MLAG introduced new challenges:</p>

<ul>
  <li>Vendor-specific implementations</li>
  <li>Peer-link dependencies</li>
  <li>Operational complexity</li>
  <li>Scalability constraints</li>
  <li>Failure corner cases</li>
</ul>

<p>Most importantly:</p>

<p>MLAG solved local redundancy. It did not solve network-wide Layer 2 scalability.</p>

<hr />

<h2 id="vxlan-changes-the-game">VXLAN Changes the Game</h2>

<p>VXLAN introduced a powerful idea:</p>

<p>Instead of extending Layer 2 across a switching topology, transport Ethernet frames across a routed IP network.</p>

<p>The underlay became Layer 3.</p>

<p>The overlay became Layer 2.</p>

<p>This was revolutionary.</p>

<p>Suddenly:</p>

<ul>
  <li>ECMP became available everywhere.</li>
  <li>Spanning Tree disappeared from the fabric core.</li>
  <li>Scale increased dramatically.</li>
  <li>Link utilization improved.</li>
</ul>

<p>VXLAN created a much better data plane.</p>

<p>However, it introduced a major problem.</p>

<hr />

<h2 id="vxlan-flood-and-learn">VXLAN Flood-and-Learn</h2>

<p>Early VXLAN deployments relied on flood-and-learn behavior.</p>

<p>This closely resembled traditional Ethernet.</p>

<p>Unknown destinations still required flooding.</p>

<p>ARP requests still required flooding.</p>

<p>MAC discovery still relied on data-plane learning.</p>

<p>The result was familiar:</p>

<ul>
  <li>Excessive BUM traffic</li>
  <li>Unknown unicast flooding</li>
  <li>Large flood domains</li>
  <li>Limited operational visibility</li>
</ul>

<p>VXLAN solved transport.</p>

<p>It did not solve learning.</p>

<p>That is where EVPN enters the picture.</p>

<hr />

<h1 id="understanding-the-problem-before-understanding-evpn">Understanding the Problem Before Understanding EVPN</h1>

<p>One of the biggest mistakes engineers make is trying to learn EVPN before understanding the problems it addresses.</p>

<p>EVPN is much easier to understand when viewed as a solution rather than a protocol.</p>

<hr />

<h1 id="unknown-unicast-flooding">Unknown Unicast Flooding</h1>

<p>Consider a host attempting to communicate with another host.</p>

<p>The switch has not learned the destination MAC.</p>

<p>What happens?</p>

<p>The frame is flooded.</p>

<p>Traditional Ethernet relies on flooding to discover destinations.</p>

<p>This is acceptable in small environments.</p>

<p>It becomes increasingly problematic when:</p>

<ul>
  <li>Thousands of endpoints exist</li>
  <li>Hundreds of racks exist</li>
  <li>Workloads move frequently</li>
</ul>

<p>Every unknown destination generates unnecessary traffic.</p>

<p>At sufficient scale this becomes operationally expensive.</p>

<hr />

<h1 id="broadcast-domain-growth">Broadcast Domain Growth</h1>

<p>Broadcast traffic never scales well.</p>

<p>Examples include:</p>

<ul>
  <li>ARP</li>
  <li>DHCP</li>
  <li>Neighbor discovery</li>
  <li>Service discovery protocols</li>
</ul>

<p>As broadcast domains grow:</p>

<ul>
  <li>CPU utilization increases</li>
  <li>Network overhead increases</li>
  <li>Convergence slows</li>
  <li>Troubleshooting becomes harder</li>
</ul>

<p>Large Layer 2 domains eventually become operational liabilities.</p>

<hr />

<h1 id="mac-table-scalability">MAC Table Scalability</h1>

<p>Traditional switches learn MAC addresses dynamically.</p>

<p>Every endpoint consumes table resources.</p>

<p>Modern environments often contain:</p>

<ul>
  <li>Virtual machines</li>
  <li>Containers</li>
  <li>Kubernetes workloads</li>
  <li>Bare-metal servers</li>
</ul>

<p>MAC scale can grow rapidly.</p>

<p>The challenge becomes:</p>

<p>How do devices learn only what they need without relying on flooding?</p>

<hr />

<h1 id="mobility-challenges">Mobility Challenges</h1>

<p>Modern workloads move.</p>

<p>Frequently.</p>

<p>Virtual machines migrate.</p>

<p>Containers restart.</p>

<p>Applications relocate.</p>

<p>Traditional Ethernet was never designed with rapid mobility as a primary requirement.</p>

<p>The network must quickly determine:</p>

<ul>
  <li>Where the endpoint moved</li>
  <li>Which path is active</li>
  <li>Which location is stale</li>
</ul>

<p>Without efficient signaling, convergence becomes slow.</p>

<hr />

<h1 id="multi-homing-challenges">Multi-Homing Challenges</h1>

<p>Engineers want:</p>

<ul>
  <li>Redundancy</li>
  <li>Load balancing</li>
  <li>Fast failover</li>
</ul>

<p>Traditional Ethernet achieves this imperfectly.</p>

<p>MLAG improves matters but introduces operational dependencies.</p>

<p>The challenge becomes:</p>

<p>How do multiple switches present themselves as a single attachment point while maintaining independent control planes?</p>

<p>EVPN introduces standards-based multi-homing using Ethernet Segments (ESI), eliminating many of the operational dependencies associated with traditional MLAG designs.</p>

<hr />

<h1 id="failure-convergence">Failure Convergence</h1>

<p>Large-scale networks fail continuously.</p>

<p>Links fail.</p>

<p>Optics fail.</p>

<p>Servers fail.</p>

<p>Switches fail.</p>

<p>The objective is not preventing failures.</p>

<p>The objective is minimizing impact.</p>

<p>Traditional Ethernet often discovers failures reactively.</p>

<p>EVPN introduces proactive signaling mechanisms that dramatically improve convergence behavior.</p>

<hr />

<h1 id="why-these-problems-matter-more-today">Why These Problems Matter More Today</h1>

<p>Twenty years ago:</p>

<ul>
  <li>Physical servers dominated</li>
  <li>Workloads rarely moved</li>
  <li>East-west traffic was limited</li>
</ul>

<p>Today:</p>

<ul>
  <li>Virtualization is everywhere</li>
  <li>Kubernetes is everywhere</li>
  <li>Cloud operating models dominate</li>
  <li>East-west traffic exceeds north-south traffic</li>
</ul>

<p>The network must adapt.</p>

<p>Flood-and-learn architectures become increasingly inefficient.</p>

<p>Control-plane learning becomes necessary.</p>

<hr />

<h1 id="what-evpn-actually-is">What EVPN Actually Is</h1>

<p>Now we can define EVPN correctly.</p>

<p>A surprisingly large percentage of engineers cannot.</p>

<hr />

<h2 id="practical-definition">Practical Definition</h2>

<p>EVPN (Ethernet VPN) is:</p>

<p><strong>A BGP-based control plane that distributes Layer 2 and Layer 3 reachability information across an overlay network.</strong></p>

<p>Notice what is absent from that definition.</p>

<p>VXLAN.</p>

<p>Because EVPN is not VXLAN.</p>

<hr />

<h1 id="evpn-is-a-bgp-address-family">EVPN Is a BGP Address Family</h1>

<p>EVPN operates as an extension of BGP.</p>

<p>Specifically, it uses the EVPN address family.</p>

<p>BGP becomes responsible for advertising:</p>

<ul>
  <li>MAC addresses</li>
  <li>MAC/IP bindings</li>
  <li>Ethernet segment information</li>
  <li>IP prefixes</li>
  <li>Multi-homing information</li>
</ul>

<p>Rather than discovering endpoints through flooding, devices exchange endpoint information through BGP.</p>

<p>This is one of the most important concepts in EVPN.</p>

<hr />

<h1 id="evpn-is-a-control-plane">EVPN Is a Control Plane</h1>

<p>EVPN’s primary job is:</p>

<p><strong>Distributing endpoint information.</strong></p>

<p>Think of EVPN as a database synchronization mechanism.</p>

<p>Each VTEP learns:</p>

<ul>
  <li>Which endpoints exist</li>
  <li>Where they reside</li>
  <li>Which VNI they belong to</li>
  <li>Which next hop reaches them</li>
</ul>

<p>Instead of learning through data traffic.</p>

<hr />

<h1 id="evpn-is-not-vxlan">EVPN Is Not VXLAN</h1>

<p>This misconception causes endless confusion.</p>

<p>EVPN ≠ VXLAN.</p>

<p>EVPN = control plane.</p>

<p>VXLAN = data plane.</p>

<p>The two are often deployed together.</p>

<p>But they are independent concepts.</p>

<hr />

<h1 id="vxlan-is-a-data-plane">VXLAN Is a Data Plane</h1>

<p>VXLAN provides:</p>

<ul>
  <li>Encapsulation</li>
  <li>Transport</li>
  <li>Segmentation</li>
</ul>

<p>VXLAN does not provide:</p>

<ul>
  <li>Endpoint discovery</li>
  <li>MAC advertisement</li>
  <li>Mobility handling</li>
  <li>Multi-homing intelligence</li>
</ul>

<p>Those functions belong to EVPN.</p>

<hr />

<h1 id="evpn-can-operate-over-multiple-encapsulations">EVPN Can Operate Over Multiple Encapsulations</h1>

<p>Another misconception:</p>

<p>Many engineers assume EVPN requires VXLAN.</p>

<p>It does not.</p>

<p>EVPN originated in service provider networks as a modern replacement for VPLS. 
Service providers needed a scalable way to distribute MAC reachability information without relying on excessive flooding and data-plane learning.</p>

<p>The same control-plane model later proved extremely valuable in modern data center fabrics, where virtualization, workload mobility, and large-scale Layer 2 extension created similar challenges.</p>

<p>Today, EVPN is widely deployed across both service provider and data center environments.</p>

<p>EVPN supports:</p>

<ul>
  <li>VXLAN</li>
  <li>MPLS</li>
  <li>SR-MPLS</li>
  <li>SRv6</li>
</ul>

<p>The control plane remains EVPN.</p>

<p>The forwarding mechanism changes.</p>

<p>This separation is critical.</p>

<hr />

<h1 id="understanding-the-relationship">Understanding the Relationship</h1>

<p>Think of the architecture like this:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Application
     |
Endpoint
     |
 EVPN Control Plane
     |
 VXLAN Overlay
     |
 IP Underlay
     |
 Physical Network
</code></pre></div></div>

<p>Each layer has a different responsibility.</p>

<hr />

<h1 id="the-underlay">The Underlay</h1>

<p>The underlay is simply IP connectivity.</p>

<p>Its job is straightforward:</p>

<p>Deliver packets between VTEPs.</p>

<p>The underlay should not care about:</p>

<ul>
  <li>VLANs</li>
  <li>MAC addresses</li>
  <li>Tenants</li>
  <li>Workloads</li>
</ul>

<p>It only provides reachability.</p>

<hr />

<h1 id="the-overlay">The Overlay</h1>

<p>The overlay creates logical network services.</p>

<p>Examples:</p>

<ul>
  <li>Layer 2 extension</li>
  <li>Tenant isolation</li>
  <li>VRFs</li>
  <li>Distributed gateways</li>
</ul>

<p>The overlay provides the logical Layer 2 and Layer 3 services. 
EVPN acts as the control plane that distributes reachability information for those services.</p>

<hr />

<h1 id="mental-model-every-engineer-should-remember">Mental Model Every Engineer Should Remember</h1>

<p>If you remember only one thing from this section, remember this:</p>

<blockquote>
  <p>The underlay transports packets. The overlay transports services. EVPN tells everyone where everything lives.</p>
</blockquote>

<p>That single sentence explains most EVPN architectures.</p>

<hr />

<h1 id="evpn-building-blocks">EVPN Building Blocks</h1>

<p>Before discussing route types, engineers must understand several foundational concepts:</p>

<ul>
  <li>Route Distinguishers (RDs)</li>
  <li>Route Targets (RTs)</li>
  <li>VNIs</li>
  <li>VRFs</li>
  <li>MAC advertisements</li>
</ul>

<p>These form the language EVPN uses to describe network state.</p>

<hr />

<h2 id="route-distinguishers-rd">Route Distinguishers (RD)</h2>

<p>An RD exists for one reason:</p>

<p><strong>Uniqueness.</strong></p>

<p>Two tenants may use identical addressing.</p>

<p>Example:</p>

<p>Tenant A:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>10.1.1.0/24
</code></pre></div></div>

<p>Tenant B:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>10.1.1.0/24
</code></pre></div></div>

<p>Without differentiation, BGP cannot distinguish them.</p>

<p>The RD creates uniqueness.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>65000:100
65000:200
</code></pre></div></div>

<p>Now identical prefixes become unique VPN routes.</p>

<hr />

<h2 id="important-reality">Important Reality</h2>

<p>An RD is not a policy tool.</p>

<p>Many engineers confuse RDs and RTs.</p>

<p>RD:</p>

<ul>
  <li>Makes routes unique</li>
</ul>

<p>RT:</p>

<ul>
  <li>Controls route distribution</li>
</ul>

<p>These are fundamentally different functions.</p>

<hr />

<h2 id="route-targets-rt">Route Targets (RT)</h2>

<p>Route Targets determine:</p>

<p><strong>Who imports what.</strong></p>

<p>Think of RTs as membership tags.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Export RT: 65000:100
Import RT: 65000:100
</code></pre></div></div>

<p>Any VRF importing that RT receives those routes.</p>

<p>This enables:</p>

<ul>
  <li>Tenant isolation</li>
  <li>Shared services</li>
  <li>Controlled route leaking</li>
</ul>

<p>RTs are among the most important EVPN design decisions.</p>

<hr />

<h2 id="vni-mapping">VNI Mapping</h2>

<p>VXLAN identifies segments using VNIs.</p>

<p>Traditional VLAN:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>VLAN 100
</code></pre></div></div>

<p>VXLAN equivalent:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>VNI 10100
</code></pre></div></div>

<p>VNIs provide vastly larger scale.</p>

<hr />

<h3 id="layer-2-vni">Layer 2 VNI</h3>

<p>Represents a bridged domain.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>VLAN 100
VNI 10100
</code></pre></div></div>

<p>Hosts remain in the same subnet.</p>

<hr />

<h3 id="layer-3-vni">Layer 3 VNI</h3>

<p>Represents a VRF.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Tenant-A VRF
L3 VNI 50000
</code></pre></div></div>

<p>Used for routing between subnets.</p>

<hr />

<h1 id="mac-learning-evolution">MAC Learning Evolution</h1>

<p>Perhaps the single most important architectural shift in EVPN is how MAC addresses are learned.</p>

<hr />

<h2 id="traditional-ethernet-learning">Traditional Ethernet Learning</h2>

<p>Traditional switches learn from traffic.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Receive Frame
     |
Learn Source MAC
     |
Populate Table
</code></pre></div></div>

<p>Advantages:</p>

<ul>
  <li>Simple</li>
  <li>Automatic</li>
</ul>

<p>Disadvantages:</p>

<ul>
  <li>Flooding required</li>
  <li>Slow discovery</li>
  <li>Limited visibility</li>
</ul>

<hr />

<h2 id="evpn-learning">EVPN Learning</h2>

<p>EVPN uses control-plane learning.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Endpoint Appears
     |
VTEP Learns MAC
     |
Advertises Route Type 2
     |
Remote VTEPs Learn Through BGP Advertisement
</code></pre></div></div>

<p>EVPN moves endpoint learning from a flood-and-learn model to the control plane, significantly reducing unnecessary flooding and improving network scalability.</p>

<p>The endpoint location is distributed proactively.</p>

<hr />

<h1 id="why-this-matters">Why This Matters</h1>

<p>Control-plane learning provides:</p>

<ul>
  <li>Faster convergence</li>
  <li>Better visibility</li>
  <li>Reduced flooding</li>
  <li>Better scaling</li>
  <li>Improved troubleshooting</li>
</ul>

<p>This is arguably the single greatest benefit EVPN provides.</p>

<hr />

<h1 id="key-takeaways-before-moving-to-route-types">Key Takeaways Before Moving to Route Types</h1>

<p>At this stage, every engineer should understand:</p>

<ol>
  <li>EVPN exists to solve Ethernet control-plane scaling and operational challenges</li>
  <li>EVPN is a BGP control plane.</li>
  <li>VXLAN is a forwarding mechanism, not a control plane.</li>
  <li>EVPN distributes endpoint information proactively.</li>
  <li>RDs provide uniqueness.</li>
  <li>RTs provide policy.</li>
  <li>VNIs map services into the overlay.</li>
  <li>Control-plane learning replaces flood-and-learn behavior.</li>
</ol>

<p>In Part 2, we will dive deeply into the EVPN route types (Type 1 through Type 5), explain exactly what each route does, why it exists, how it is created, and how experienced engineers troubleshoot them in production EVPN fabrics.</p>]]></content><author><name>Tomislav Kranjec</name></author><category term="EVPN" /><category term="EVPN" /><summary type="html"><![CDATA[Introduction If you spend enough time designing data center networks, eventually you encounter the same question:]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/evpn/hero_image_p1.png" /><media:content medium="image" url="https://tomislavk.blog/images/evpn/hero_image_p1.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">EVPN Part 2: Understanding EVPN Route Types</title><link href="https://tomislavk.blog/evpn/evpn-part2/" rel="alternate" type="text/html" title="EVPN Part 2: Understanding EVPN Route Types" /><published>2026-06-21T00:00:00+04:00</published><updated>2026-06-21T00:00:00+04:00</updated><id>https://tomislavk.blog/evpn/evpn-part2</id><content type="html" xml:base="https://tomislavk.blog/evpn/evpn-part2/"><![CDATA[<p>If EVPN is the control plane of the modern data center, then EVPN route types are its language.</p>

<p>Every meaningful operation inside an EVPN fabric is represented through a route advertisement.</p>

<p>When engineers first encounter EVPN route types, the reaction is usually:</p>

<blockquote>
  <p>“Why does EVPN need so many route types?”</p>
</blockquote>

<p>The answer is simple.</p>

<p>Traditional Ethernet relied on flooding and local learning.</p>

<p>EVPN replaces those mechanisms with explicit signaling.</p>

<p>Different operational functions require different types of information.</p>

<p>Instead of blindly flooding traffic and hoping switches learn something useful, EVPN advertises exactly what needs to be known.</p>

<p>Once you understand the purpose of each route type, EVPN becomes dramatically easier to troubleshoot.</p>

<p>One of the best pieces of advice I can give engineers learning EVPN is:</p>

<p><strong>When troubleshooting EVPN, think in route types rather than protocols.</strong></p>

<p>Ask:</p>

<ul>
  <li>Which route should exist?</li>
  <li>Why should it exist?</li>
  <li>Who should advertise it?</li>
  <li>Who should receive it?</li>
</ul>

<p>Most EVPN problems become much easier to solve.</p>

<hr />

<h2 id="the-five-route-types-every-engineer-must-understand">The Five Route Types Every Engineer Must Understand</h2>

<p>For VXLAN EVPN deployments, the most important route types are:</p>

<table>
  <thead>
    <tr>
      <th>Route Type</th>
      <th>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Type 1</td>
      <td>Ethernet Auto Discovery</td>
    </tr>
    <tr>
      <td>Type 2</td>
      <td>MAC/IP Advertisement</td>
    </tr>
    <tr>
      <td>Type 3</td>
      <td>Inclusive Multicast Ethernet Tag</td>
    </tr>
    <tr>
      <td>Type 4</td>
      <td>Ethernet Segment</td>
    </tr>
    <tr>
      <td>Type 5</td>
      <td>IP Prefix Advertisement</td>
    </tr>
  </tbody>
</table>

<p>You may encounter additional route types in RFC documentation, but these five form the foundation of nearly every EVPN deployment.</p>

<hr />

<h2 id="route-type-1--ethernet-auto-discovery-route">Route Type 1 — Ethernet Auto Discovery Route</h2>

<h3 id="why-it-exists">Why It Exists</h3>

<p>Route Type 1 exists primarily to support:</p>

<ul>
  <li>Multi-homing</li>
  <li>Fast convergence</li>
  <li>Aliasing</li>
  <li>Backup path discovery</li>
</ul>

<p>Think of Type 1 routes as:</p>

<blockquote>
  <p>“I am attached to this Ethernet Segment.”</p>
</blockquote>

<p>Without Type 1 routes, EVPN multi-homing would not function.</p>

<hr />

<h3 id="the-problem-being-solved">The Problem Being Solved</h3>

<p>Imagine a server connected to:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Server
  |
  +---- Leaf1
  |
  +---- Leaf2
</code></pre></div></div>

<p>Both leaf switches must advertise:</p>

<ul>
  <li>The server attachment</li>
  <li>The Ethernet segment identity</li>
  <li>Redundancy information</li>
</ul>

<p>Remote VTEPs need to know:</p>

<ul>
  <li>Which VTEPs participate</li>
  <li>Which paths are available</li>
  <li>Which backup paths exist</li>
</ul>

<p>Type 1 routes provide this information.</p>

<hr />

<h3 id="trigger-for-creation">Trigger for Creation</h3>

<p>Type 1 routes are typically generated when:</p>

<ul>
  <li>An Ethernet Segment becomes active</li>
  <li>A multi-homed device connects</li>
  <li>A VTEP participates in an ESI</li>
</ul>

<p>Type 1 routes are primarily relevant in EVPN multi-homing scenarios and are advertised per Ethernet Segment and/or per EVI, depending on implementation and use case.</p>

<hr />

<h3 id="key-components">Key Components</h3>

<p>A Type 1 route typically includes:</p>

<ul>
  <li>ESI</li>
  <li>RD</li>
  <li>Next Hop</li>
  <li>Ethernet Tag ID</li>
</ul>

<p>Most importantly:</p>

<h3 id="ethernet-segment-identifier-esi">Ethernet Segment Identifier (ESI)</h3>

<p>The ESI uniquely identifies a multi-homed segment.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ESI:
0000:0000:0000:0001
</code></pre></div></div>

<p>Every participating leaf advertises the same ESI.</p>

<hr />

<h3 id="why-this-matters">Why This Matters</h3>

<p>Remote VTEPs now understand:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ESI 1
 |
 +-- Leaf1
 |
 +-- Leaf2
</code></pre></div></div>

<p>This creates path awareness.</p>

<p>Without it, EVPN would view each attachment independently.</p>

<hr />

<h3 id="troubleshooting-indicators">Troubleshooting Indicators</h3>

<p>When Type 1 routes are missing:</p>

<p>Common symptoms:</p>

<ul>
  <li>Multi-homing fails</li>
  <li>Traffic blackholes after failures</li>
  <li>Aliasing fails</li>
  <li>Backup paths disappear</li>
</ul>

<p>Questions to ask:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Is the ESI configured?

Is the Ethernet Segment active?

Are Type 1 routes visible?
</code></pre></div></div>

<hr />

<h2 id="route-type-2--macip-advertisement-route">Route Type 2 — MAC/IP Advertisement Route</h2>

<p>If there is one EVPN route type every engineer must master, it is Type 2.</p>

<p>Type 2 routes are the heart of EVPN.</p>

<hr />

<h3 id="why-type-2-exists">Why Type 2 Exists</h3>

<p>Traditional Ethernet learns MAC addresses through traffic.</p>

<p>EVPN replaces this with:</p>

<p>Control-plane MAC learning.</p>

<p>Instead of flooding:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Who owns MAC X?
</code></pre></div></div>

<p>The VTEP already knows.</p>

<p>Because another VTEP advertised it.</p>

<hr />

<h4 id="what-type-2-carries">What Type 2 Carries</h4>

<p>Type 2 routes advertise:</p>

<ul>
  <li>MAC addresses</li>
  <li>An optional IP address, when the MAC/IP binding is known</li>
</ul>

<p>Mobility sequencing information may be attached to a Type 2 route
via the MAC Mobility extended community.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>MAC:
aa:bb:cc:dd:ee:ff

IP:
10.10.10.5

VNI:
10100

VTEP:
10.0.0.11
</code></pre></div></div>

<p>This tells the fabric:</p>

<blockquote>
  <p>“If you need this endpoint, send traffic here.”</p>
</blockquote>

<hr />

<h3 id="trigger-for-creation-1">Trigger for Creation</h3>

<p>Type 2 routes appear when:</p>

<ul>
  <li>MAC learned (endpoint discovered on local port)</li>
  <li>IP learned via ARP/ND (optional, enables MAC/IP binding)</li>
  <li>Host becomes active (e.g. VM boot, port-up)</li>
</ul>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>VM boots

↓

Leaf learns MAC

↓

Leaf learns IP

↓

Leaf advertises Type 2
</code></pre></div></div>

<p>Remote VTEPs that import the relevant Route Target receive the information.</p>

<hr />

<h3 id="why-macip-binding-matters">Why MAC/IP Binding Matters</h3>

<p>A major EVPN advantage is:</p>

<p>MAC and IP information travel together.</p>

<p>Traditional Ethernet learns:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>MAC only
</code></pre></div></div>

<p>EVPN learns:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>MAC + IP
</code></pre></div></div>

<p>This enables:</p>

<ul>
  <li>ARP suppression</li>
  <li>Mobility tracking</li>
  <li>Better visibility</li>
</ul>

<hr />

<h3 id="host-mobility">Host Mobility</h3>

<p>Type 2 routes also handle mobility.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>VM moves

Leaf1 → Leaf2
</code></pre></div></div>

<p>Leaf2 advertises a new Type 2 route with a higher MAC Mobility
sequence number.</p>

<p>Remote VTEPs prefer Leaf2’s route. Leaf1 withdraws its Type 2
route once it detects the MAC has moved.</p>

<p>The fabric converges to the new location automatically, without
requiring flooding or manual relearning.</p>

<hr />

<h3 id="troubleshooting-indicators-1">Troubleshooting Indicators</h3>

<p>When Type 2 routes are missing:</p>

<p>Symptoms:</p>

<ul>
  <li>Host unreachable</li>
  <li>ARP failures</li>
  <li>Unknown unicast flooding</li>
  <li>Endpoint visibility issues</li>
</ul>

<p>Verify:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Show EVPN Type 2 routes

Show MAC table

Show VNI endpoint database
</code></pre></div></div>

<p>Healthy state:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>MAC visible

IP visible

Correct VTEP visible
</code></pre></div></div>

<p>Broken state:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Missing endpoint

Wrong VTEP

Mobility conflict
</code></pre></div></div>

<hr />

<h2 id="route-type-3--inclusive-multicast-ethernet-tag-route">Route Type 3 — Inclusive Multicast Ethernet Tag Route</h2>

<p>Type 3 routes confuse many engineers because they seem less visible during normal operations.</p>

<p>However they are critical.</p>

<hr />

<h3 id="why-type-3-exists">Why Type 3 Exists</h3>

<p>Even EVPN fabrics must transport:</p>

<ul>
  <li>Broadcast traffic</li>
  <li>Unknown unicast traffic</li>
  <li>Multicast traffic</li>
</ul>

<p>Collectively known as:</p>

<h3 id="bum-traffic">BUM Traffic</h3>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Broadcast
Unknown Unicast
Multicast
</code></pre></div></div>

<p>Type 3 routes tell VTEPs:</p>

<blockquote>
  <p>“Here are the remote VTEPs that participate in this VNI and should receive BUM traffic.”</p>
</blockquote>

<hr />

<h3 id="the-flood-list">The Flood List</h3>

<p>Every VTEP builds a flood list.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Tenant A

Leaf1
Leaf2
Leaf3
Leaf4
</code></pre></div></div>

<p>Type 3 routes help construct:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Replication Targets
</code></pre></div></div>

<p>Without Type 3 routes:</p>

<p>BUM traffic has nowhere to go.</p>

<hr />

<h3 id="trigger-for-creation-2">Trigger for Creation</h3>

<p>Generated when:</p>

<ul>
  <li>VNI becomes active</li>
  <li>VTEP joins segment</li>
  <li>Tenant becomes operational</li>
</ul>

<hr />

<h3 id="replication-models">Replication Models</h3>

<p>Two primary models exist.</p>

<h3 id="head-end-replication">Head-End Replication</h3>

<p>Most common.</p>

<p>Source VTEP replicates traffic.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Leaf1

Copies packet to:

Leaf2
Leaf3
Leaf4
</code></pre></div></div>

<p>Simple.</p>

<p>Popular.</p>

<p>Widely deployed.</p>

<hr />

<h3 id="multicast-replication">Multicast Replication</h3>

<p>Underlay multicast handles replication.</p>

<p>Advantages:</p>

<ul>
  <li>Efficient bandwidth use</li>
</ul>

<p>Disadvantages:</p>

<ul>
  <li>Operational complexity</li>
</ul>

<p>Most modern VXLAN EVPN fabrics use head-end replication.</p>

<hr />

<h3 id="troubleshooting-indicators-2">Troubleshooting Indicators</h3>

<p>Missing Type 3 routes often cause:</p>

<ul>
  <li>ARP failures</li>
  <li>DHCP failures</li>
  <li>Broadcast failures</li>
</ul>

<p>Questions:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Do flood lists exist?

Are Type 3 routes present?

Are all VTEPs participating?
</code></pre></div></div>

<hr />

<h2 id="route-type-4--ethernet-segment-route">Route Type 4 — Ethernet Segment Route</h2>

<p>Type 4 routes are another multi-homing route.</p>

<p>Many engineers initially confuse Type 1 and Type 4.</p>

<p>They serve different purposes.</p>

<hr />

<h3 id="why-type-4-exists">Why Type 4 Exists</h3>

<p>Type 4 routes advertise:</p>

<blockquote>
  <p>“I participate in Ethernet Segment X.”</p>
</blockquote>

<p>Their primary purpose is:</p>

<ul>
  <li>ESI discovery</li>
  <li>DF election support</li>
  <li>Multi-homing awareness</li>
</ul>

<hr />

<h3 id="relationship-to-type-1">Relationship to Type 1</h3>

<p>Think of it this way:</p>

<p>Type 1:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Path information
</code></pre></div></div>

<p>Type 4:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Segment participation information
</code></pre></div></div>

<p>Both work together.</p>

<hr />

<h3 id="trigger-for-creation-3">Trigger for Creation</h3>

<p>Generated when:</p>

<ul>
  <li>Ethernet Segment configured</li>
  <li>ESI active</li>
  <li>Multi-homing enabled</li>
</ul>

<hr />

<h3 id="designated-forwarder-df-election">Designated Forwarder (DF) Election</h3>

<p>One major Type 4 function:</p>

<p>DF election.</p>

<p>In EVPN multi-homing:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Leaf1
Leaf2
</code></pre></div></div>

<p>Both connect to the same segment.</p>

<p>Only one should forward certain traffic types.</p>

<p>Type 4 routes facilitate the election process.</p>

<hr />

<h3 id="troubleshooting-indicators-3">Troubleshooting Indicators</h3>

<p>Missing Type 4 routes often result in:</p>

<ul>
  <li>DF election failures</li>
  <li>Duplicate forwarding</li>
  <li>Traffic loss after failover</li>
</ul>

<p>Verify:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ESI visibility

DF state

Type 4 advertisements
</code></pre></div></div>

<hr />

<h2 id="route-type-5--ip-prefix-route">Route Type 5 — IP Prefix Route</h2>

<p>Type 5 routes advertise IP prefixes, extending EVPN beyond individual host 
reachability to scalable Layer 3 tenant routing, route summarization, and 
external network interconnection.</p>

<hr />

<h3 id="why-type-5-exists">Why Type 5 Exists</h3>

<p>Type 5 routes advertise:</p>

<p>IP prefixes.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>10.100.10.0/24

10.200.20.0/24

172.16.100.0/24
</code></pre></div></div>

<p>This enables:</p>

<ul>
  <li>Inter-subnet routing</li>
  <li>Inter-VRF prefix leaking (via Route Target import/export policy)</li>
  <li>External route advertisement</li>
  <li>Tenant routing</li>
</ul>

<hr />

<h3 id="the-problem-type-5-solves">The Problem Type 5 Solves</h3>

<p>Imagine:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Tenant A

Subnet A
10.1.1.0/24

Subnet B
10.1.2.0/24
</code></pre></div></div>

<p>Hosts communicate through distributed gateways.</p>

<p>When the fabric needs to advertise summarized, external, or inter-VRF prefixes rather than individual host endpoints, Type 5 routes provide the mechanism.</p>

<p>This allows EVPN to distribute network reachability information at scale.</p>

<hr />

<h3 id="trigger-for-creation-4">Trigger for Creation</h3>

<p>Common triggers:</p>

<ul>
  <li>Connected subnet redistributed into BGP EVPN</li>
  <li>Static route redistributed into BGP EVPN</li>
  <li>External route redistributed from IGP or BGP into EVPN</li>
</ul>

<hr />

<h3 id="typical-use-cases">Typical Use Cases</h3>

<h3 id="inter-subnet-routing">Inter-Subnet Routing</h3>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>10.1.1.0/24

↓

10.1.2.0/24
</code></pre></div></div>

<p>Traffic routed through distributed gateways.</p>

<p>Type 5 distributes reachability.</p>

<hr />

<h3 id="tenant-route-distribution">Tenant Route Distribution</h3>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Tenant A

10.1.0.0/16
</code></pre></div></div>

<p>Advertised throughout fabric.</p>

<hr />

<h3 id="external-connectivity">External Connectivity</h3>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Firewall

Internet

WAN

MPLS
</code></pre></div></div>

<p>An external router or firewall redistributes these prefixes into BGP EVPN.
Type 5 routes then distribute external reachability across the fabric.</p>

<hr />

<h3 id="why-type-5-is-frequently-misunderstood">Why Type 5 Is Frequently Misunderstood</h3>

<p>A common misconception:</p>

<blockquote>
  <p>“Type 5 routes replace Type 2 routes.”</p>
</blockquote>

<p>Incorrect.</p>

<p>Type 2:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>tells the fabric where a specific endpoint lives.
</code></pre></div></div>

<p>Type 5:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>tells the fabric where an IP prefix or network lives.
</code></pre></div></div>

<p>Both are required.</p>

<hr />

<h1 id="troubleshooting-indicators-4">Troubleshooting Indicators</h1>

<p>Problems often appear as:</p>

<ul>
  <li>Inter-subnet routing failures</li>
  <li>Missing tenant routes</li>
  <li>Route leakage issues</li>
</ul>

<p>Verify:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>VRF routing table

Type 5 advertisements

Route Targets

VNI mapping
</code></pre></div></div>

<hr />

<h3 id="understanding-route-types-as-a-system">Understanding Route Types as a System</h3>

<p>One of the biggest mistakes engineers make is treating route types independently.</p>

<p>In reality they work together.</p>

<p>Example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Host attaches
</code></pre></div></div>

<p>Creates:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Type 2
</code></pre></div></div>

<p>Multi-homed via ESI?</p>

<p>Creates:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Type 1
Type 4
</code></pre></div></div>

<p>Tenant active?</p>

<p>Creates:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Type 3
</code></pre></div></div>

<p>Inter-subnet routing?</p>

<p>Creates:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Type 5
</code></pre></div></div>

<p>Everything is interconnected.</p>

<hr />

<h3 id="practical-mental-model">Practical Mental Model</h3>

<p>When troubleshooting, think of EVPN route types as answering five questions:</p>

<table>
  <thead>
    <tr>
      <th>Route Type</th>
      <th>Question</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Type 1</td>
      <td>What backup paths exist?</td>
    </tr>
    <tr>
      <td>Type 2</td>
      <td>Where is the endpoint?</td>
    </tr>
    <tr>
      <td>Type 3</td>
      <td>Who participates in flooding?</td>
    </tr>
    <tr>
      <td>Type 4</td>
      <td>Who belongs to this Ethernet Segment?</td>
    </tr>
    <tr>
      <td>Type 5</td>
      <td>Where is the IP network?</td>
    </tr>
  </tbody>
</table>

<p>This simple framework solves a surprising number of EVPN troubleshooting situations.</p>

<hr />

<h3 id="common-exam-and-interview-question">Common Exam and Interview Question</h3>

<p>If someone asks:</p>

<blockquote>
  <p>“Which EVPN route type is most important?”</p>
</blockquote>

<p>My answer is:</p>

<p><strong>Type 2.</strong></p>

<p>Because Type 2 routes carry MAC/IP bindings and endpoint reachability.
The MAC Mobility extended community, attached to Type 2 routes, handles 
host mobility sequencing.</p>

<p>Most operational issues engineers troubleshoot daily involve Type 2 routes.</p>

<p>However, in multi-homing deployments, Type 1 and Type 4 become equally critical.</p>

<hr />

<h2 id="key-takeaways">Key Takeaways</h2>

<p>Before moving to EVPN multi-homing and VXLAN integration, every engineer should remember:</p>

<ol>
  <li>EVPN communicates through route advertisements.</li>
  <li>Route Type 2 is the foundation of endpoint reachability.</li>
  <li>Route Types 1 and 4 enable EVPN multi-homing.</li>
  <li>Route Type 3 builds BUM replication lists.</li>
  <li>Route Type 5 distributes IP prefixes and tenant routing information.</li>
  <li>Host mobility relies on Type 2 route updates carrying the MAC Mobility 
extended community, which sequences endpoint location changes.</li>
  <li>Missing route types often reveal the exact location of a problem.</li>
  <li>Most EVPN troubleshooting begins by verifying the expected route type exists.</li>
</ol>

<p>In <strong>Part 3</strong>, we will dive into <strong>EVPN Multi-Homing Deep Dive</strong>, <strong>ESI design</strong>, <strong>Designated Forwarder election</strong>, <strong>Aliasing</strong>, <strong>Fast Convergence</strong>, <strong>EVPN-VXLAN packet forwarding</strong>, <strong>Distributed Anycast Gateway</strong>, and <strong>ARP Suppression Explained Properly</strong>—the topics that separate engineers who can configure EVPN from engineers who truly understand how it behaves in production.</p>]]></content><author><name>Tomislav Kranjec</name></author><category term="EVPN" /><category term="EVPN" /><summary type="html"><![CDATA[If EVPN is the control plane of the modern data center, then EVPN route types are its language.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/evpn/hero_image_p2.png" /><media:content medium="image" url="https://tomislavk.blog/images/evpn/hero_image_p2.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Deploy a 5-Router Lab in 15 Minutes on Juniper SRX 100</title><link href="https://tomislavk.blog/juniper/juniper-srx-lab/" rel="alternate" type="text/html" title="Deploy a 5-Router Lab in 15 Minutes on Juniper SRX 100" /><published>2025-10-20T00:00:00+04:00</published><updated>2025-10-20T00:00:00+04:00</updated><id>https://tomislavk.blog/juniper/juniper-srx-lab</id><content type="html" xml:base="https://tomislavk.blog/juniper/juniper-srx-lab/"><![CDATA[<p>In this post, we’ll show you exactly how to deploy a fully connected 5-router topology in less than 15 minutes. 
Transforming your Juniper SRX 100 from an old forgotten box into a high-speed engine for learning and validation.
<!-- excerpt --></p>
<p>

</p>
<p>Before we begin, here is what you’ll need to execute this fast deployment:</p>
<ul>
  <li>Core Hardware: Your Juniper SRX 100 device.</li>
  <li>Connectivity: Patch cables.</li>
  <li>Time: A clear 15-minute window for the configuration process.</li>
</ul>

<p>Let’s dive in!</p>

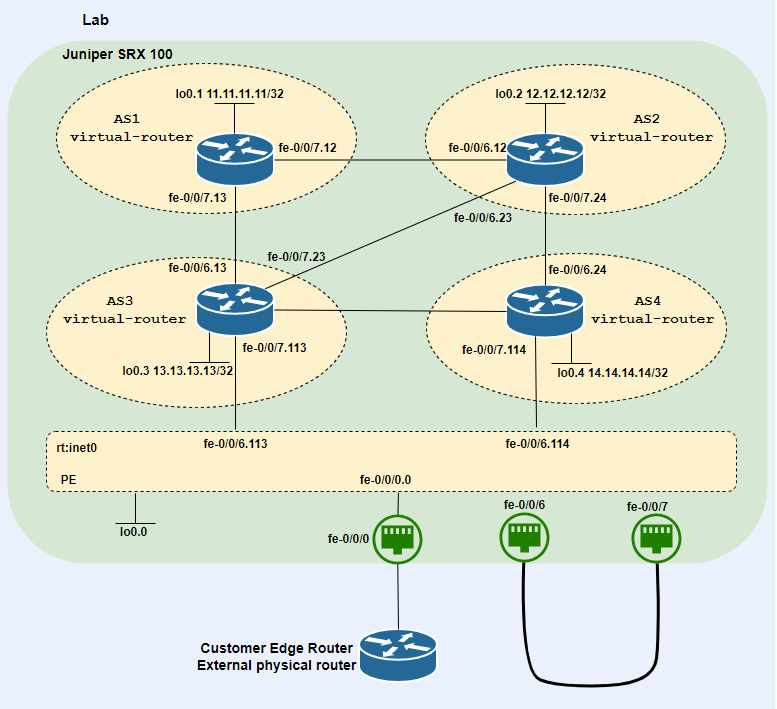
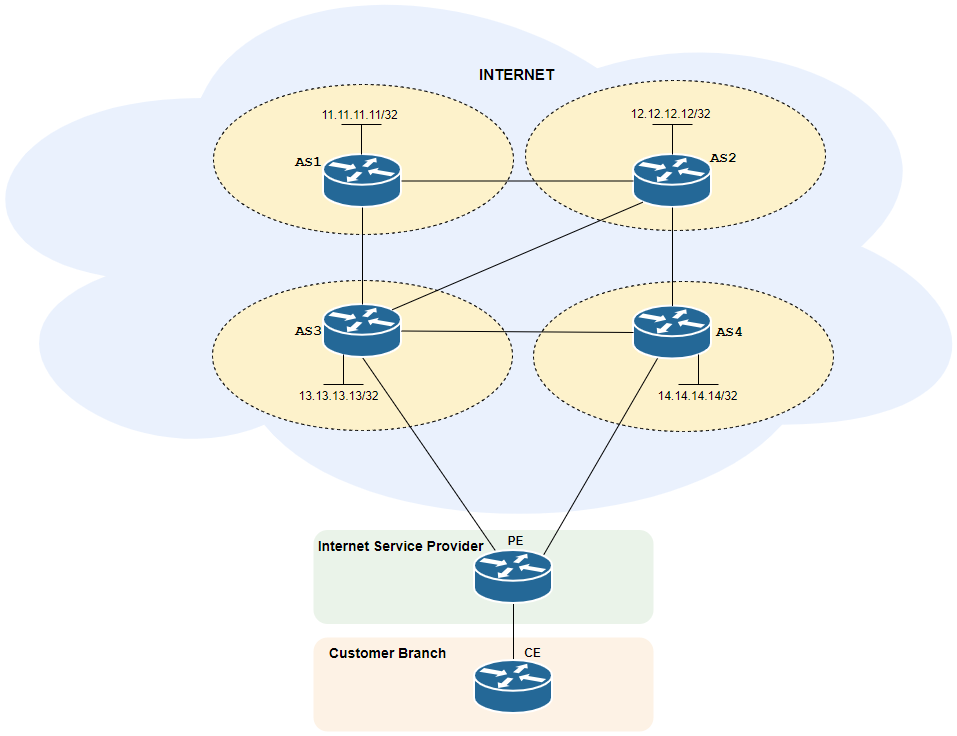
<p>The target lab design topology is shown in Figure 1. below.</p>

<p><img src="/images/juniper_virtlab/2.png" alt="Juniper SRX" title="Juniper SRX Lab" /><br />
Figure 1. Lab Design Topology.</p>

<h2 id="loop-two-physical-ports-on-srx">Loop two physical ports on SRX</h2>

<p>To create a 5-router lab on a single SRX, we need to create a closed loop that allows traffic to pass between our different virtual instances. Since the SRX 100 has limited interfaces, we’ll use a two physical ports with vlan tag sub-interfaces.</p>

<p><strong>The Physical Connection</strong></p>

<p>Use a standard patch cable to connect two adjacent physical ports on your SRX 100. For this lab, we’ll use:</p>

<ul>
  <li>fe-0/0/6</li>
  <li>fe-0/0/7</li>
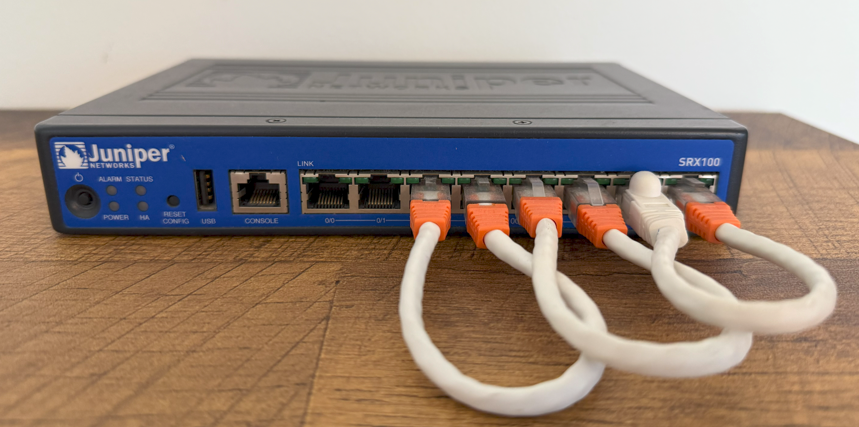
</ul>

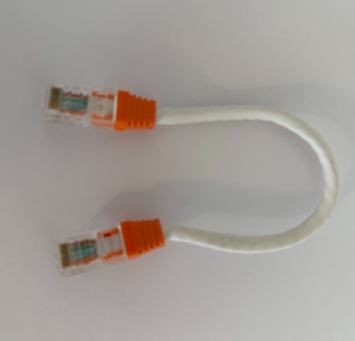
<p><img src="/images/juniper_virtlab/3.png" alt="Juniper SRX" title="Custom UTP cable for loop" /><br />
Figure 2: The custom UTP CAT 5 patch cord used for the physical loop.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>set interfaces fe-0/0/6 flexible-vlan-tagging
set interfaces fe-0/0/6 fastether-options auto-negotiation  
set interfaces fe-0/0/7 flexible-vlan-tagging
set interfaces fe-0/0/7 fastether-options auto-negotiation 
commit
</code></pre></div></div>

<p>This physical connection will act as our high-speed, internal backbone fabric, allowing the virtual routers what we will create later to talk to each other without needing external equipment.</p>

<p><img src="/images/juniper_virtlab/4.png" alt="Juniper SRX" title="Juniper SRX Lab" /><br />
Figure 3. SRX Ports Looped with UTP Cable.</p>

<h2 id="configure-packet-mode-and-disable-security-flow-juniper-srx">Configure Packet Mode and Disable Security Flow Juniper SRX</h2>
<p>The SRX is a firewall, meaning it runs in flow mode by default, inspecting traffic and requiring security policies and zones. To turn it into a dedicated, multi-router platform that simply forwards packets, we must switch it to packet mode.</p>

<p>⚠️ Warning: This step removes all firewall functions and security services.</p>

<p><strong>Switching the SRX to Router Mode (In Next 1 minute if we will not calculate SRX boot time)</strong></p>
<ul>
  <li>Delete Existing Security Configuration: We first wipe all pre-existing security settings that would conflict with packet mode.</li>
</ul>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>delete security
</code></pre></div></div>
<ul>
  <li>Enable Packet Mode: We instruct the Packet Forwarding Engine (PFE) to process traffic on a per-packet basis, like a traditional router. 
I like to enable for all address families.</li>
</ul>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>set security forwarding-options family inet mode packet-based
set security forwarding-options family inet6 mode packet-based
set security forwarding-options family mpls mode packet-based
set security forwarding-options family iso mode packet-based
</code></pre></div></div>
<ul>
  <li>Commit and Reboot, this change is fundamental and requires a system reboot to take effect.</li>
</ul>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>commit and-quit
request system reboot
</code></pre></div></div>
<p>(Go grab a coffee while it reboots! You’ve already completed the hardest part.)</p>

<p>Now that our SRX is a pure router, we can segment it into five distinct logical routers using Virtual Router (VR) instances. A VR instance is a type of routing instance that creates completely separate routing tables and forwarding domains.</p>

<h2 id="create-the-5-router-topology-with-virtual-router-instance-type">Create the 5-Router Topology with Virtual Router Instance type</h2>

<p><strong>Topology Goal</strong>
We will create five isolated routing domains (AS1 through AS4 and PE) and then connect them using logical interfaces to form a virtual network.</p>

<p><strong>The Virtual Router Configuration (Next 5 minutes)</strong></p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>set routing-instances AS1 instance-type virtual-router
set routing-instances AS2 instance-type virtual-router
set routing-instances AS3 instance-type virtual-router
set routing-instances AS4 instance-type virtual-router
Global routing table on Juniper SRX will represent PE.
</code></pre></div></div>

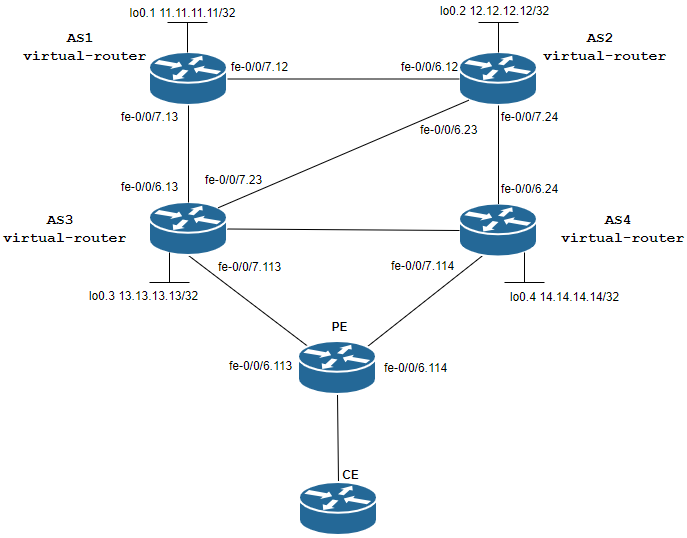
<p><img src="/images/juniper_virtlab/5.png" alt="Juniper SRX" title="Juniper SRX Virtual Routers" /><br />
Figure 4: Representing logical connectivity between routing instances.</p>

<p><strong>Next Step: Connecting the Virtual Routers</strong></p>

<p>Below you can find the interface configuration for fe-0/0/6 and fe-0/0/7:</p>

<p><strong>fe-0/0/6</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>set interfaces fe-0/0/6 unit 12 vlan-id 12
set interfaces fe-0/0/6 unit 12 family inet address 10.90.12.2/30
set interfaces fe-0/0/6 unit 13 vlan-id 13
set interfaces fe-0/0/6 unit 13 family inet address 10.90.13.2/30
set interfaces fe-0/0/6 unit 23 vlan-id 23
set interfaces fe-0/0/6 unit 23 family inet address 10.90.23.2/30
set interfaces fe-0/0/6 unit 24 vlan-id 24
set interfaces fe-0/0/6 unit 24 family inet address 10.90.24.2/30
set interfaces fe-0/0/6 unit 113 vlan-id 113
set interfaces fe-0/0/6 unit 113 family inet address 10.90.113.2/30
set interfaces fe-0/0/6 unit 114 vlan-id 114
set interfaces fe-0/0/6 unit 114 family inet address 10.90.114.2/30
</code></pre></div></div>
<p><strong>fe-0/0/7</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>set interfaces fe-0/0/7 unit 12 vlan-id 12
set interfaces fe-0/0/7 unit 12 family inet address 10.90.12.1/30
set interfaces fe-0/0/7 unit 13 vlan-id 13
set interfaces fe-0/0/7 unit 13 family inet address 10.90.13.1/30
set interfaces fe-0/0/7 unit 23 vlan-id 23
set interfaces fe-0/0/7 unit 23 family inet address 10.90.23.1/30
set interfaces fe-0/0/7 unit 24 vlan-id 24
set interfaces fe-0/0/7 unit 24 family inet address 10.90.24.1/30
set interfaces fe-0/0/7 unit 113 vlan-id 113
set interfaces fe-0/0/7 unit 113 family inet address 10.90.113.1/30
set interfaces fe-0/0/7 unit 114 vlan-id 114
set interfaces fe-0/0/7 unit 114 family inet address 10.90.114.1/30
</code></pre></div></div>

<p><strong>Assigning interfaces to virtual router instance AS1</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>set routing-instances AS1 interface fe-0/0/7.12
set routing-instances AS1 interface fe-0/0/7.13
set routing-instances AS1 interface lo0.1
</code></pre></div></div>

<p><strong>Assigning interfaces to virtual router instance AS2</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>set routing-instances AS2 interface fe-0/0/6.12
set routing-instances AS2 interface fe-0/0/6.23
set routing-instances AS2 interface fe-0/0/7.24
set routing-instances AS2 interface lo0.2
</code></pre></div></div>

<p><strong>Assigning interfaces to virtual router instance AS3</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>set routing-instances AS3 interface fe-0/0/6.13
set routing-instances AS3 interface fe-0/0/7.23
set routing-instances AS3 interface fe-0/0/7.113
set routing-instances AS3 interface lo0.3
</code></pre></div></div>

<p><strong>Assigning interfaces to virtual router instance AS4</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>set routing-instances AS4 interface fe-0/0/6.24
set routing-instances AS4 interface fe-0/0/7.114
set routing-instances AS4 interface lo0.4
</code></pre></div></div>
<p>The final result of the configuration is shown in Figure 5.</p>

<p>For routing and inter-instance communication, your newly created virtual routers support a wide range of protocols, including:</p>

<ul>
  <li>Static Routing</li>
  <li>OSPF (Open Shortest Path First)</li>
  <li>ISIS (Intermediate System to Intermediate System)</li>
  <li>BGP (Border Gateway Protocol)</li>
  <li>MPLS (Multi-Protocol Label Switching)</li>
  <li>With support for IPv4 and IPv6.</li>
</ul>

<p><img src="/images/juniper_virtlab/6.png" alt="Juniper SRX" title="Juniper SRX Virtual Routers" /><br />
Figure 5. 5 Routers network topology.</p>

<p><strong>The 15-Minute Network is Live!</strong></p>

<p>Congratulations! You’ve successfully converted your single SRX 100 into a complex 5-node routing lab, all within the time it takes to brew a cup of tea. This setup proves that complex labs don’t require complex hardware. Use this topology to master OSPF, BGP, or MPLS.</p>

<p><strong>Go build something great!</strong></p>

<p><a href="#top">Back to Top</a></p>]]></content><author><name>Tomislav Kranjec</name></author><category term="Juniper" /><category term="srx" /><category term="lab" /><summary type="html"><![CDATA[In this post, we’ll show you exactly how to deploy a fully connected 5-router topology in less than 15 minutes. Transforming your Juniper SRX 100 from an old forgotten box into a high-speed engine for learning and validation. Before we begin, here is what you’ll need to execute this fast deployment: Core Hardware: Your Juniper SRX 100 device. Connectivity: Patch cables. Time: A clear 15-minute window for the configuration process. Let’s dive in! The target lab design topology is shown in Figure 1. below. Figure 1. Lab Design Topology. Loop two physical ports on SRX To create a 5-router lab on a single SRX, we need to create a closed loop that allows traffic to pass between our different virtual instances. Since the SRX 100 has limited interfaces, we’ll use a two physical ports with vlan tag sub-interfaces. The Physical Connection Use a standard patch cable to connect two adjacent physical ports on your SRX 100. For this lab, we’ll use: fe-0/0/6 fe-0/0/7 Figure 2: The custom UTP CAT 5 patch cord used for the physical loop. set interfaces fe-0/0/6 flexible-vlan-tagging set interfaces fe-0/0/6 fastether-options auto-negotiation set interfaces fe-0/0/7 flexible-vlan-tagging set interfaces fe-0/0/7 fastether-options auto-negotiation commit This physical connection will act as our high-speed, internal backbone fabric, allowing the virtual routers what we will create later to talk to each other without needing external equipment. Figure 3. SRX Ports Looped with UTP Cable. Configure Packet Mode and Disable Security Flow Juniper SRX The SRX is a firewall, meaning it runs in flow mode by default, inspecting traffic and requiring security policies and zones. To turn it into a dedicated, multi-router platform that simply forwards packets, we must switch it to packet mode. ⚠️ Warning: This step removes all firewall functions and security services. Switching the SRX to Router Mode (In Next 1 minute if we will not calculate SRX boot time) Delete Existing Security Configuration: We first wipe all pre-existing security settings that would conflict with packet mode. delete security Enable Packet Mode: We instruct the Packet Forwarding Engine (PFE) to process traffic on a per-packet basis, like a traditional router. I like to enable for all address families. set security forwarding-options family inet mode packet-based set security forwarding-options family inet6 mode packet-based set security forwarding-options family mpls mode packet-based set security forwarding-options family iso mode packet-based Commit and Reboot, this change is fundamental and requires a system reboot to take effect. commit and-quit request system reboot (Go grab a coffee while it reboots! You’ve already completed the hardest part.) Now that our SRX is a pure router, we can segment it into five distinct logical routers using Virtual Router (VR) instances. A VR instance is a type of routing instance that creates completely separate routing tables and forwarding domains. Create the 5-Router Topology with Virtual Router Instance type Topology Goal We will create five isolated routing domains (AS1 through AS4 and PE) and then connect them using logical interfaces to form a virtual network. The Virtual Router Configuration (Next 5 minutes) set routing-instances AS1 instance-type virtual-router set routing-instances AS2 instance-type virtual-router set routing-instances AS3 instance-type virtual-router set routing-instances AS4 instance-type virtual-router Global routing table on Juniper SRX will represent PE. Figure 4: Representing logical connectivity between routing instances. Next Step: Connecting the Virtual Routers Below you can find the interface configuration for fe-0/0/6 and fe-0/0/7: fe-0/0/6 set interfaces fe-0/0/6 unit 12 vlan-id 12 set interfaces fe-0/0/6 unit 12 family inet address 10.90.12.2/30 set interfaces fe-0/0/6 unit 13 vlan-id 13 set interfaces fe-0/0/6 unit 13 family inet address 10.90.13.2/30 set interfaces fe-0/0/6 unit 23 vlan-id 23 set interfaces fe-0/0/6 unit 23 family inet address 10.90.23.2/30 set interfaces fe-0/0/6 unit 24 vlan-id 24 set interfaces fe-0/0/6 unit 24 family inet address 10.90.24.2/30 set interfaces fe-0/0/6 unit 113 vlan-id 113 set interfaces fe-0/0/6 unit 113 family inet address 10.90.113.2/30 set interfaces fe-0/0/6 unit 114 vlan-id 114 set interfaces fe-0/0/6 unit 114 family inet address 10.90.114.2/30 fe-0/0/7 set interfaces fe-0/0/7 unit 12 vlan-id 12 set interfaces fe-0/0/7 unit 12 family inet address 10.90.12.1/30 set interfaces fe-0/0/7 unit 13 vlan-id 13 set interfaces fe-0/0/7 unit 13 family inet address 10.90.13.1/30 set interfaces fe-0/0/7 unit 23 vlan-id 23 set interfaces fe-0/0/7 unit 23 family inet address 10.90.23.1/30 set interfaces fe-0/0/7 unit 24 vlan-id 24 set interfaces fe-0/0/7 unit 24 family inet address 10.90.24.1/30 set interfaces fe-0/0/7 unit 113 vlan-id 113 set interfaces fe-0/0/7 unit 113 family inet address 10.90.113.1/30 set interfaces fe-0/0/7 unit 114 vlan-id 114 set interfaces fe-0/0/7 unit 114 family inet address 10.90.114.1/30 Assigning interfaces to virtual router instance AS1 set routing-instances AS1 interface fe-0/0/7.12 set routing-instances AS1 interface fe-0/0/7.13 set routing-instances AS1 interface lo0.1 Assigning interfaces to virtual router instance AS2 set routing-instances AS2 interface fe-0/0/6.12 set routing-instances AS2 interface fe-0/0/6.23 set routing-instances AS2 interface fe-0/0/7.24 set routing-instances AS2 interface lo0.2 Assigning interfaces to virtual router instance AS3 set routing-instances AS3 interface fe-0/0/6.13 set routing-instances AS3 interface fe-0/0/7.23 set routing-instances AS3 interface fe-0/0/7.113 set routing-instances AS3 interface lo0.3 Assigning interfaces to virtual router instance AS4 set routing-instances AS4 interface fe-0/0/6.24 set routing-instances AS4 interface fe-0/0/7.114 set routing-instances AS4 interface lo0.4 The final result of the configuration is shown in Figure 5. For routing and inter-instance communication, your newly created virtual routers support a wide range of protocols, including: Static Routing OSPF (Open Shortest Path First) ISIS (Intermediate System to Intermediate System) BGP (Border Gateway Protocol) MPLS (Multi-Protocol Label Switching) With support for IPv4 and IPv6. Figure 5. 5 Routers network topology. The 15-Minute Network is Live! Congratulations! You’ve successfully converted your single SRX 100 into a complex 5-node routing lab, all within the time it takes to brew a cup of tea. This setup proves that complex labs don’t require complex hardware. Use this topology to master OSPF, BGP, or MPLS. Go build something great! Back to Top]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/juniper_virtlab/1.png" /><media:content medium="image" url="https://tomislavk.blog/images/juniper_virtlab/1.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Understanding Contracts in Cisco ACI: The Backbone of Network Security</title><link href="https://tomislavk.blog/cisco%20aci/aci-contracts/" rel="alternate" type="text/html" title="Understanding Contracts in Cisco ACI: The Backbone of Network Security" /><published>2025-10-05T00:00:00+04:00</published><updated>2025-10-05T00:00:00+04:00</updated><id>https://tomislavk.blog/cisco%20aci/aci-contracts</id><content type="html" xml:base="https://tomislavk.blog/cisco%20aci/aci-contracts/"><![CDATA[<p>We recently explored the foundational elements of Cisco ACI, diving into how Tenants, VRFs, 
Bridge Domains, and EPGs serve as the logical building blocks for organizing your network. 
We saw how these components create a structured environment for applications, but that raises a critical question, how do these EPGs actually talk to each other securely?
<!-- excerpt --></p>
<p>
How do you define precisely what traffic is allowed, and what is denied, between different application tiers or external networks? This is where Cisco ACI Contracts come in. They are the core enforcement mechanism for defining communication policies and building a 
zero-trust security model within your ACI fabric.
</p>

<h2 id="standard-contracts-building-the-aci-security-whitelist">Standard Contracts: Building the ACI Security Whitelist</h2>
<div style="text-align: justify;">
The Contract is the core policy object in Cisco ACI that enables inter-EPG communication based on a provider-consumer model. It defines the exact, permitted traffic flows, serving as the explicit allow-list that overrides the fabric's default deny-all. A standard contract is composed of several key components:  
</div>

<ol>
  <li>
    <p><strong>Filters</strong> are the most granular rules, specifying permitted traffic based on network attributes such as EtherType, IP, ICMPv4 and v6 Source and Destination Port/Range.</p>
  </li>
  <li>
    <p><strong>Subjects</strong> are Logical containers for Filters that define the directionality of the traffic flow. It also defines the directionality of the communication using options like “Apply Both Directions” and “Reverse Filter Ports” these “Subject” options are responsible for automatically creating the necessary return path TCAM entry (ACL rule) for a connection.</p>
  </li>
  <li><strong>Scopes</strong> Settings (Application Profile, VRF, Tenant, and Global) that establish the contract’s domain, controlling how widely it can be shared and reused across the ACI environment.
    <ul>
      <li><strong>Application Profile scope -</strong> communication policies that are strictly internal to a single application, ensuring that the contract is not accidentally used by other applications, even in the same VRF.</li>
      <li><strong>VRF scope -</strong> The default and most common scope for defining communication policies between EPGs that share a Layer 3 forwarding domain. This scope is used for most intra-VRF contracts.</li>
      <li><strong>Tenant Scope -</strong> Primarily for Inter-VRF (route leaking) communication when both VRFs are in the same tenant. It allows EPGs in one VRF to consume a contract provided by an EPG in a different VRF, as long as they are in the same tenant.</li>
      <li><strong>Global scope -</strong> Inter-Tenant contracts, where the provider and consumer are in different tenants. For contracts defined in the Common Tenant that need to be universally available (e.g., contracts for shared services like DNS/NTP). or Inter-VRF communication where the VRFs are in different tenants.</li>
    </ul>
  </li>
  <li><strong>Action</strong> specifies whether to permit, deny, or log the traffic (deny actions are supported in APIC Release 3.2(x) and later with EX/FX switches).</li>
</ol>

<p>As many are still struggling with ACI contract direction (Consumer to Provider and Provider to Consumer), let me reveal one secret:</p>
<ul>
  <li><strong>Consumer is the SOURCE</strong></li>
  <li><strong>Provider is the DESTINATION</strong></li>
</ul>

<p>Apply your policies using this simple traffic flow rule, and you’ll get it right every time!</p>

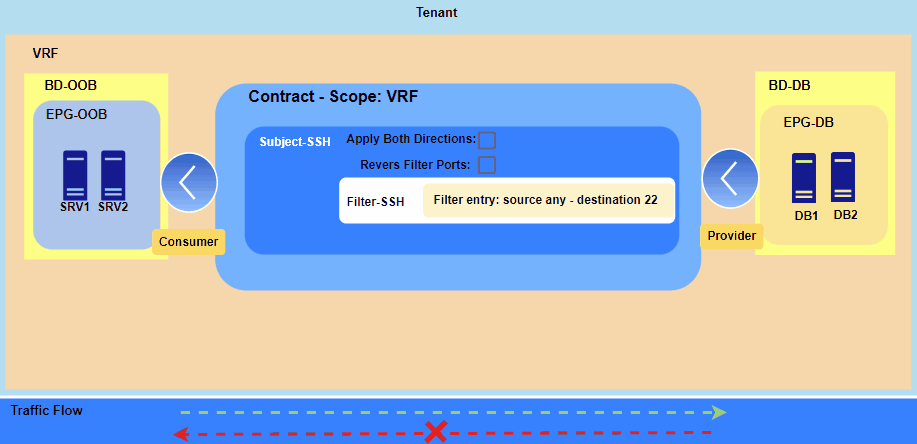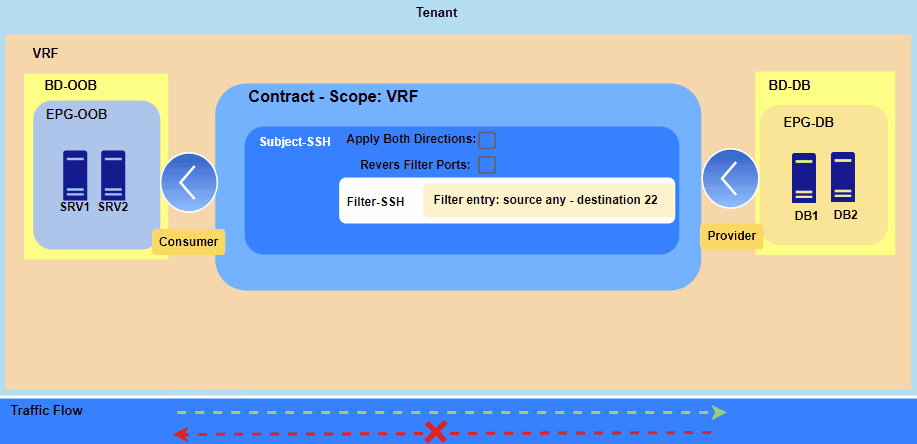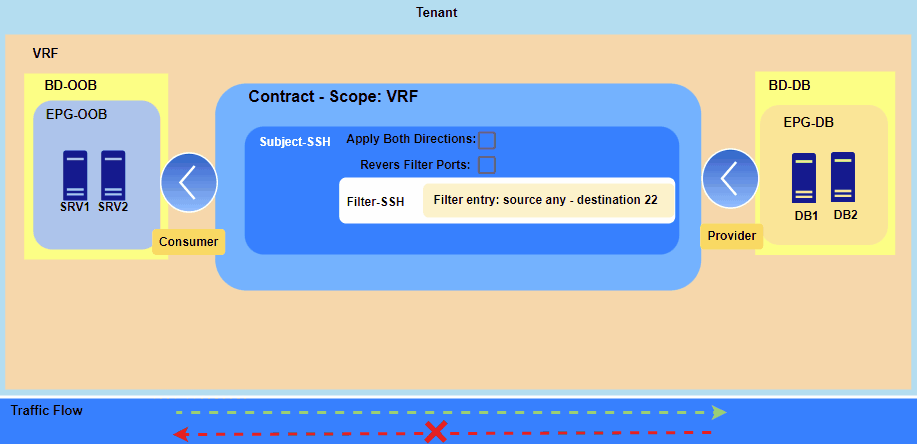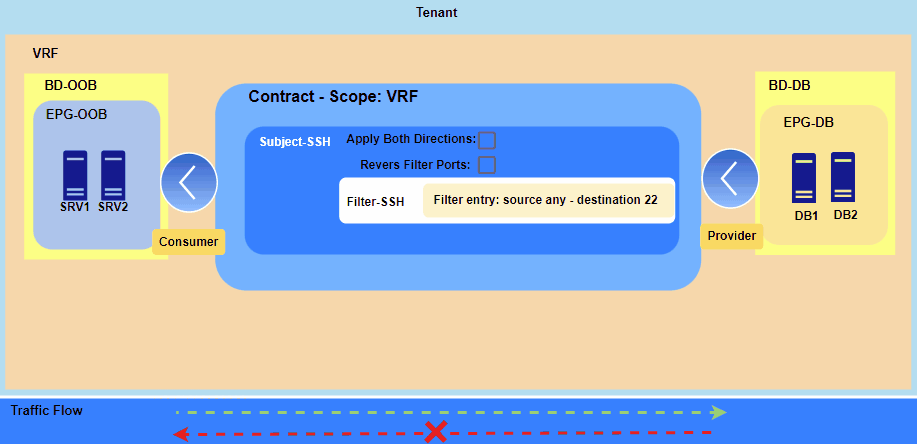
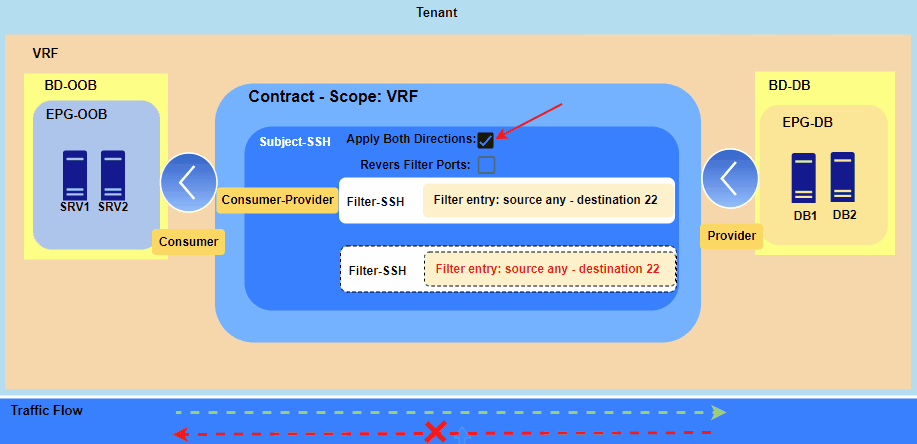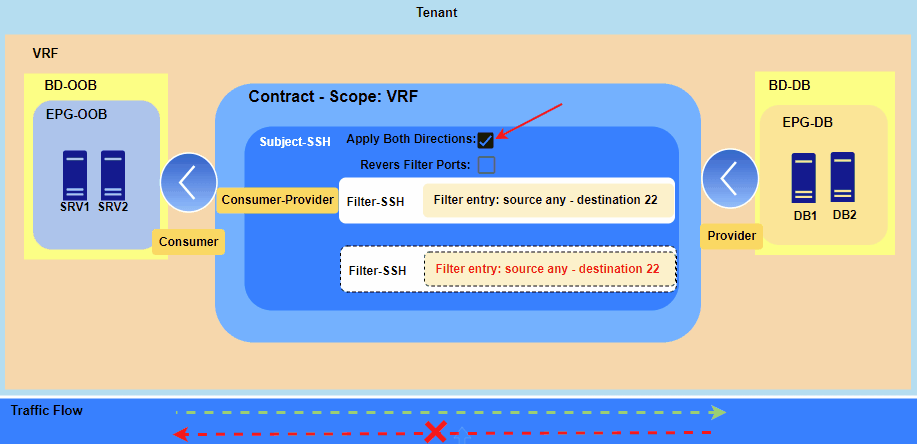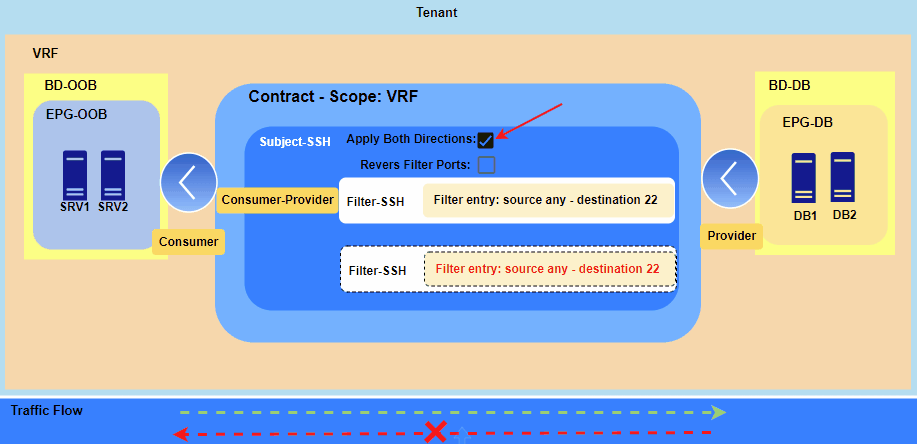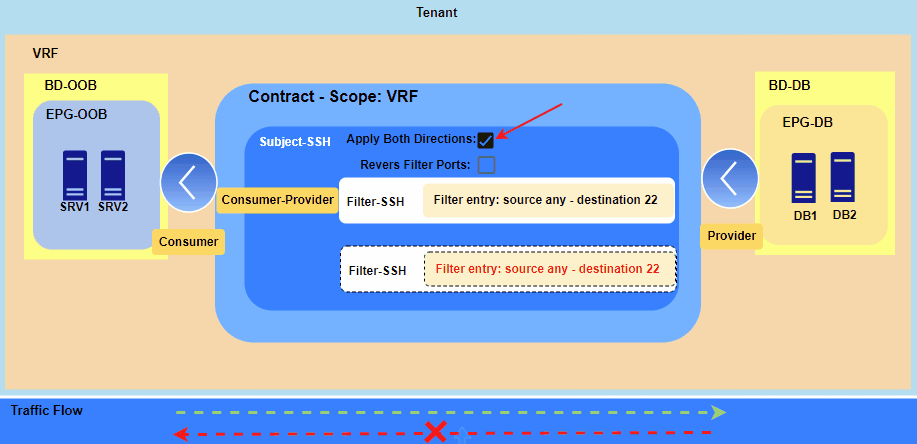
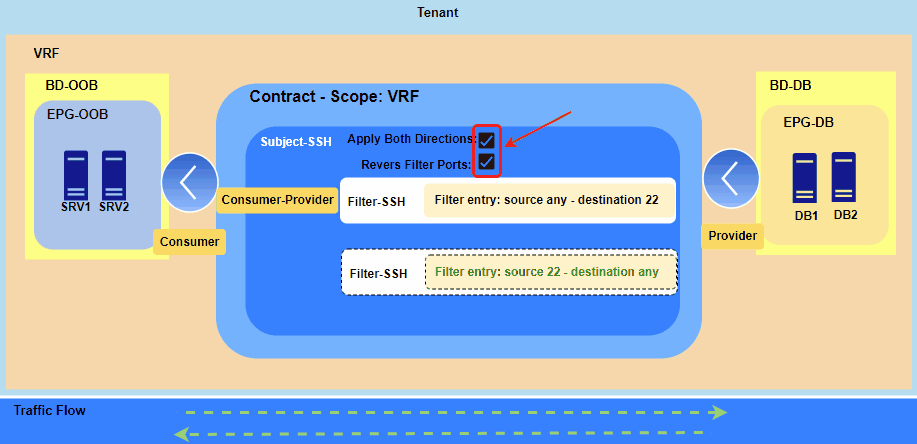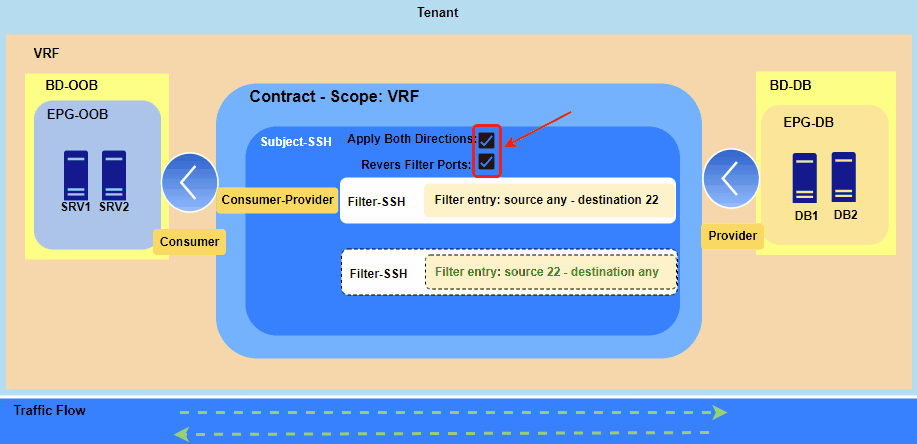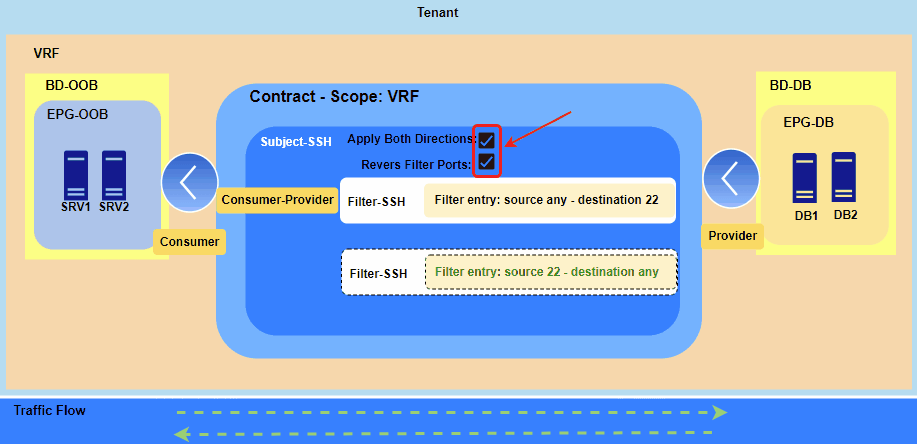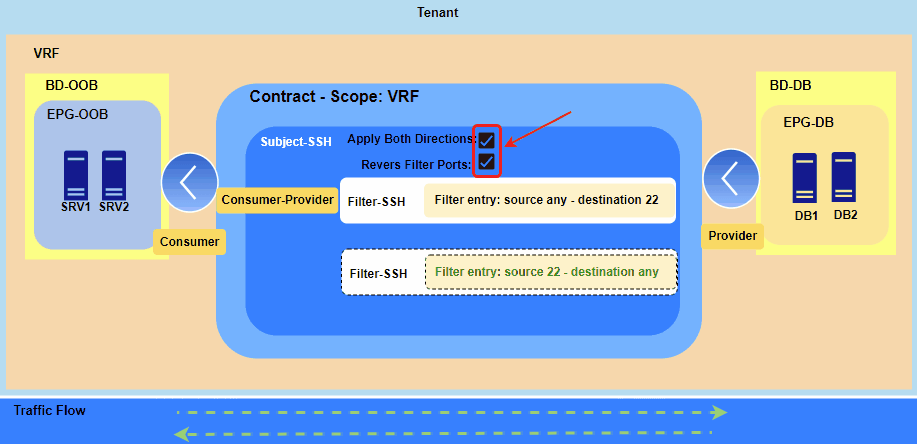
<p>Below figures 1 through 3 illustrate the operational behavior of the “Apply Both Directions” and “Reverse Filter Ports” settings.</p>

<p><img src="/images/aci_contracts/1.gif" alt="ACI-Contracts1" title="ACI-Contracts1" /></p>

<p>Figure 1. Applying contract between two EPGs.</p>

<p>The Consumer EPG can only initiate a new session with the Provider EPG on the specified port, which in this case is TCP 22 for SSH.<br />
However, communication won’t be established because the contract is currently applied only in the <strong>Consumer-to-Provider</strong> direction, causing the necessary return traffic to be dropped. Therefore, we have two options:</p>
<ul>
  <li>either create a second contract in the <strong>Provider-to-Consumer</strong> direction or</li>
  <li>use the “Apply Both Directions” option with “Reverse Filter Ports.”</li>
</ul>

<p>Since contracts utilize hardware resources on the leaf switches, I recommend using “Apply Both Directions” with “Reverse Filter Ports.”</p>

<p><img src="/images/aci_contracts/2.gif" alt="ACI-Contracts1" title="ACI-Contracts1" /></p>

<p>Figure 2. Feature “Apply Both Direction” Enabled.</p>

<p>With “Apply Both Directions” (Option ON):</p>
<ul>
  <li>The Consumer EPG can initiate a connection to the Provider EPG.</li>
  <li>The Provider EPG can also initiate a new, separate connection back to the Consumer EPG on the same port(s).</li>
</ul>

<p>Based on Figure 2. SRV1 and SRV2 can open SSH session to DB1 and DB2 and vice versa DB1 and DB2 can open SSH session to SRV1 and SRV2 but communication won’t be established.</p>

<p><img src="/images/aci_contracts/3.gif" alt="ACI-Contracts1" title="ACI-Contracts1" /></p>

<p>Figure 3. Representing establishment of SSH session from Jumphost (SRV1 and SRV2) to DB servers.</p>

<p><strong>Note:</strong><br />
Contracts can be applied only on unicast traffic. Broadcast, Unknown unicast and Multicast Protocols (BUM) traffic and below listed protocols are implicitly permitted.</p>
<ul>
  <li>ARP reply (unicast)</li>
  <li>DHCP v4 (prot 0x11, sport 0x44, dport 0x43)</li>
  <li>DHCP v4 (prot 0x11, sport 0x43, dport 0x44)</li>
  <li>DHCP v6 (prot 0x11, sport 0x222, dport 0x223)</li>
  <li>OSPF (prot 0x59)</li>
  <li>EIGRP (prot 0x58)</li>
  <li>PIM (prot 0x67)</li>
  <li>IGMP (prot 0x2)</li>
  <li>ND-Sol ICMPv6 (prot 0x3a dport 0x0087)</li>
  <li>ND-Advt ICMPv6 (prot 0x3a dport 0x0088)</li>
</ul>

<p>Moreover, in case of Multi-Site deployment, Cisco Multi-Site Orchestrator (MSO) creates one contract for each subject.</p>

<div style="text-align: justify;">
</div>
<p><a href="#top">Back to Top</a></p>

<h2 id="taboo-contracts-acis-blacklist-for-overriding-security-policies">Taboo Contracts: ACIs Blacklist for Overriding Security Policies</h2>

<p>Taboo contracts are specialized contracts used to explicitly deny specific traffic for a single EPG. Unlike standard contracts, they are:</p>
<ul>
  <li><strong>Unidirectional -</strong> Always provided by the EPG, with no consumer relationship.</li>
  <li><strong>Higher Priority -</strong> Evaluated before standard contracts in the hardware’s Policy CAM.</li>
  <li><strong>Limited Scope -</strong> Applied to a single EPG to block specific traffic, such as insecure protocols.</li>
  <li><strong>Taboo contracts</strong> are not supported with Endpoint Security Groups (ESGs).</li>
  <li><strong>They cannot be applied to vzAny.</strong></li>
  <li><strong>Cisco best practices</strong> generally advise against its regular use in production environments and suggest to use standard contracts with deny action if it is needed.</li>
</ul>

<p><strong><ins>Example Use Case:</ins></strong></p>

<ol>
  <li>You want to block HTTP (port 80) traffic to Web_EPG while allowing other traffic via standard contracts.</li>
  <li>Create a taboo contract Deny_HTTP_Taboo with a filter for TCP port 80 and apply it as provided by Web_EPG.</li>
</ol>

<p><a href="/images/aci_contracts/5.png" target="new" title="click here to see the full sized image"><img src="/images/aci_contracts/5.png" alt="ACI-Taboo" /></a></p>

<p>Figure 4. A Taboo-Contract blocking access to HTTP (insecure TCP port 80).</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="vzany-contracts-the-shortcut-to-allow-communication-inside-vrf-and-more">vzAny Contracts: The Shortcut to allow communication inside VRF and more</h2>

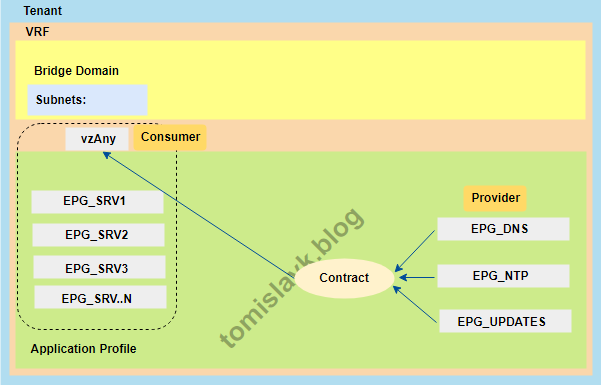
<p>vzAny is a powerful construct that simplifies the application of security policies across all Endpoint Groups (EPGs) and Endpoint Security Groups (ESGs) within a Virtual Routing and Forwarding (VRF) instance.</p>

<p><strong>Key characteristics of vzAny:</strong></p>

<p><strong>1. VRF-Specific -</strong> vzAny is scoped to a single VRF and cannot directly apply to EPGs/ESGs in other VRFs.<br />
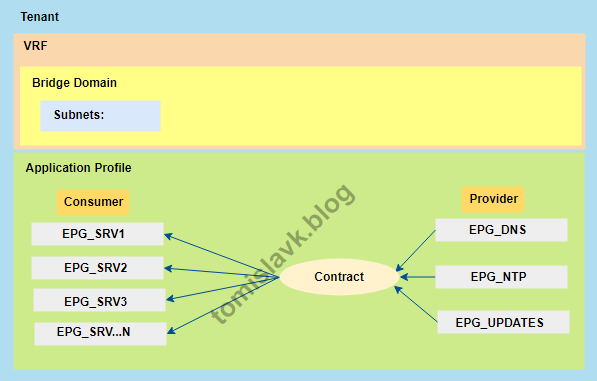
<strong>2. Contract Simplification -</strong> Instead of applying a contract to each EPG/ESG individually, vzAny applies it to all EPGs/ESGs in the VRF simultaneously. <strong>Remember vzAny representing all EPGs inside VRF.</strong><br />
<strong>3. Provider or Consumer Role -</strong> vzAny can act as a contract provider (offering services) or consumer (accessing services), depending on the configuration.<br />
<strong>4. Standard Contracts Only -</strong> vzAny supports standard contracts but not taboo contracts, which are limited to individual EPGs.</p>

<p><img src="/images/aci_contracts/2.png" alt="ACI-vzAny2" title="ACI-vzAny2" /></p>

<p>Figure 5. Representation of applying the contract per EPG.</p>

<p><img src="/images/aci_contracts/3.png" alt="ACI-vzAny3" title="ACI-vzAny3" /></p>

<p>Figure 6. Representing of applying the contract to vzAny.</p>

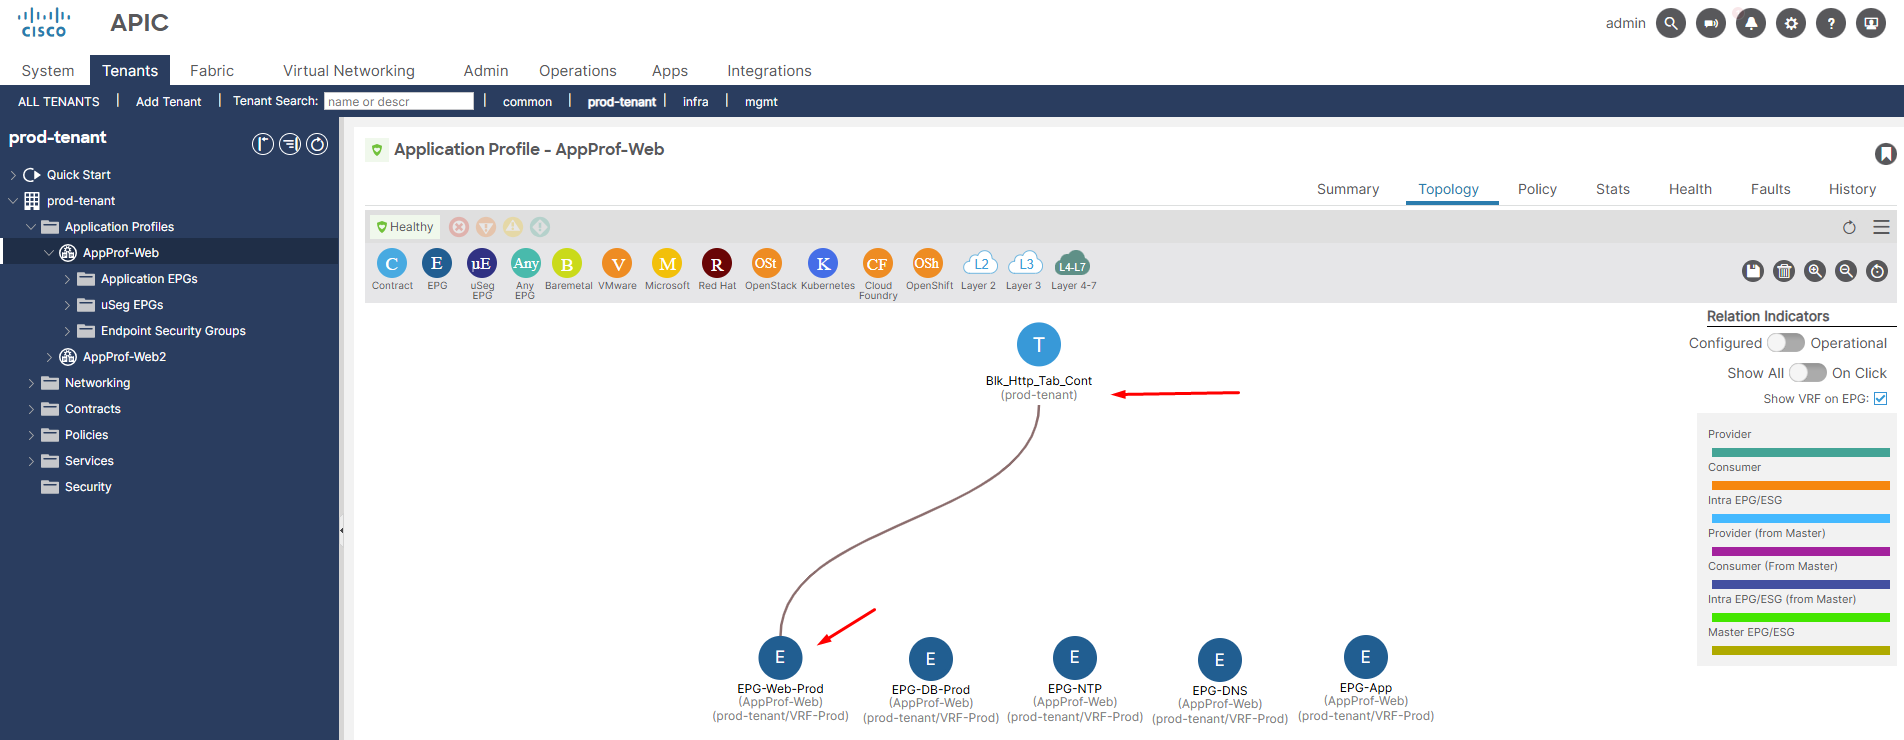
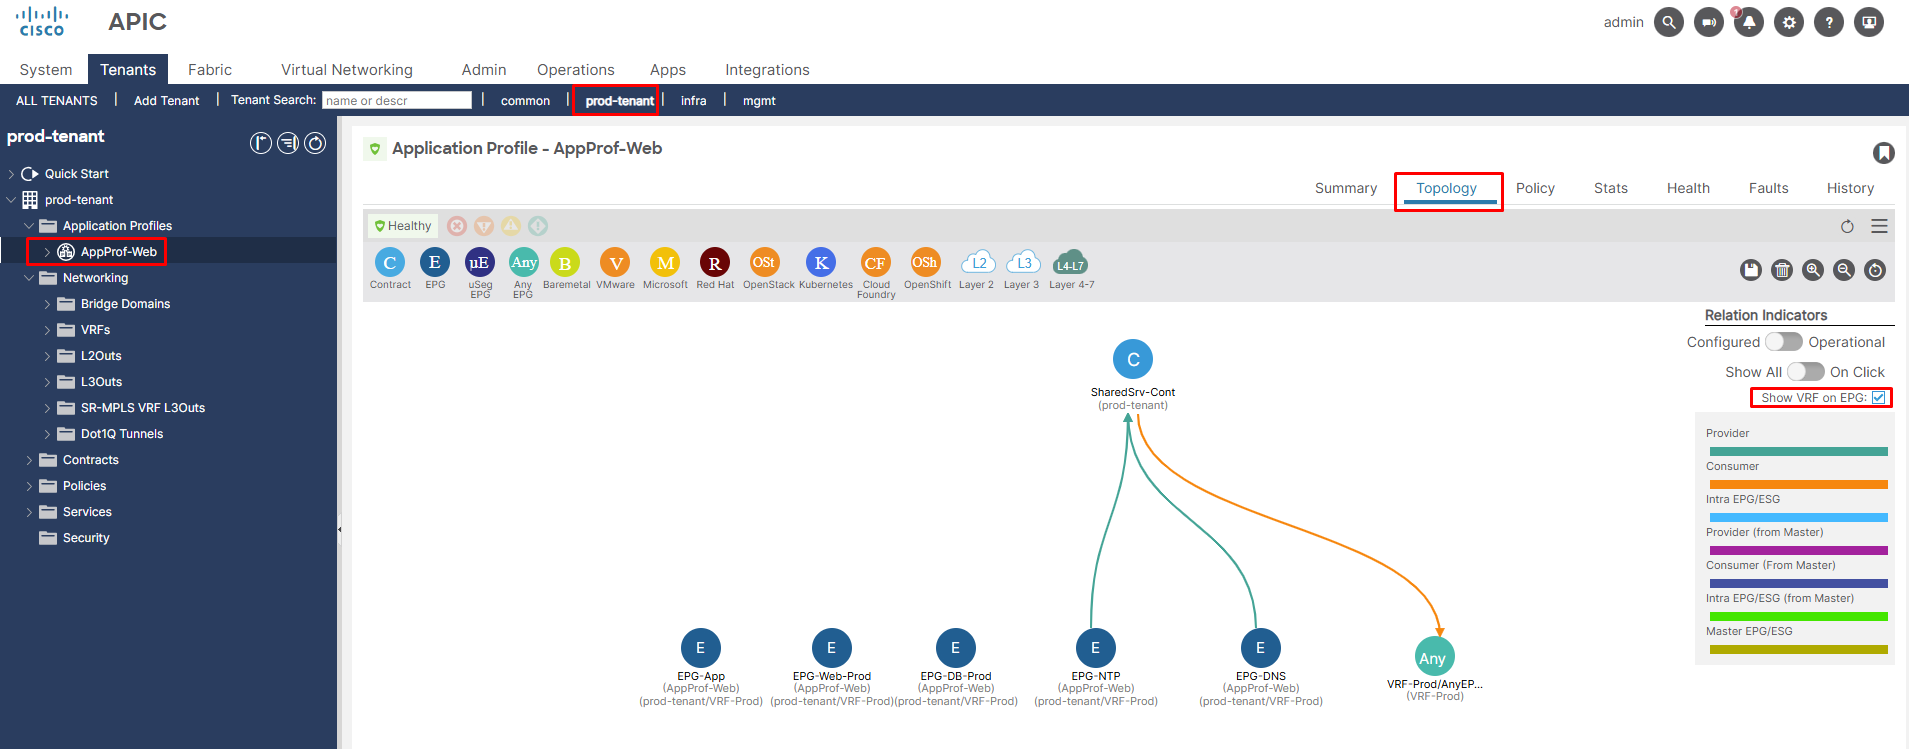
<p>Under the “Application Profile” and “Topology” tabs, you can view the graphical representation of the relationship between EPGs and Contracts.
Below Figure 6 illustrates how DNS and NTP services are shared for all EPGs within the VRF using vzAny.</p>

<p><strong>Note</strong> the checkbox on the right, “Show VRF in EPG,” which helps us identify which VRF a particular EPG belongs to.</p>

<p><a href="/images/aci_contracts/4.png" target="new" title="click here to see the full sized image"><img src="/images/aci_contracts/4.png" alt="ACI-vzAny4" /></a></p>

<p>Figure 7. Contract relationship: vzAny consumes services provided by DNS and NTP EPGs.</p>

<p><strong>Please Note:</strong>
External EPGs that are associated with L3Outs and are part of a VRF are also included in the vzAny logical group.</p>

<p><strong>Limitations of vzAny:</strong><br />
<strong>1. VRF Scope -</strong> vzAny is limited to a single VRF. It cannot directly apply contracts to EPGs/ESGs in other VRFs without additional configuration (e.g., contract export or shared services).<br />
<strong>2. No Taboo Contracts -</strong> vzAny does not support taboo contracts, which are used to deny specific traffic for individual EPGs.<br />
<strong>3. Over-Permissiveness Risk -</strong> Applying contracts to vzAny affects all EPGs/ESGs in the VRF, which may lead to unintended traffic flows if not carefully planned.<br />
<strong>4. Not for Granular Control -</strong> For specific EPG-to-EPG policies, individual contracts are preferred over vzAny.</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="preferred-groups-when-to-unenforce-policy-in-aci">Preferred Groups: When to Unenforce Policy in ACI</h2>

<p>A Preferred Group is a VRF-level configuration that designates a subset of EPGs or ESGs within a VRF as members of a group that can communicate with each other without contracts. When an EPG or ESG is added to the Preferred Group, it can send and receive traffic to/from other Preferred Group members within the same VRF, bypassing the need for standard contracts, provided the VRF is in enforced mode. I would like to mentioned that only one group can exist per VRF.</p>

<p><strong>Limitations of Preferred Groups:</strong></p>
<ol>
  <li>Preferred Groups are limited to a single VRF.</li>
  <li>No Taboo Contract Support: Taboo contracts, which explicitly deny traffic for individual EPGs, cannot be overridden by Preferred Groups. If a taboo contract is applied to an EPG, it takes precedence.</li>
  <li>All-or-Nothing Communication, preferred Group members can communicate freely with each other for all traffic types.</li>
  <li>Not for External Connectivity: Preferred Groups do not apply to L3Out external EPGs for external connectivity; contracts are still required.</li>
  <li>Policy CAM Usage: Preferred Group rules consume Policy CAM on leaf switches, which can impact scalability in large deployments.</li>
  <li>If the VRF is unenforced, contracts are bypassed, and the Preferred Group has no effect (all EPGs/ESGs can communicate freely).</li>
</ol>

<p><a href="#top">Back to Top</a></p>

<h2 id="unenforced-vrfs-the-full-open-communication-inside-vrf">Unenforced VRFs: The Full Open Communication inside VRF</h2>

<p>An unenforced VRF is a VRF configuration in Cisco ACI where the policy enforcement is disabled.</p>

<p><strong>In this mode:</strong></p>
<ol>
  <li>All EPGs and ESGs within the VRF can communicate with each other without requiring contracts.</li>
  <li>The unenforced setting applies only to intra-VRF traffic; inter-VRF communication still requires contracts and route leaking.</li>
  <li>Traffic flows freely between endpoints within the VRF.</li>
  <li>Contracts, including standard and taboo contracts, are bypassed for intra-VRF communication.</li>
  <li>Features like Preferred Groups and vzAny become irrelevant in an unenforced VRF, as all traffic is permitted.</li>
</ol>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Feature</th>
      <th style="text-align: left">Preferred group</th>
      <th style="text-align: left">vzAny</th>
      <th>Unenforced VRF</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">Scope</td>
      <td style="text-align: left">Specific EPGs/ESGs in a VRF</td>
      <td style="text-align: left">All EPGs/ESGs in a VRF</td>
      <td>All EPGs/ESGs in a VRF</td>
    </tr>
    <tr>
      <td style="text-align: left">Contract Requirement</td>
      <td style="text-align: left">No contracts needed between members.</td>
      <td style="text-align: left">Contracts required (provider/consumer)</td>
      <td>No contracts needed for any traffic</td>
    </tr>
    <tr>
      <td style="text-align: left">Granularity</td>
      <td style="text-align: left">Selective (only members communicate freely).</td>
      <td style="text-align: left">Applies to all EPGs/ESGs via contracts.</td>
      <td>No control (all traffic allowed)</td>
    </tr>
    <tr>
      <td style="text-align: left">Inter-VRF Support</td>
      <td style="text-align: left">No (requires contracts for inter-VRF).</td>
      <td style="text-align: left">Supports inter-VRF with contract export.</td>
      <td>No (VRF isolation still applies)</td>
    </tr>
    <tr>
      <td style="text-align: left">Use Case</td>
      <td style="text-align: left">Controlled open communication within VRF.</td>
      <td style="text-align: left">Simplified contract application.</td>
      <td>Fully open VRF (less secure)</td>
    </tr>
  </tbody>
</table>

<p>Table 1. Representing comparison Preferred Groups vs. vzAny vs. Unenforced VRF.</p>

<p><a href="#top">Back to Top</a></p>]]></content><author><name>Tomislav Kranjec</name></author><category term="Cisco ACI" /><category term="aci" /><category term="fabric" /><category term="leaf" /><category term="spine" /><summary type="html"><![CDATA[We recently explored the foundational elements of Cisco ACI, diving into how Tenants, VRFs, Bridge Domains, and EPGs serve as the logical building blocks for organizing your network. We saw how these components create a structured environment for applications, but that raises a critical question, how do these EPGs actually talk to each other securely? How do you define precisely what traffic is allowed, and what is denied, between different application tiers or external networks? This is where Cisco ACI Contracts come in. They are the core enforcement mechanism for defining communication policies and building a zero-trust security model within your ACI fabric. Standard Contracts: Building the ACI Security Whitelist The Contract is the core policy object in Cisco ACI that enables inter-EPG communication based on a provider-consumer model. It defines the exact, permitted traffic flows, serving as the explicit allow-list that overrides the fabric's default deny-all. A standard contract is composed of several key components: Filters are the most granular rules, specifying permitted traffic based on network attributes such as EtherType, IP, ICMPv4 and v6 Source and Destination Port/Range. Subjects are Logical containers for Filters that define the directionality of the traffic flow. It also defines the directionality of the communication using options like “Apply Both Directions” and “Reverse Filter Ports” these “Subject” options are responsible for automatically creating the necessary return path TCAM entry (ACL rule) for a connection. Scopes Settings (Application Profile, VRF, Tenant, and Global) that establish the contract’s domain, controlling how widely it can be shared and reused across the ACI environment. Application Profile scope - communication policies that are strictly internal to a single application, ensuring that the contract is not accidentally used by other applications, even in the same VRF. VRF scope - The default and most common scope for defining communication policies between EPGs that share a Layer 3 forwarding domain. This scope is used for most intra-VRF contracts. Tenant Scope - Primarily for Inter-VRF (route leaking) communication when both VRFs are in the same tenant. It allows EPGs in one VRF to consume a contract provided by an EPG in a different VRF, as long as they are in the same tenant. Global scope - Inter-Tenant contracts, where the provider and consumer are in different tenants. For contracts defined in the Common Tenant that need to be universally available (e.g., contracts for shared services like DNS/NTP). or Inter-VRF communication where the VRFs are in different tenants. Action specifies whether to permit, deny, or log the traffic (deny actions are supported in APIC Release 3.2(x) and later with EX/FX switches). As many are still struggling with ACI contract direction (Consumer to Provider and Provider to Consumer), let me reveal one secret: Consumer is the SOURCE Provider is the DESTINATION Apply your policies using this simple traffic flow rule, and you’ll get it right every time! Below figures 1 through 3 illustrate the operational behavior of the “Apply Both Directions” and “Reverse Filter Ports” settings. Figure 1. Applying contract between two EPGs. The Consumer EPG can only initiate a new session with the Provider EPG on the specified port, which in this case is TCP 22 for SSH. However, communication won’t be established because the contract is currently applied only in the Consumer-to-Provider direction, causing the necessary return traffic to be dropped. Therefore, we have two options: either create a second contract in the Provider-to-Consumer direction or use the “Apply Both Directions” option with “Reverse Filter Ports.” Since contracts utilize hardware resources on the leaf switches, I recommend using “Apply Both Directions” with “Reverse Filter Ports.” Figure 2. Feature “Apply Both Direction” Enabled. With “Apply Both Directions” (Option ON): The Consumer EPG can initiate a connection to the Provider EPG. The Provider EPG can also initiate a new, separate connection back to the Consumer EPG on the same port(s). Based on Figure 2. SRV1 and SRV2 can open SSH session to DB1 and DB2 and vice versa DB1 and DB2 can open SSH session to SRV1 and SRV2 but communication won’t be established. Figure 3. Representing establishment of SSH session from Jumphost (SRV1 and SRV2) to DB servers. Note: Contracts can be applied only on unicast traffic. Broadcast, Unknown unicast and Multicast Protocols (BUM) traffic and below listed protocols are implicitly permitted. ARP reply (unicast) DHCP v4 (prot 0x11, sport 0x44, dport 0x43) DHCP v4 (prot 0x11, sport 0x43, dport 0x44) DHCP v6 (prot 0x11, sport 0x222, dport 0x223) OSPF (prot 0x59) EIGRP (prot 0x58) PIM (prot 0x67) IGMP (prot 0x2) ND-Sol ICMPv6 (prot 0x3a dport 0x0087) ND-Advt ICMPv6 (prot 0x3a dport 0x0088) Moreover, in case of Multi-Site deployment, Cisco Multi-Site Orchestrator (MSO) creates one contract for each subject. Back to Top Taboo Contracts: ACIs Blacklist for Overriding Security Policies Taboo contracts are specialized contracts used to explicitly deny specific traffic for a single EPG. Unlike standard contracts, they are: Unidirectional - Always provided by the EPG, with no consumer relationship. Higher Priority - Evaluated before standard contracts in the hardware’s Policy CAM. Limited Scope - Applied to a single EPG to block specific traffic, such as insecure protocols. Taboo contracts are not supported with Endpoint Security Groups (ESGs). They cannot be applied to vzAny. Cisco best practices generally advise against its regular use in production environments and suggest to use standard contracts with deny action if it is needed. Example Use Case: You want to block HTTP (port 80) traffic to Web_EPG while allowing other traffic via standard contracts. Create a taboo contract Deny_HTTP_Taboo with a filter for TCP port 80 and apply it as provided by Web_EPG. Figure 4. A Taboo-Contract blocking access to HTTP (insecure TCP port 80). Back to Top vzAny Contracts: The Shortcut to allow communication inside VRF and more vzAny is a powerful construct that simplifies the application of security policies across all Endpoint Groups (EPGs) and Endpoint Security Groups (ESGs) within a Virtual Routing and Forwarding (VRF) instance. Key characteristics of vzAny: 1. VRF-Specific - vzAny is scoped to a single VRF and cannot directly apply to EPGs/ESGs in other VRFs. 2. Contract Simplification - Instead of applying a contract to each EPG/ESG individually, vzAny applies it to all EPGs/ESGs in the VRF simultaneously. Remember vzAny representing all EPGs inside VRF. 3. Provider or Consumer Role - vzAny can act as a contract provider (offering services) or consumer (accessing services), depending on the configuration. 4. Standard Contracts Only - vzAny supports standard contracts but not taboo contracts, which are limited to individual EPGs. Figure 5. Representation of applying the contract per EPG. Figure 6. Representing of applying the contract to vzAny. Under the “Application Profile” and “Topology” tabs, you can view the graphical representation of the relationship between EPGs and Contracts. Below Figure 6 illustrates how DNS and NTP services are shared for all EPGs within the VRF using vzAny. Note the checkbox on the right, “Show VRF in EPG,” which helps us identify which VRF a particular EPG belongs to. Figure 7. Contract relationship: vzAny consumes services provided by DNS and NTP EPGs. Please Note: External EPGs that are associated with L3Outs and are part of a VRF are also included in the vzAny logical group. Limitations of vzAny: 1. VRF Scope - vzAny is limited to a single VRF. It cannot directly apply contracts to EPGs/ESGs in other VRFs without additional configuration (e.g., contract export or shared services). 2. No Taboo Contracts - vzAny does not support taboo contracts, which are used to deny specific traffic for individual EPGs. 3. Over-Permissiveness Risk - Applying contracts to vzAny affects all EPGs/ESGs in the VRF, which may lead to unintended traffic flows if not carefully planned. 4. Not for Granular Control - For specific EPG-to-EPG policies, individual contracts are preferred over vzAny. Back to Top Preferred Groups: When to Unenforce Policy in ACI A Preferred Group is a VRF-level configuration that designates a subset of EPGs or ESGs within a VRF as members of a group that can communicate with each other without contracts. When an EPG or ESG is added to the Preferred Group, it can send and receive traffic to/from other Preferred Group members within the same VRF, bypassing the need for standard contracts, provided the VRF is in enforced mode. I would like to mentioned that only one group can exist per VRF. Limitations of Preferred Groups: Preferred Groups are limited to a single VRF. No Taboo Contract Support: Taboo contracts, which explicitly deny traffic for individual EPGs, cannot be overridden by Preferred Groups. If a taboo contract is applied to an EPG, it takes precedence. All-or-Nothing Communication, preferred Group members can communicate freely with each other for all traffic types. Not for External Connectivity: Preferred Groups do not apply to L3Out external EPGs for external connectivity; contracts are still required. Policy CAM Usage: Preferred Group rules consume Policy CAM on leaf switches, which can impact scalability in large deployments. If the VRF is unenforced, contracts are bypassed, and the Preferred Group has no effect (all EPGs/ESGs can communicate freely). Back to Top Unenforced VRFs: The Full Open Communication inside VRF An unenforced VRF is a VRF configuration in Cisco ACI where the policy enforcement is disabled. In this mode: All EPGs and ESGs within the VRF can communicate with each other without requiring contracts. The unenforced setting applies only to intra-VRF traffic; inter-VRF communication still requires contracts and route leaking. Traffic flows freely between endpoints within the VRF. Contracts, including standard and taboo contracts, are bypassed for intra-VRF communication. Features like Preferred Groups and vzAny become irrelevant in an unenforced VRF, as all traffic is permitted. Feature Preferred group vzAny Unenforced VRF Scope Specific EPGs/ESGs in a VRF All EPGs/ESGs in a VRF All EPGs/ESGs in a VRF Contract Requirement No contracts needed between members. Contracts required (provider/consumer) No contracts needed for any traffic Granularity Selective (only members communicate freely). Applies to all EPGs/ESGs via contracts. No control (all traffic allowed) Inter-VRF Support No (requires contracts for inter-VRF). Supports inter-VRF with contract export. No (VRF isolation still applies) Use Case Controlled open communication within VRF. Simplified contract application. Fully open VRF (less secure) Table 1. Representing comparison Preferred Groups vs. vzAny vs. Unenforced VRF. Back to Top]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/aci_contracts/1.png" /><media:content medium="image" url="https://tomislavk.blog/images/aci_contracts/1.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Cisco ACI’s Core Building Blocks: Tenants to EPGs Explained</title><link href="https://tomislavk.blog/aci/aci-core-build/" rel="alternate" type="text/html" title="Cisco ACI’s Core Building Blocks: Tenants to EPGs Explained" /><published>2025-06-16T00:00:00+04:00</published><updated>2025-06-16T00:00:00+04:00</updated><id>https://tomislavk.blog/aci/aci-core-build</id><content type="html" xml:base="https://tomislavk.blog/aci/aci-core-build/"><![CDATA[<p>In the world of modern data centers, Cisco Application Centric Infrastructure (ACI) stands out as a powerful solution for network automation, policy enforcement, and application agility.
<!-- excerpt --></p>

<p>
This post will demystify the core building blocks of Cisco ACI, guiding you through the concepts of Tenants, VRFs (Virtual Routing and Forwarding), Bridge Domains, Application Profiles, and Endpoint Groups (EPGs). By the end of this explanation, you'll have a clear understanding of how these elements work together to form a robust and flexible network fabric, enabling you to design and implement ACI solutions with confidence. Let's dive in!
</p>

<p><a href="/images/aci_building_blocks/2-0.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/2-0.png" alt="ACI-Tenant" /></a></p>

<p>Figure 1. Workflow of Tenant to EPG deployment.</p>

<h2 id="understanding-the-tenant-the-administrative-boundary">Understanding the Tenant: The Administrative Boundary</h2>

<p>In the ACI object model, the Tenant (fvTenant) is the root of a policy tree for a given set of configurations. All subsequent networking objects (VRF, BD, EPG, etc.) are children of a Tenant.</p>

<p><strong>Default Tenants:</strong> When you initialize an ACI fabric, three default tenants are automatically created:</p>

<p><strong>common:</strong> This tenant is for shared resources that can be accessed by all other tenants. Common uses include shared Layer 3 Out (L3Out) connections to external networks, common services like DNS or DHCP, and shared Layer 4-7 services (e.g., firewalls, load balancers). Objects in the common tenant can be consumed by other tenants via contracts.</p>

<p><strong>infra (Infrastructure):</strong> This tenant is used for internal ACI fabric communications. It contains policies related to fabric discovery, image management, VXLAN overlay, and other underlying infrastructure functions. It’s generally not directly configured by users unless specifically instructed by Cisco for advanced scenarios like Multi-Pod or Multi-Site deployments.</p>

<p><strong>mgmt (Management):</strong> This tenant is dedicated to managing the ACI fabric itself. It defines policies for in-band and out-of-band management access to the APIC controllers and fabric switches. No Direct Network Construct: A Tenant itself doesn’t map directly to a traditional network construct like a VLAN, VRF, or physical interface.</p>

<p><strong>Globally Unique Names:</strong> Tenant names must be globally unique across the ACI fabric.</p>

<p><a href="/images/aci_building_blocks/2.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/2.png" alt="ACI-Tenant" /></a></p>

<p>Figure 2. Tenant deployment workflow.</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="vrf-virtual-routing-and-forwarding-the-layer-3-isolation-domain">VRF (Virtual Routing and Forwarding): The Layer 3 Isolation Domain</h2>

<p>Layer 3 Isolation: The fundamental purpose of a VRF in ACI, just like in traditional networking, is to provide Layer 3 isolation. Each VRF has its own independent routing table, IP address space, and set of routing protocols. This means that traffic within one VRF cannot directly communicate with traffic in another VRF unless explicitly configured to do so (e.g., via a firewall or inter-VRF routing policies).</p>

<p><strong>Routing Instance:</strong> A VRF is essentially a virtual routing instance. It holds the routing information (routes, ARP/ND entries) for the subnets and endpoints associated with it.</p>

<p><strong>Tenant Scoped:</strong> A VRF is always contained within a Tenant. It’s a child object of a Tenant (fvCtx in the ACI object model). This means that a VRF belongs to a specific administrative domain and its policies are managed under that tenant.</p>

<p><strong>Policy Control Enforcement Preference:</strong></p>

<ul>
  <li>“Enforced” (Default and Recommended): This means that all communication between EPGs within this VRF (or between an EPG in this VRF and an external network) requires a Contract.</li>
  <li>“Unenforced”: This setting implies that all EPGs within this VRF can communicate freely with each other by default, without the need for explicit Contracts. While it simplifies initial setup, it bypasses ACI’s micro-segmentation capabilities and is generally discouraged for production environments where granular security is a requirement.</li>
</ul>

<p><strong>Preferred Group:</strong> setting, enabled at the VRF level, allows all EPGs within that VRF to communicate with each other by default if they are part of the preferred group.</p>

<p><a href="/images/aci_building_blocks/3.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/3.png" alt="ACI-VRF" /></a></p>

<p>Figure 3. VRF deployment workflow</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="bridge-domain-bd-the-layer-2-forwarding-domain">Bridge Domain (BD): The Layer 2 Forwarding Domain</h2>

<p>In Cisco ACI, a Bridge Domain (BD) is a critical logical construct that represents a Layer 2 forwarding domain. It’s the ACI equivalent of a traditional VLAN or broadcast domain, but with significantly enhanced capabilities and policy integration.</p>

<p><a href="/images/aci_building_blocks/4.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/4.png" alt="ACI-BD" /></a></p>

<p>Figure 4. First step in Bridge Domain deployment.</p>

<p><a href="/images/aci_building_blocks/4-1.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/4-1.png" alt="ACI-BD" /></a></p>

<p>Figure 5. Second step in Bridge Domain deployment.</p>

<p><a href="/images/aci_building_blocks/4-2.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/4-2.png" alt="ACI-BD" /></a></p>

<p>Figure 6. Third step in Bridge Domain deployment.</p>

<p><a href="/images/aci_building_blocks/4-3.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/4-3.png" alt="ACI-BD" /></a></p>

<p>Figure 7. Bridge Domain L2 features.</p>

<p><strong>Advertise Host Routes:</strong> By advertising a precise /32 (or /128) route for each individual endpoint, external routers learn the exact leaf switch (and pod/site) where the endpoint resides. This directs traffic directly to the optimal entry point into the ACI fabric.</p>

<p><strong>L2 Unknown Unicast Handling:</strong> This setting defines how the ACI fabric handles unknown unicast traffic within the Bridge Domain:</p>
<ul>
  <li>
    <p>Hardware Proxy (Default and Recommended): This is the most efficient and scalable method. When a leaf switch receives an unknown unicast frame, it doesn’t flood it everywhere. Instead, it sends the frame to a spine proxy. The spine acts as a central lookup point, and if it knows the destination MAC, it forwards the frame directly to the correct leaf. If the MAC is unknown to the spine, only then does the spine flood it to relevant leaves. This significantly reduces flood domains.</p>
  </li>
  <li>
    <p>Flood: This behaves like traditional Ethernet. Unknown unicast frames are flooded to all leaf switches that have an endpoint associated with this Bridge Domain. This can be inefficient and generate unnecessary traffic, especially in large environments.</p>
  </li>
</ul>

<p><strong>Optimize ARP Flooding:</strong> This option, when enabled, means that the ACI fabric will proxy ARP requests for known MAC addresses instead of flooding them. This reduces broadcast traffic.</p>

<p><strong>Limit local IP learning to BD/EPG subnets:</strong> Restrict IP Learning: The ACI leaf switches connected to this Bridge Domain will only learn IP addresses for endpoints that fall within the explicitly defined IP subnets configured under that particular Bridge Domain, or the subnets defined within the EPGs that reside within that BD. It will ignore Out-of-Subnet IPs.</p>

<p><a href="/images/aci_building_blocks/4-4.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/4-4.png" alt="ACI-BD" /></a></p>

<p>Figure 8. Bridge Domain L3 features.</p>

<p><strong>IP Unicast Routing (Enabled/Disabled):</strong></p>
<ul>
  <li>If enabled, the ACI fabric will provide a distributed default gateway (Anycast Gateway) for any IP subnets defined within this Bridge Domain. This means the Layer 3 routing for endpoints in this BD is handled directly by the ACI leaf switches. This is the typical configuration for routed networks.</li>
  <li>If disabled, the ACI fabric will not provide a default gateway for the subnets in this BD. This is often used for: Networks where an external router or firewall provides the default gateway. In such cases, the ACI fabric simply acts as a transparent Layer 2 forwarding plane.</li>
</ul>

<p><a href="#top">Back to Top</a></p>

<p><strong><span style="color:#074080; font-size:16.0pt;" id="section4">3.1 Subnet Configuration within a Bridge Domain: Defining IP Address Space &amp; Reachability.</span></strong></p>

<p>Each Bridge Domain can have one or more IP subnets associated with it. These subnets represent the IP address space for the endpoints connected to the Bridge Domain. Additionally, subnets can also be created directly under an EPG, but their purpose in that context is different: it facilitates Route Leaking and Shared Services between VRFs/Tenants with policy granularity.</p>

<p><a href="/images/aci_building_blocks/4-6.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/4-6.png" alt="ACI-Sub" /></a></p>

<p>Table 1. Comparing Subnets: Bridge Domain vs. EPG.</p>

<p><a href="/images/aci_building_blocks/4-5.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/4-5.png" alt="ACI-Sub" /></a></p>

<p>Figure 9. Subnet deployment within specific Bridge Domain.</p>

<p><strong>Treat as Virtual IP address:</strong> Special handling for HA (Active/Standby) external device VIPs, ensuring proper learning and failover during HA events.</p>

<p><strong>Make this IP address primary</strong> Designates a preferred source IP for the BD’s own control plane traffic when multiple subnets exist within this BD.</p>

<p><strong>Advertised Externally:</strong> Advertises individual /32 (or /128) host routes for learned endpoints to external networks via L3Outs, optimizing traffic paths and VM mobility.</p>

<p><strong>Shared Between VRFs:</strong> This option allows the subnet to be “leaked” and reachable by other VRFs within the same or different Tenants, usually in conjunction with Contracts for inter-VRF communication.</p>

<p><strong>No Default SVI Gateway:</strong> Disables ACI’s pervasive gateway for this specific subnet (useful for secondary IPs or external gateways).</p>

<p><strong>IP Data Plane Learning</strong> Enables dynamic learning of endpoint IP addresses by observing network traffic (typically enabled for general endpoints).</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="application-profile-ap-the-application-logical-container">Application Profile (AP): The Application Logical Container</h2>

<p>In Cisco ACI, an Application Profile (AP) is a logical container that groups together all the Endpoint Groups (EPGs) and Contracts needed to deploy a specific application or service. It provides a higher-level abstraction for managing application-centric policies within the ACI fabric. The primary purpose of an Application Profile is to shift the focus from network-centric configuration to application-centric configuration. Instead of configuring network policies based on VLANs or subnets, you define policies based on the application components and their communication requirements.</p>

<p><a href="/images/aci_building_blocks/5.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/5.png" alt="ACI-AppProf" /></a></p>

<p>Figure 10. Deployment of Application profile.</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="epg-endpoint-group-the-granular-policy-enforcement-point">EPG (Endpoint Group): The Granular Policy Enforcement Point</h2>

<p>An EPG is the smallest and most critical unit to which policy (Contracts) is applied. If two endpoints are in the same EPG, they can communicate by default (unless otherwise restricted by other policies like Preferred Group or micro-segmentation). If they are in different EPGs, communication between them is blocked by default, and a Contract is required to permit specific traffic flows. This is ACI’s core “whitelist” security model. EPGs support micro-segmentation through features like intra-EPG isolation, which prevents communication between endpoints within the same EPG if required.</p>

<p><strong>Type Of EPGs:</strong></p>
<ul>
  <li>“Classic” EPG which is representing endpoints, they can be physical servers, virtual machines, network-attached storage devices, or even clients on the internet.</li>
  <li>Layer 2 external outside network instance endpoint groups (l2extInstP).</li>
  <li>Layer 3 external outside network instance endpoint groups (l3extInstP).</li>
  <li>Management Endpoints groups (mgmtOoB, mgmtInB) are used for securing access to the ACI fabric’s management plane, either through a dedicated out-of-band management network or via in-band access within the fabric itself.</li>
</ul>

<p><a href="/images/aci_building_blocks/5.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/5.png" alt="ACI-EPG" /></a></p>

<p>Figure 11. Deployment of EPG under application profile.</p>

<p>To provision EPG on the port/switch we have to methods:</p>
<ul>
  <li><strong>Static Ports:</strong> Explicitly links an EPG to a specific physical interface.</li>
  <li><strong>Static Leafs (via AAEP):</strong> Links an EPG to a logical group of interfaces defined by an AAEP, effectively pushing the EPG’s VLAN to all ports associated with that AAEP.</li>
</ul>

<p><a href="/images/aci_building_blocks/5-1.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/5-1.png" alt="ACI-EPG" /></a></p>

<p>Figure 12. EPG to Leaf Port Static Assignment.</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="endpoint-security-groups-esgs-decoupling-security-from-forwarding">Endpoint Security Groups (ESGs): Decoupling Security from Forwarding</h2>

<p>Decoupling Security from Forwarding: This is the core architectural shift and primary benefit of ESGs compared to EPGs. EPGs combine both forwarding (VLAN/VXLAN binding, BD association) and security, whereas ESGs aim to provide security policy based on attributes, independent of the underlying network forwarding.</p>

<p><a href="/images/aci_building_blocks/6.png" target="new" title="click here to see the full sized image"><img src="/images/aci_building_blocks/6.png" alt="ACI-ESG" /></a></p>

<p>Figure 13. Defining Endpoint Security Groups (ESGs) for Policy Decoupling.</p>

<p>After defining your ESGs, you will create Contracts as usual.
Associate the ESG as a Provider or Consumer of the contract, just like you would with EPGs.</p>

<p><strong>Remember:</strong> Contracts typically apply ESG-to-ESG, ESG-to-L3Out External EPG, ESG-to-L2Out External EPG or ESG-to-vzAny.</p>

<p>By using ESGs, ACI provides an additional layer of flexibility and powerful tools for defining and enforcing security policies, especially beneficial in complex and evolving data center environments.</p>

<p><a href="#top">Back to Top</a></p>]]></content><author><name>Tomislav Kranjec</name></author><category term="ACI" /><category term="aci" /><category term="fabric" /><category term="leaf" /><category term="spine" /><summary type="html"><![CDATA[In the world of modern data centers, Cisco Application Centric Infrastructure (ACI) stands out as a powerful solution for network automation, policy enforcement, and application agility. This post will demystify the core building blocks of Cisco ACI, guiding you through the concepts of Tenants, VRFs (Virtual Routing and Forwarding), Bridge Domains, Application Profiles, and Endpoint Groups (EPGs). By the end of this explanation, you'll have a clear understanding of how these elements work together to form a robust and flexible network fabric, enabling you to design and implement ACI solutions with confidence. Let's dive in! Figure 1. Workflow of Tenant to EPG deployment. Understanding the Tenant: The Administrative Boundary In the ACI object model, the Tenant (fvTenant) is the root of a policy tree for a given set of configurations. All subsequent networking objects (VRF, BD, EPG, etc.) are children of a Tenant. Default Tenants: When you initialize an ACI fabric, three default tenants are automatically created: common: This tenant is for shared resources that can be accessed by all other tenants. Common uses include shared Layer 3 Out (L3Out) connections to external networks, common services like DNS or DHCP, and shared Layer 4-7 services (e.g., firewalls, load balancers). Objects in the common tenant can be consumed by other tenants via contracts. infra (Infrastructure): This tenant is used for internal ACI fabric communications. It contains policies related to fabric discovery, image management, VXLAN overlay, and other underlying infrastructure functions. It’s generally not directly configured by users unless specifically instructed by Cisco for advanced scenarios like Multi-Pod or Multi-Site deployments. mgmt (Management): This tenant is dedicated to managing the ACI fabric itself. It defines policies for in-band and out-of-band management access to the APIC controllers and fabric switches. No Direct Network Construct: A Tenant itself doesn’t map directly to a traditional network construct like a VLAN, VRF, or physical interface. Globally Unique Names: Tenant names must be globally unique across the ACI fabric. Figure 2. Tenant deployment workflow. Back to Top VRF (Virtual Routing and Forwarding): The Layer 3 Isolation Domain Layer 3 Isolation: The fundamental purpose of a VRF in ACI, just like in traditional networking, is to provide Layer 3 isolation. Each VRF has its own independent routing table, IP address space, and set of routing protocols. This means that traffic within one VRF cannot directly communicate with traffic in another VRF unless explicitly configured to do so (e.g., via a firewall or inter-VRF routing policies). Routing Instance: A VRF is essentially a virtual routing instance. It holds the routing information (routes, ARP/ND entries) for the subnets and endpoints associated with it. Tenant Scoped: A VRF is always contained within a Tenant. It’s a child object of a Tenant (fvCtx in the ACI object model). This means that a VRF belongs to a specific administrative domain and its policies are managed under that tenant. Policy Control Enforcement Preference: “Enforced” (Default and Recommended): This means that all communication between EPGs within this VRF (or between an EPG in this VRF and an external network) requires a Contract. “Unenforced”: This setting implies that all EPGs within this VRF can communicate freely with each other by default, without the need for explicit Contracts. While it simplifies initial setup, it bypasses ACI’s micro-segmentation capabilities and is generally discouraged for production environments where granular security is a requirement. Preferred Group: setting, enabled at the VRF level, allows all EPGs within that VRF to communicate with each other by default if they are part of the preferred group. Figure 3. VRF deployment workflow Back to Top Bridge Domain (BD): The Layer 2 Forwarding Domain In Cisco ACI, a Bridge Domain (BD) is a critical logical construct that represents a Layer 2 forwarding domain. It’s the ACI equivalent of a traditional VLAN or broadcast domain, but with significantly enhanced capabilities and policy integration. Figure 4. First step in Bridge Domain deployment. Figure 5. Second step in Bridge Domain deployment. Figure 6. Third step in Bridge Domain deployment. Figure 7. Bridge Domain L2 features. Advertise Host Routes: By advertising a precise /32 (or /128) route for each individual endpoint, external routers learn the exact leaf switch (and pod/site) where the endpoint resides. This directs traffic directly to the optimal entry point into the ACI fabric. L2 Unknown Unicast Handling: This setting defines how the ACI fabric handles unknown unicast traffic within the Bridge Domain: Hardware Proxy (Default and Recommended): This is the most efficient and scalable method. When a leaf switch receives an unknown unicast frame, it doesn’t flood it everywhere. Instead, it sends the frame to a spine proxy. The spine acts as a central lookup point, and if it knows the destination MAC, it forwards the frame directly to the correct leaf. If the MAC is unknown to the spine, only then does the spine flood it to relevant leaves. This significantly reduces flood domains. Flood: This behaves like traditional Ethernet. Unknown unicast frames are flooded to all leaf switches that have an endpoint associated with this Bridge Domain. This can be inefficient and generate unnecessary traffic, especially in large environments. Optimize ARP Flooding: This option, when enabled, means that the ACI fabric will proxy ARP requests for known MAC addresses instead of flooding them. This reduces broadcast traffic. Limit local IP learning to BD/EPG subnets: Restrict IP Learning: The ACI leaf switches connected to this Bridge Domain will only learn IP addresses for endpoints that fall within the explicitly defined IP subnets configured under that particular Bridge Domain, or the subnets defined within the EPGs that reside within that BD. It will ignore Out-of-Subnet IPs. Figure 8. Bridge Domain L3 features. IP Unicast Routing (Enabled/Disabled): If enabled, the ACI fabric will provide a distributed default gateway (Anycast Gateway) for any IP subnets defined within this Bridge Domain. This means the Layer 3 routing for endpoints in this BD is handled directly by the ACI leaf switches. This is the typical configuration for routed networks. If disabled, the ACI fabric will not provide a default gateway for the subnets in this BD. This is often used for: Networks where an external router or firewall provides the default gateway. In such cases, the ACI fabric simply acts as a transparent Layer 2 forwarding plane. Back to Top 3.1 Subnet Configuration within a Bridge Domain: Defining IP Address Space &amp; Reachability. Each Bridge Domain can have one or more IP subnets associated with it. These subnets represent the IP address space for the endpoints connected to the Bridge Domain. Additionally, subnets can also be created directly under an EPG, but their purpose in that context is different: it facilitates Route Leaking and Shared Services between VRFs/Tenants with policy granularity. Table 1. Comparing Subnets: Bridge Domain vs. EPG. Figure 9. Subnet deployment within specific Bridge Domain. Treat as Virtual IP address: Special handling for HA (Active/Standby) external device VIPs, ensuring proper learning and failover during HA events. Make this IP address primary Designates a preferred source IP for the BD’s own control plane traffic when multiple subnets exist within this BD. Advertised Externally: Advertises individual /32 (or /128) host routes for learned endpoints to external networks via L3Outs, optimizing traffic paths and VM mobility. Shared Between VRFs: This option allows the subnet to be “leaked” and reachable by other VRFs within the same or different Tenants, usually in conjunction with Contracts for inter-VRF communication. No Default SVI Gateway: Disables ACI’s pervasive gateway for this specific subnet (useful for secondary IPs or external gateways). IP Data Plane Learning Enables dynamic learning of endpoint IP addresses by observing network traffic (typically enabled for general endpoints). Back to Top Application Profile (AP): The Application Logical Container In Cisco ACI, an Application Profile (AP) is a logical container that groups together all the Endpoint Groups (EPGs) and Contracts needed to deploy a specific application or service. It provides a higher-level abstraction for managing application-centric policies within the ACI fabric. The primary purpose of an Application Profile is to shift the focus from network-centric configuration to application-centric configuration. Instead of configuring network policies based on VLANs or subnets, you define policies based on the application components and their communication requirements. Figure 10. Deployment of Application profile. Back to Top EPG (Endpoint Group): The Granular Policy Enforcement Point An EPG is the smallest and most critical unit to which policy (Contracts) is applied. If two endpoints are in the same EPG, they can communicate by default (unless otherwise restricted by other policies like Preferred Group or micro-segmentation). If they are in different EPGs, communication between them is blocked by default, and a Contract is required to permit specific traffic flows. This is ACI’s core “whitelist” security model. EPGs support micro-segmentation through features like intra-EPG isolation, which prevents communication between endpoints within the same EPG if required. Type Of EPGs: “Classic” EPG which is representing endpoints, they can be physical servers, virtual machines, network-attached storage devices, or even clients on the internet. Layer 2 external outside network instance endpoint groups (l2extInstP). Layer 3 external outside network instance endpoint groups (l3extInstP). Management Endpoints groups (mgmtOoB, mgmtInB) are used for securing access to the ACI fabric’s management plane, either through a dedicated out-of-band management network or via in-band access within the fabric itself. Figure 11. Deployment of EPG under application profile. To provision EPG on the port/switch we have to methods: Static Ports: Explicitly links an EPG to a specific physical interface. Static Leafs (via AAEP): Links an EPG to a logical group of interfaces defined by an AAEP, effectively pushing the EPG’s VLAN to all ports associated with that AAEP. Figure 12. EPG to Leaf Port Static Assignment. Back to Top Endpoint Security Groups (ESGs): Decoupling Security from Forwarding Decoupling Security from Forwarding: This is the core architectural shift and primary benefit of ESGs compared to EPGs. EPGs combine both forwarding (VLAN/VXLAN binding, BD association) and security, whereas ESGs aim to provide security policy based on attributes, independent of the underlying network forwarding. Figure 13. Defining Endpoint Security Groups (ESGs) for Policy Decoupling. After defining your ESGs, you will create Contracts as usual. Associate the ESG as a Provider or Consumer of the contract, just like you would with EPGs. Remember: Contracts typically apply ESG-to-ESG, ESG-to-L3Out External EPG, ESG-to-L2Out External EPG or ESG-to-vzAny. By using ESGs, ACI provides an additional layer of flexibility and powerful tools for defining and enforcing security policies, especially beneficial in complex and evolving data center environments. Back to Top]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/aci_building_blocks/1.png" /><media:content medium="image" url="https://tomislavk.blog/images/aci_building_blocks/1.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Understanding Cisco ACI Access Policies: A Practical Guide</title><link href="https://tomislavk.blog/aci/aci-access-polices/" rel="alternate" type="text/html" title="Understanding Cisco ACI Access Policies: A Practical Guide" /><published>2025-05-28T00:00:00+04:00</published><updated>2025-05-28T00:00:00+04:00</updated><id>https://tomislavk.blog/aci/aci-access-polices</id><content type="html" xml:base="https://tomislavk.blog/aci/aci-access-polices/"><![CDATA[<p>Understanding Cisco ACI Access Policies doesn’t have to be complicated. This practical guide simplifies the core concepts and clearly shows you what you need to know.
<!-- excerpt --></p>

<p>
Secure and controlled access is fundamental to any network. This guide walks you through both the essentials and more advanced topics of Cisco ACI Access Policies, demonstrating how to apply them effectively in your environment and designs.
</p>

<h2 id="the-end-to-end-workflow-for-cisco-aci-access-policy-deployment">The End-to-End Workflow for Cisco ACI Access Policy Deployment</h2>

<p>Cisco Application Centric Infrastructure (ACI) redefines network management with its policy-driven automation, moving away from traditional device-by-device configurations. At the heart of this transformative approach lies Access Policies, which dictate how physical network devices connect to the ACI fabric and how virtual and physical workloads access network services.</p>

<p><strong><span style="font-size:18.0pt;" id="section2">1.1. Interface Policies Configuration Workflow.</span></strong></p>

<ul>
  <li>
    <p><strong>VLAN Pools</strong> A VLAN Pool defines a range (or multiple ranges) of VLAN IDs that are permitted for use on leaf switch ports for EPG encapsulation. It doesn’t provision the VLANs themselves but rather reserves them for use.</p>
  </li>
  <li><strong>Domains and Domain Types</strong> Purpose: Domains act as a bridge, linking VLAN Pools with policies and the infrastructure. They define the scope where a particular VLAN pool can be utilized and by what type of entity.
    <ol>
      <li>
        <p>Physical Domains integrate bare-metal servers, physical appliances (e.g., firewalls, load balancers, non-virtualized servers), or other physical devices directly connected to ACI leaf ports.</p>
      </li>
      <li>
        <p>Fibre Channel Domains are primarily used for integrating Fibre Channel over Ethernet (FCoE) storage networks with the ACI fabric. This allows the ACI fabric to act as a converged network that carries both IP and FCoE traffic.</p>
      </li>
      <li>
        <p>External L3 Domains connect the ACI fabric to external Layer 3 (routed) networks or traditional routers outside the ACI fabric (Used by L3OUT).</p>
      </li>
      <li>
        <p>External Bridge Domains connect the ACI fabric to external Layer 2 (bridged) networks or switches outside the ACI fabric. This is used when you need to extend Layer 2 segments from the ACI fabric to external devices without routing (Used by L2OUT).</p>
      </li>
    </ol>
  </li>
  <li><strong>Attachable Access Entity Profile (AAEP)</strong> The AAEP effectively defines which VLANs are allowed on an interface or group of interfaces. It does this by referencing Domains, which in turn reference VLAN Pools. If we compare with old fashion switch configuration it should be
    <div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code> switchport trunk allowed vlan
</code></pre></div>    </div>
    <p><strong>Common Scenarios for AAEP Scope/Design:</strong></p>
    <ol>
      <li>
        <p>One-to-one with Domains: Often, you’ll create an AAEP for each type of domain (Physical AAEP,   1.VMM AAEP, L3Out AAEP, L2Out AAEP, FCoE AAEP) to clearly separate their respective VLAN pools and interface associations.</p>
      </li>
      <li>
        <p>Functional Grouping: You might create AAEPs based on functional groups of ports, e.g., “ServerFarm_AAEP” that encompasses all necessary domains (physical and VMM) and VLANs for server connectivity.</p>
      </li>
    </ol>
  </li>
  <li><strong>Interface Policy Group (IPG)</strong> acts as a collection point for individual “interface policies.” These individual policies define specific Layer 1 or Layer 2 parameters for a port.</li>
</ul>

<p><strong>Key Interface Policy Group Policies are:</strong></p>
<ul>
  <li>Link Level Policy (speed, duplex, auto-negotiation).</li>
  <li>CDP (Cisco Discovery Protocol) Policy (enable/disable).</li>
  <li>LLDP (Link Layer Discovery Protocol) Policy (enable/disable).</li>
  <li>LACP Policy (for Port Channels: active, passive, on, port priority).</li>
  <li>Storm Control Policy control Broadcast, Unknown Unicast, and Multicast (BUM).</li>
  <li>MCP (Mis-Cabling Protocol) Policy.</li>
  <li>Spanning Tree related policies (BPDU Guard/Filter).</li>
  <li>
    <p>L2 Interface Polices (VLAN scope Global or Port Local).</p>
  </li>
  <li><strong>Interface Profile</strong></li>
</ul>

<p align="center">
<img src="/images/aci_access_polices/2-1.png" alt="ACI-AccessPolice" title="ACI-AccessPolice" /> 
</p>
<p>Figure 1. Representing Interface Policies Configuration Flow.</p>

<p><a href="/images/aci_access_polices/2-11.png" target="new" title="click here to see the full sized image"><img src="/images/aci_access_polices/2-11.png" alt="IntProPolices" /></a></p>

<p>Figure 2. Interface Policy Configuration within the Cisco APIC UI.</p>

<p><a href="/images/aci_access_polices/2-13.png" target="new" title="click here to see the full sized image"><img src="/images/aci_access_polices/2-13.png" alt="IntProPolices" /></a></p>

<p>Figure 2.1. Interface Policy Configuration within the Cisco APIC UI.</p>

<p><a href="#top">Back to Top</a></p>

<p><strong><span style="font-size:18.0pt;" id="section3">1.2. Leaf Switches Policies Configuration Workflow.</span></strong></p>

<ul>
  <li><strong>Leaf Switches Policy Groups</strong> they control the behavior of the entire leaf switch. This allows for consistent application of switch-level configurations to multiple leaf nodes selected by a Leaf Switch Profile.</li>
</ul>

<p><strong>Key Leaf Switches Policy Groups are:</strong></p>
<ul>
  <li>Spanning Tree</li>
  <li>Monitoring polices</li>
  <li>CoPP Leaf Policy</li>
  <li>NetFlow Node Policy</li>
  <li>BFD IPv4 and IPv6 Policy</li>
</ul>

<p align="center">  
<img src="/images/aci_access_polices/2-2.png" alt="ACI-AccessPolice" title="ACI-AccessPolice" /> 
</p>
<p>Figure 3. Representing Leaf Switch Policies Configuration Flow.</p>

<p><a href="/images/aci_access_polices/2-21.png" target="new" title="click here to see the full sized image"><img src="/images/aci_access_polices/2-21.png" alt="LeafSWIntPro" /></a></p>

<p>Figure 4. Leaf Switch Policies Configuration within the Cisco APIC UI.</p>

<p align="center">
<img src="/images/aci_access_polices/2.png" alt="ACI-AccessPolice" title="ACI-AccessPolice" /> 
</p>

<p>Figure 5. Full configuration flow for interface and leaf switch polices.</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="leaf-access-port-configuration">Leaf Access Port configuration</h2>

<p><a href="/images/aci_access_polices/3-1.png" target="new" title="click here to see the full sized image"><img src="/images/aci_access_polices/3-1.png" alt="AccessPort" /></a></p>

<p>Figure 6. Implementation of an Interface Policy Group within the Cisco APIC user interface (UI).</p>

<p>After creating the Leaf Interface profile and attaching it to the Leaf Switch profile, we add specific ports under the Leaf Interface profile and select the appropriate Interface Policy Group. This approach provides reusability and simplifies automation. For Particular case we created Leaf Access Port Policy Group like below and attached to port eth1/1 inside specific Leaf Interface Profile.</p>

<p><a href="/images/aci_access_polices/3-2.png" target="new" title="click here to see the full sized image"><img src="/images/aci_access_polices/3-2.png" alt="AccessPort" /></a></p>

<p>Figure 7. Representing creation of Access port policy group and attaching to specific Leaf Interface profile.</p>

<p align="center">
<img src="/images/aci_access_polices/3.png" alt="ACI-AccessPolice" title="ACI-AccessPolice" /> 
</p>

<p>Figure 8. End to end workflow to setup access port up and running on leaf switch.</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="leaf-port-channel-pc-configuration">Leaf Port Channel (PC) configuration</h2>

<p>The foundational workflow for configuring a Port Channel in Cisco ACI closely mirrors that of a standard Access Port; however, a key distinction lies in the explicit inclusion and application of an LACP Policy within the associated Interface Policy Group, which is then specifically leveraged for the two designated physical ports on a single leaf switch to form the logical Port Channel.</p>

<p><a href="/images/aci_access_polices/4-1.png" target="new" title="click here to see the full sized image"><img src="/images/aci_access_polices/4-1.png" alt="PC" /></a></p>

<p>Figure 9. Representing creation of Port Channel policy group.</p>

<p align="center">
<img src="/images/aci_access_polices/4.png" alt="ACI-AccessPolice" title="ACI-AccessPolice" /> 
</p>

<p>Figure 10. End to end workflow to setup Port Channel (PC) up and running on leaf switch.</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="leaf-virtual-port-channel-vpc-configuration">Leaf Virtual Port Channel (vPC) configuration</h2>

<p>Virtual Port Channel (vPC) significantly enhances network resilience and operational uptime by logically combining two physical ports, each residing on a separate Cisco Nexus leaf switch, into a single, aggregated link. This innovative design provides superior high availability, as it creates active-active forwarding paths, ensuring that traffic can seamlessly continue to flow even if one of the leaf switches or an individual link experiences a failure.</p>

<p><a href="/images/aci_access_polices/6-1.png" target="new" title="click here to see the full sized image"><img src="/images/aci_access_polices/6-1.png" alt="VPCDom" /></a></p>

<p>Figure 11. Representing creation of Virtual Port Channel (vPC) policy group.</p>

<p align="center">
<img src="/images/aci_access_polices/5.png" alt="ACI-AccessPolice" title="ACI-AccessPolice" /> 
</p>
<p>Figure 12.End to end workflow to setup Virtual Port Channel (vPC) up and running on leaf switches.</p>

<p><a href="#top">Back to Top</a></p>]]></content><author><name>Tomislav Kranjec</name></author><category term="ACI" /><category term="aci" /><category term="fabric" /><category term="leaf" /><category term="spine" /><summary type="html"><![CDATA[Understanding Cisco ACI Access Policies doesn’t have to be complicated. This practical guide simplifies the core concepts and clearly shows you what you need to know. Secure and controlled access is fundamental to any network. This guide walks you through both the essentials and more advanced topics of Cisco ACI Access Policies, demonstrating how to apply them effectively in your environment and designs. The End-to-End Workflow for Cisco ACI Access Policy Deployment Cisco Application Centric Infrastructure (ACI) redefines network management with its policy-driven automation, moving away from traditional device-by-device configurations. At the heart of this transformative approach lies Access Policies, which dictate how physical network devices connect to the ACI fabric and how virtual and physical workloads access network services. 1.1. Interface Policies Configuration Workflow. VLAN Pools A VLAN Pool defines a range (or multiple ranges) of VLAN IDs that are permitted for use on leaf switch ports for EPG encapsulation. It doesn’t provision the VLANs themselves but rather reserves them for use. Domains and Domain Types Purpose: Domains act as a bridge, linking VLAN Pools with policies and the infrastructure. They define the scope where a particular VLAN pool can be utilized and by what type of entity. Physical Domains integrate bare-metal servers, physical appliances (e.g., firewalls, load balancers, non-virtualized servers), or other physical devices directly connected to ACI leaf ports. Fibre Channel Domains are primarily used for integrating Fibre Channel over Ethernet (FCoE) storage networks with the ACI fabric. This allows the ACI fabric to act as a converged network that carries both IP and FCoE traffic. External L3 Domains connect the ACI fabric to external Layer 3 (routed) networks or traditional routers outside the ACI fabric (Used by L3OUT). External Bridge Domains connect the ACI fabric to external Layer 2 (bridged) networks or switches outside the ACI fabric. This is used when you need to extend Layer 2 segments from the ACI fabric to external devices without routing (Used by L2OUT). Attachable Access Entity Profile (AAEP) The AAEP effectively defines which VLANs are allowed on an interface or group of interfaces. It does this by referencing Domains, which in turn reference VLAN Pools. If we compare with old fashion switch configuration it should be switchport trunk allowed vlan Common Scenarios for AAEP Scope/Design: One-to-one with Domains: Often, you’ll create an AAEP for each type of domain (Physical AAEP, 1.VMM AAEP, L3Out AAEP, L2Out AAEP, FCoE AAEP) to clearly separate their respective VLAN pools and interface associations. Functional Grouping: You might create AAEPs based on functional groups of ports, e.g., “ServerFarm_AAEP” that encompasses all necessary domains (physical and VMM) and VLANs for server connectivity. Interface Policy Group (IPG) acts as a collection point for individual “interface policies.” These individual policies define specific Layer 1 or Layer 2 parameters for a port. Key Interface Policy Group Policies are: Link Level Policy (speed, duplex, auto-negotiation). CDP (Cisco Discovery Protocol) Policy (enable/disable). LLDP (Link Layer Discovery Protocol) Policy (enable/disable). LACP Policy (for Port Channels: active, passive, on, port priority). Storm Control Policy control Broadcast, Unknown Unicast, and Multicast (BUM). MCP (Mis-Cabling Protocol) Policy. Spanning Tree related policies (BPDU Guard/Filter). L2 Interface Polices (VLAN scope Global or Port Local). Interface Profile Figure 1. Representing Interface Policies Configuration Flow. Figure 2. Interface Policy Configuration within the Cisco APIC UI. Figure 2.1. Interface Policy Configuration within the Cisco APIC UI. Back to Top 1.2. Leaf Switches Policies Configuration Workflow. Leaf Switches Policy Groups they control the behavior of the entire leaf switch. This allows for consistent application of switch-level configurations to multiple leaf nodes selected by a Leaf Switch Profile. Key Leaf Switches Policy Groups are: Spanning Tree Monitoring polices CoPP Leaf Policy NetFlow Node Policy BFD IPv4 and IPv6 Policy Figure 3. Representing Leaf Switch Policies Configuration Flow. Figure 4. Leaf Switch Policies Configuration within the Cisco APIC UI. Figure 5. Full configuration flow for interface and leaf switch polices. Back to Top Leaf Access Port configuration Figure 6. Implementation of an Interface Policy Group within the Cisco APIC user interface (UI). After creating the Leaf Interface profile and attaching it to the Leaf Switch profile, we add specific ports under the Leaf Interface profile and select the appropriate Interface Policy Group. This approach provides reusability and simplifies automation. For Particular case we created Leaf Access Port Policy Group like below and attached to port eth1/1 inside specific Leaf Interface Profile. Figure 7. Representing creation of Access port policy group and attaching to specific Leaf Interface profile. Figure 8. End to end workflow to setup access port up and running on leaf switch. Back to Top Leaf Port Channel (PC) configuration The foundational workflow for configuring a Port Channel in Cisco ACI closely mirrors that of a standard Access Port; however, a key distinction lies in the explicit inclusion and application of an LACP Policy within the associated Interface Policy Group, which is then specifically leveraged for the two designated physical ports on a single leaf switch to form the logical Port Channel. Figure 9. Representing creation of Port Channel policy group. Figure 10. End to end workflow to setup Port Channel (PC) up and running on leaf switch. Back to Top Leaf Virtual Port Channel (vPC) configuration Virtual Port Channel (vPC) significantly enhances network resilience and operational uptime by logically combining two physical ports, each residing on a separate Cisco Nexus leaf switch, into a single, aggregated link. This innovative design provides superior high availability, as it creates active-active forwarding paths, ensuring that traffic can seamlessly continue to flow even if one of the leaf switches or an individual link experiences a failure. Figure 11. Representing creation of Virtual Port Channel (vPC) policy group. Figure 12.End to end workflow to setup Virtual Port Channel (vPC) up and running on leaf switches. Back to Top]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/aci_access_polices/1.gif" /><media:content medium="image" url="https://tomislavk.blog/images/aci_access_polices/1.gif" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Designing with Cisco ACI</title><link href="https://tomislavk.blog/aci/designing-with-aci/" rel="alternate" type="text/html" title="Designing with Cisco ACI" /><published>2025-03-30T00:00:00+04:00</published><updated>2025-03-30T00:00:00+04:00</updated><id>https://tomislavk.blog/aci/designing-with-aci</id><content type="html" xml:base="https://tomislavk.blog/aci/designing-with-aci/"><![CDATA[<p>Welcome to “Designing with Cisco ACI,” where we will dive into the Cisco ACI principals of creating robust, scalable, and efficient network architectures using Cisco’s Application Centric Infrastructure (ACI).
<!-- excerpt --></p>

<p>
In today’s rapidly evolving IT landscape, the ability to design flexible and resilient networks is more critical than ever. This blog will provide you with ideas on what you can do with Cisco ACI fabric, covering various use cases and key design points. It will be especially valuable for those preparing to deploy Cisco ACI and who are still unsure which design to choose.
The following Cisco ACI design types will be the topics of discussion:  
</p>
<body id="top">  
</body>

<p><strong>So let’s start!</strong></p>

<h2 id="cisco-aci-traditional-single-pod">Cisco ACI Traditional Single Pod</h2>
<p align="center">
<img src="/images/designing_with_aci/single-pod.png" alt="ACI-SinglePod" title="ACI-SinglePod" /> 
</p>
<p>Figure 1. Cisco ACI Single Pod Fabric.</p>

<p><strong>Main Characteristics:</strong></p>

<ul>
  <li><strong>Architecture:</strong> Consists of a single APIC (Application Policy Infrastructure Controller) cluster managing one ACI fabric.</li>
  <li><strong>Management:</strong> Centralized management with a single point of control.</li>
  <li><strong>Scalability:</strong> Limited to the capacity of one fabric.</li>
  <li><strong>Latency:</strong> Lower latency within the single fabric.</li>
  <li><strong>Failure Domain:</strong> Single failure domain, meaning any issue can affect the entire fabric.</li>
</ul>

<p><strong>Key Differences between Cisco ACI Single and Multi Pod Fabric:</strong></p>
<ul>
  <li><strong>Scalability:</strong> Multi-Pod offers greater scalability by allowing multiple Pods to be managed under one APIC cluster.</li>
  <li><strong>Resiliency:</strong> Multi-Pod improves resiliency by isolating failure domains.</li>
  <li><strong>Latency:</strong> Single Pod has lower latency within the fabric, while Multi-Pod may have slightly higher latency due to inter-Pod communication</li>
</ul>

<p><a href="#top">Back to Top</a></p>

<h2 id="cisco-aci-remote-leaf">Cisco ACI Remote leaf</h2>
<p align="center">
<img src="/images/designing_with_aci/remote-leaf.png" alt="ACI-Remote-leaf" title="ACI-Remote-leaf" /> 
</p>
<p>Figure 2. Cisco ACI Extending fabric with remote leaf to remote location.</p>

<p><strong>Main Characteristics:</strong></p>
<ul>
  <li><strong>VxLAN Tunnels:</strong> Unicast traffic is forwarded through VXLAN tunnels over Layer 3. This ensures that traffic between the remote leaf and the main fabric is encapsulated and securely transmitted.</li>
  <li><strong>Head End Replication (HER):</strong> For Layer 2 broadcast, unknown unicast, and multicast (BUM) traffic, Head End Replication (HER) tunnels are used. This method avoids the need for multicast in the WAN.</li>
  <li><strong>Policy Consistency:</strong> All policies defined in the main data center are consistently applied to the remote leaf switches, ensuring uniform policy enforcement across the entire fabric.</li>
  <li><strong>Local Switching:</strong> Traffic between endpoints connected to the remote leaf is switched locally, while traffic requiring spine proxy services is forwarded to the main fabric.</li>
</ul>

<p><strong>Inter-Pod Network Requirements for Remote Leaf deployment:</strong></p>
<ul>
  <li>L3 network should support 50 Bytes overhead for VxLAN if we have default MTU 1500 Bytes.</li>
  <li>The latency between the ACI main DC and the remote Leaf should be less than 300 msec Round Trip Time (RTT)</li>
  <li>A minimum of 100 Mbps bandwidth in the IP Network. Starting from Cisco ACI Release 4.2.4, the requirement has been lowered to 10 Mbps of bandwidth.</li>
  <li>The remote leaf solution requires the /32 Tunnel End Point (TEP) IP addresses of the remote leaf switches and main data center leaf/spine switches to be advertised across the main data center and remote leaf switches without summarization.</li>
</ul>

<p><strong>Use Cases:</strong><br />
<strong>Satellite/Co-Location Data Centers:</strong>  <br />
Enterprises or service providers often have a main data center and several smaller satellite data centers distributed across multiple locations.<br />
<strong>Disaster Recovery Sites:</strong>  <br />
Organizations need to maintain disaster recovery sites to ensure business continuity in case of a failure at the primary site.<br />
<strong>Branch Offices:</strong><br />
Companies with multiple branch offices require consistent network policies and centralized management.<br />
<strong>Edge Computing:</strong><br />
With the rise of edge computing, data processing is moved closer to the source of data generation example telco 5G.</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="cisco-aci-mini">Cisco ACI Mini</h2>
<p align="center">
<img src="/images/designing_with_aci/aci-mini.png" alt="ACI-Remote-leaf" title="ACI-Remote-leaf" /> 
</p>
<p>Figure 3. Cisco ACI mini - connecting virtual APICs to fabric.</p>

<p><strong>Main Characteristics</strong></p>
<ul>
  <li><strong>APIC Cluster:</strong>
Consists of one physical APIC and two virtual APICs (vAPICs) running in virtual machines.
Reduces the physical footprint and cost of the APIC cluster, making it suitable for environments with limited rack space or budget.</li>
  <li><strong>Deployment Scenarios:</strong>
Ideal for colocation facilities, single-room data centers, or any scenario where full-scale ACI installations are impractical.</li>
  <li><strong>Management and Policy:</strong>
Provides centralized management and policy enforcement similar to full-scale ACI deployments.
Does not support features like Multi-Pod, Virtual Pod, or Remote Leaf switches.</li>
  <li><strong>Integration:</strong>
Multi-Site Support: Can be integrated with Cisco ACI Multi-Site for broader deployment scenarios.</li>
  <li><strong>Time Synchronization:</strong>
Requires the physical APIC and the ESXi server hosting the virtual APICs to be time-synced with the same NTP server to avoid synchronization issues.</li>
</ul>

<p><strong>Use Cases:</strong></p>
<ul>
  <li><strong>Colocation Facilities:</strong>
Businesses that use colocation facilities to host their IT infrastructure.</li>
  <li><strong>Single-Room Data Centers:</strong>
Small businesses or branch offices with a single-room data center.</li>
  <li><strong>Development and Test Environments:</strong>
Organizations that need a dedicated environment for development and testing.</li>
  <li><strong>Edge Computing:</strong>
Deployments at the edge of the network, closer to data sources.</li>
</ul>

<p><a href="#top">Back to Top</a></p>

<h2 id="cisco-aci-multi-pod-interconnect-via-ipn">Cisco ACI Multi-Pod Interconnect via IPN</h2>
<p align="center">
<img src="/images/designing_with_aci/multi-pod.png" alt="ACI-MultiPod" title="ACI-MultiPod" /> 
</p>
<p>Figure 4. Cisco ACI Multi-Pod Interconnected via Inter-Pod Network.</p>

<p><strong>Main Characteristics</strong></p>
<ul>
  <li><strong>Centralized Management:</strong>
Managed by a single APIC cluster, providing a unified management and policy domain across all Pods1.</li>
  <li><strong>Fault Isolation:</strong>
Control plane protocols (e.g., IS-IS, COOP, MP-BGP) operate independently within each Pod, enhancing fault isolation.</li>
  <li><strong>Scalability:</strong>
Supports the interconnection of multiple Pods, allowing for greater scalability and flexibility in data center design.</li>
  <li><strong>Inter-Pod Network (IPN):</strong>
Pods are connected via a Layer 3 Inter-Pod Network (IPN), which uses VXLAN encapsulation for data plane traffic and MP-BGP EVPN for control plane communication.</li>
  <li><strong>End-to-End Policy Enforcement:</strong>
Ensures consistent policy enforcement across all Pods, maintaining uniform security and network policies.</li>
  <li><strong>Resiliency:</strong>
Isolated failure domains within each Pod reduce the impact of failures, enhancing overall resiliency.</li>
  <li><strong>Geographical Flexibility:</strong>
Pods can be located in different physical data centers, including geographically dispersed locations, with up to 50 ms RTT latency.</li>
</ul>

<p><strong>Inter-Pod Network (IPN) Requirements:</strong></p>
<ul>
  <li><strong>OSPF:</strong> Required for routing between Pods.</li>
  <li><strong>PIM Bi-Dir:</strong> Used for handling unknown unicast, multicast, and broadcast traffic.</li>
  <li><strong>MTU Size:</strong> The IPN must support jumbo frames with an MTU of 9150 to accommodate VXLAN encapsulated traffic.
In newer APIC version there is possibility to perform tunning of the MTU size of all the control plane packets generated by ACI nodes (leaf and spines), including inter-Pod MP-BGP control plane traffic.</li>
  <li><strong>DHCP Relay Functionality:</strong> Needed to allow Spine and Leaf nodes to be discovered across the IPN.</li>
  <li><strong>Prioritization:</strong> Ensures that APIC-to-APIC communication is prioritized over the IPN.</li>
  <li><strong>Interface Support:</strong> 10/40/100G</li>
  <li><strong>VLAN 4:</strong> Used for 802.1Q encapsulation between the spine and IPN devices.</li>
  <li><strong>VRF Context:</strong> Recommended to isolate IPN traffic from other services, ensuring stable IPN connectivity.</li>
</ul>

<p><strong>Use Cases:</strong></p>
<ul>
  <li><strong>Disaster Recovery and Business Continuity:</strong>
Organizations need to ensure business continuity and disaster recovery across multiple data centers.</li>
  <li><strong>Geographically Dispersed Data Centers:</strong>
Enterprises with data centers in different geographical locations require a unified network fabric.</li>
  <li><strong>Active/Active Data Centers:</strong>
Businesses need to deploy applications across multiple active data centers for load balancing and high availability.</li>
  <li><strong>Scalability and Flexibility:</strong>
Large enterprises or service providers need to scale their data center infrastructure.</li>
</ul>

<p><a href="#top">Back to Top</a></p>

<h2 id="cisco-aci-multi-pod-interconnect-spine-back-to-back">Cisco ACI Multi-Pod Interconnect Spine back to back.</h2>
<p align="center">
<img src="/images/designing_with_aci/multi-pod-b2b.png" alt="ACI-MultiPod" title="ACI-MultiPod" /> 
</p>
<p>Figure 5. Cisco ACI Multi-Pod, pods connected directly via Spines.</p>

<p>The characteristics and use cases for Cisco ACI Multi-Pod with spine back-to-back interconnect are essentially the same as those for Cisco ACI Multi-Pod interconnected via an Inter-Pod Network (IPN). The primary distinction is the absence of an IPN. However, it is crucial to ensure direct connectivity between remote spines.</p>

<p><strong>Advantages:</strong></p>
<ul>
  <li><strong>Simplified Network Design:</strong>
Eliminates the need for an Inter-Pod Network (IPN), simplifying the overall network design and reducing complexity.</li>
  <li><strong>Reduced Latency:</strong><br />
Provides direct connectivity between remote spines, which can reduce latency compared to traversing an IPN.</li>
  <li><strong>Cost Efficiency:</strong><br />
Reduces the need for additional IPN devices and infrastructure, leading to cost savings.</li>
  <li><strong>Improved Performance:</strong><br />
Direct spine-to-spine connections can optimize traffic flow and improve overall network performance.</li>
  <li><strong>Enhanced Resiliency:</strong><br />
Offers redundant paths between Pods, enhancing network resiliency and fault tolerance.</li>
</ul>

<p><a href="#top">Back to Top</a></p>

<h2 id="cisco-aci-multi-site">Cisco ACI Multi-Site</h2>
<p align="center">
<img src="/images/designing_with_aci/multi-site.png" alt="ACI-MultiSite" title="ACI-MultiSite" /> 
</p>
<p>Figure 6. Cisco ACI Multi-Site managed by Nexus Dashboard Orchestrator.</p>

<p><strong>Key Differences between Multi Site and Multi Pod deployment:</strong></p>
<ul>
  <li><strong>Management:</strong> Multi-Pod uses a single APIC cluster, while Multi-Site uses multiple APIC clusters managed by NDO.</li>
  <li><strong>Latency:</strong> Multi-Pod typically has lower latency between pods, whereas Multi-Site can handle higher latency across sites.</li>
  <li><strong>Scalability:</strong> Multi-Site is better suited for large-scale, geographically dispersed deployments.</li>
</ul>

<p><strong>Main Characteristics:</strong></p>
<ul>
  <li><strong>Geographical Flexibility:</strong>
Supports the interconnection of geographically dispersed data centers, extending Layer 2 and Layer 3 connectivity between sites.</li>
  <li><strong>Unified Policy Management:</strong>
Utilizes the Nexus Dashboard Orchestrator (formerly Multi-Site Orchestrator) to manage and enforce policies across multiple sites.</li>
  <li><strong>Fault Isolation:</strong>
Each site operates with its own APIC cluster, ensuring fault isolation and independent control planes.</li>
  <li><strong>Scalability:</strong>
Allows for the integration of multiple ACI fabrics, providing scalability for large and distributed environments.</li>
  <li><strong>Consistent Policy Enforcement:</strong>
Ensures consistent policy enforcement across all interconnected sites, maintaining uniform security and network policies.</li>
  <li><strong>Data Plane Communication:</strong>
VXLAN and MP-BGP EVPN: Uses VXLAN for data-plane communication and MP-BGP EVPN for control-plane communication between sites.</li>
</ul>

<p><strong>Inter-Site Network (ISN) Requirements:</strong>
ACI fabrics are connected via ISN routed network which will be used for VxLAN communications between endpoints which they belong to different fabrics.
I would like to highlight that there is no latency limit between the different ACI fabrics part of the same Multi-Site domain.<br />
The only latency considerations are:</p>

<ul>
  <li>Up to 150 ms, RTT is the latency supported between the Nexus Dashboard cluster nodes where the Orchestrator service is enabled.</li>
  <li>Up to 500 msec RTT is the latency between each Nexus Dashboard Orchestrator node and the APIC controller nodes that are added to the Multi-Site domain. This means that the Multi-Site architecture has been designed from the ground up to be able to manage ACI fabrics that can be geographically dispersed around the world.</li>
  <li>No Need for Multicast.</li>
  <li>MTU between ISN routers and spines should be increases to minimum 1600 Bytes, in this case should be changed default MTU size 9000 Bytes in global configuration.</li>
  <li>IP connectivity can be achieved using OSPF, BGP or static routing.</li>
</ul>

<p><strong>Use Cases:</strong><br />
<strong>Centralized Data Center with Separate Availability Zones:</strong><br />
Allows for the creation of distinct availability zones within a centralized data center, enhancing fault isolation and resource management.<br />
<strong>Disaster Recovery:</strong><br />
Facilitates disaster recovery by enabling data replication and failover between sites, ensuring business continuity in case of site failures.<br />
<strong>Geographically Distributed Data Centers:</strong><br />
Supports the management of data centers spread across different cities, countries, or continents from a single pane of glass, simplifying provisioning, monitoring, and management.<br />
<strong>Stretched Bridge Domain with Layer 2 Broadcast Extension:</strong><br />
Extends Layer 2 domains across sites, allowing for live VM migration and active/active high availability.<br />
<strong>Stretched VRF with Inter-Site Contracts:</strong><br />
Enables consistent policy enforcement across sites by stretching VRFs and applying inter-site contracts.<br />
<strong>Shared Services with Stretched Provider EPGs:</strong><br />
Allows shared services to be accessed across multiple sites using stretched Endpoint Groups (EPGs).</p>

<p><a href="#top">Back to Top</a></p>

<h2 id="multipod-multisite-hybrid-deployment">MultiPod MultiSite hybrid deployment</h2>

<p><a href="/images/designing_with_aci/multi-pod-multi-site.png" target="new" title="click here to see the full sized image"><img src="/images/designing_with_aci/multi-pod-multi-site.png" alt="your alt description here" /></a>
Figure 7. Extending Cisco ACI Multi-Pod to Multi-Site.</p>

<p>Using Cisco ACI Multi-Site and Multi-Pod as a single fabric offers several benefits, enhancing the overall network architecture. Here are some key advantages:</p>

<ul>
  <li><strong>Centralized Management:</strong><br />
Both Multi-Site and Multi-Pod architectures allow for centralized management through a single APIC cluster, simplifying policy enforcement and configuration.</li>
  <li><strong>Scalability:</strong><br />
Multi-Pod enables the expansion of a single ACI fabric across multiple locations without the need for separate fabrics, making it easier to scale the network.<br />
Multi-Site allows for the interconnection of multiple ACI fabrics, providing scalability across geographically dispersed data centers.</li>
  <li><strong>Resiliency and Fault Isolation:</strong><br />
Multi-Pod architecture offers full resiliency at the network level across pods while maintaining a single fabric, ensuring minimal impact from failures.<br />
Multi-Site architecture isolates failure domains between sites, enhancing overall network resiliency.</li>
  <li><strong>Disaster Recovery and Business Continuity:</strong><br />
Both architectures support disaster recovery by enabling data replication and failover between sites or pods, ensuring business continuity in case of site failures.</li>
  <li><strong>Consistent Policy Enforcement:</strong> 
Policies and configurations can be consistently applied across all sites and pods, ensuring uniform security and compliance.</li>
  <li><strong>Operational Efficiency:</strong>  <br />
Centralized management and automation reduce administrative overhead and operational complexity, making it easier to manage large-scale networks.</li>
</ul>

<p><a href="#top">Back to Top</a></p>]]></content><author><name>Tomislav Kranjec</name></author><category term="ACI" /><category term="aci" /><category term="fabric" /><category term="leaf" /><category term="spine" /><summary type="html"><![CDATA[Welcome to “Designing with Cisco ACI,” where we will dive into the Cisco ACI principals of creating robust, scalable, and efficient network architectures using Cisco’s Application Centric Infrastructure (ACI). In today’s rapidly evolving IT landscape, the ability to design flexible and resilient networks is more critical than ever. This blog will provide you with ideas on what you can do with Cisco ACI fabric, covering various use cases and key design points. It will be especially valuable for those preparing to deploy Cisco ACI and who are still unsure which design to choose. The following Cisco ACI design types will be the topics of discussion: So let’s start! Cisco ACI Traditional Single Pod Figure 1. Cisco ACI Single Pod Fabric. Main Characteristics: Architecture: Consists of a single APIC (Application Policy Infrastructure Controller) cluster managing one ACI fabric. Management: Centralized management with a single point of control. Scalability: Limited to the capacity of one fabric. Latency: Lower latency within the single fabric. Failure Domain: Single failure domain, meaning any issue can affect the entire fabric. Key Differences between Cisco ACI Single and Multi Pod Fabric: Scalability: Multi-Pod offers greater scalability by allowing multiple Pods to be managed under one APIC cluster. Resiliency: Multi-Pod improves resiliency by isolating failure domains. Latency: Single Pod has lower latency within the fabric, while Multi-Pod may have slightly higher latency due to inter-Pod communication Back to Top Cisco ACI Remote leaf Figure 2. Cisco ACI Extending fabric with remote leaf to remote location. Main Characteristics: VxLAN Tunnels: Unicast traffic is forwarded through VXLAN tunnels over Layer 3. This ensures that traffic between the remote leaf and the main fabric is encapsulated and securely transmitted. Head End Replication (HER): For Layer 2 broadcast, unknown unicast, and multicast (BUM) traffic, Head End Replication (HER) tunnels are used. This method avoids the need for multicast in the WAN. Policy Consistency: All policies defined in the main data center are consistently applied to the remote leaf switches, ensuring uniform policy enforcement across the entire fabric. Local Switching: Traffic between endpoints connected to the remote leaf is switched locally, while traffic requiring spine proxy services is forwarded to the main fabric. Inter-Pod Network Requirements for Remote Leaf deployment: L3 network should support 50 Bytes overhead for VxLAN if we have default MTU 1500 Bytes. The latency between the ACI main DC and the remote Leaf should be less than 300 msec Round Trip Time (RTT) A minimum of 100 Mbps bandwidth in the IP Network. Starting from Cisco ACI Release 4.2.4, the requirement has been lowered to 10 Mbps of bandwidth. The remote leaf solution requires the /32 Tunnel End Point (TEP) IP addresses of the remote leaf switches and main data center leaf/spine switches to be advertised across the main data center and remote leaf switches without summarization. Use Cases: Satellite/Co-Location Data Centers: Enterprises or service providers often have a main data center and several smaller satellite data centers distributed across multiple locations. Disaster Recovery Sites: Organizations need to maintain disaster recovery sites to ensure business continuity in case of a failure at the primary site. Branch Offices: Companies with multiple branch offices require consistent network policies and centralized management. Edge Computing: With the rise of edge computing, data processing is moved closer to the source of data generation example telco 5G. Back to Top Cisco ACI Mini Figure 3. Cisco ACI mini - connecting virtual APICs to fabric. Main Characteristics APIC Cluster: Consists of one physical APIC and two virtual APICs (vAPICs) running in virtual machines. Reduces the physical footprint and cost of the APIC cluster, making it suitable for environments with limited rack space or budget. Deployment Scenarios: Ideal for colocation facilities, single-room data centers, or any scenario where full-scale ACI installations are impractical. Management and Policy: Provides centralized management and policy enforcement similar to full-scale ACI deployments. Does not support features like Multi-Pod, Virtual Pod, or Remote Leaf switches. Integration: Multi-Site Support: Can be integrated with Cisco ACI Multi-Site for broader deployment scenarios. Time Synchronization: Requires the physical APIC and the ESXi server hosting the virtual APICs to be time-synced with the same NTP server to avoid synchronization issues. Use Cases: Colocation Facilities: Businesses that use colocation facilities to host their IT infrastructure. Single-Room Data Centers: Small businesses or branch offices with a single-room data center. Development and Test Environments: Organizations that need a dedicated environment for development and testing. Edge Computing: Deployments at the edge of the network, closer to data sources. Back to Top Cisco ACI Multi-Pod Interconnect via IPN Figure 4. Cisco ACI Multi-Pod Interconnected via Inter-Pod Network. Main Characteristics Centralized Management: Managed by a single APIC cluster, providing a unified management and policy domain across all Pods1. Fault Isolation: Control plane protocols (e.g., IS-IS, COOP, MP-BGP) operate independently within each Pod, enhancing fault isolation. Scalability: Supports the interconnection of multiple Pods, allowing for greater scalability and flexibility in data center design. Inter-Pod Network (IPN): Pods are connected via a Layer 3 Inter-Pod Network (IPN), which uses VXLAN encapsulation for data plane traffic and MP-BGP EVPN for control plane communication. End-to-End Policy Enforcement: Ensures consistent policy enforcement across all Pods, maintaining uniform security and network policies. Resiliency: Isolated failure domains within each Pod reduce the impact of failures, enhancing overall resiliency. Geographical Flexibility: Pods can be located in different physical data centers, including geographically dispersed locations, with up to 50 ms RTT latency. Inter-Pod Network (IPN) Requirements: OSPF: Required for routing between Pods. PIM Bi-Dir: Used for handling unknown unicast, multicast, and broadcast traffic. MTU Size: The IPN must support jumbo frames with an MTU of 9150 to accommodate VXLAN encapsulated traffic. In newer APIC version there is possibility to perform tunning of the MTU size of all the control plane packets generated by ACI nodes (leaf and spines), including inter-Pod MP-BGP control plane traffic. DHCP Relay Functionality: Needed to allow Spine and Leaf nodes to be discovered across the IPN. Prioritization: Ensures that APIC-to-APIC communication is prioritized over the IPN. Interface Support: 10/40/100G VLAN 4: Used for 802.1Q encapsulation between the spine and IPN devices. VRF Context: Recommended to isolate IPN traffic from other services, ensuring stable IPN connectivity. Use Cases: Disaster Recovery and Business Continuity: Organizations need to ensure business continuity and disaster recovery across multiple data centers. Geographically Dispersed Data Centers: Enterprises with data centers in different geographical locations require a unified network fabric. Active/Active Data Centers: Businesses need to deploy applications across multiple active data centers for load balancing and high availability. Scalability and Flexibility: Large enterprises or service providers need to scale their data center infrastructure. Back to Top Cisco ACI Multi-Pod Interconnect Spine back to back. Figure 5. Cisco ACI Multi-Pod, pods connected directly via Spines. The characteristics and use cases for Cisco ACI Multi-Pod with spine back-to-back interconnect are essentially the same as those for Cisco ACI Multi-Pod interconnected via an Inter-Pod Network (IPN). The primary distinction is the absence of an IPN. However, it is crucial to ensure direct connectivity between remote spines. Advantages: Simplified Network Design: Eliminates the need for an Inter-Pod Network (IPN), simplifying the overall network design and reducing complexity. Reduced Latency: Provides direct connectivity between remote spines, which can reduce latency compared to traversing an IPN. Cost Efficiency: Reduces the need for additional IPN devices and infrastructure, leading to cost savings. Improved Performance: Direct spine-to-spine connections can optimize traffic flow and improve overall network performance. Enhanced Resiliency: Offers redundant paths between Pods, enhancing network resiliency and fault tolerance. Back to Top Cisco ACI Multi-Site Figure 6. Cisco ACI Multi-Site managed by Nexus Dashboard Orchestrator. Key Differences between Multi Site and Multi Pod deployment: Management: Multi-Pod uses a single APIC cluster, while Multi-Site uses multiple APIC clusters managed by NDO. Latency: Multi-Pod typically has lower latency between pods, whereas Multi-Site can handle higher latency across sites. Scalability: Multi-Site is better suited for large-scale, geographically dispersed deployments. Main Characteristics: Geographical Flexibility: Supports the interconnection of geographically dispersed data centers, extending Layer 2 and Layer 3 connectivity between sites. Unified Policy Management: Utilizes the Nexus Dashboard Orchestrator (formerly Multi-Site Orchestrator) to manage and enforce policies across multiple sites. Fault Isolation: Each site operates with its own APIC cluster, ensuring fault isolation and independent control planes. Scalability: Allows for the integration of multiple ACI fabrics, providing scalability for large and distributed environments. Consistent Policy Enforcement: Ensures consistent policy enforcement across all interconnected sites, maintaining uniform security and network policies. Data Plane Communication: VXLAN and MP-BGP EVPN: Uses VXLAN for data-plane communication and MP-BGP EVPN for control-plane communication between sites. Inter-Site Network (ISN) Requirements: ACI fabrics are connected via ISN routed network which will be used for VxLAN communications between endpoints which they belong to different fabrics. I would like to highlight that there is no latency limit between the different ACI fabrics part of the same Multi-Site domain. The only latency considerations are: Up to 150 ms, RTT is the latency supported between the Nexus Dashboard cluster nodes where the Orchestrator service is enabled. Up to 500 msec RTT is the latency between each Nexus Dashboard Orchestrator node and the APIC controller nodes that are added to the Multi-Site domain. This means that the Multi-Site architecture has been designed from the ground up to be able to manage ACI fabrics that can be geographically dispersed around the world. No Need for Multicast. MTU between ISN routers and spines should be increases to minimum 1600 Bytes, in this case should be changed default MTU size 9000 Bytes in global configuration. IP connectivity can be achieved using OSPF, BGP or static routing. Use Cases: Centralized Data Center with Separate Availability Zones: Allows for the creation of distinct availability zones within a centralized data center, enhancing fault isolation and resource management. Disaster Recovery: Facilitates disaster recovery by enabling data replication and failover between sites, ensuring business continuity in case of site failures. Geographically Distributed Data Centers: Supports the management of data centers spread across different cities, countries, or continents from a single pane of glass, simplifying provisioning, monitoring, and management. Stretched Bridge Domain with Layer 2 Broadcast Extension: Extends Layer 2 domains across sites, allowing for live VM migration and active/active high availability. Stretched VRF with Inter-Site Contracts: Enables consistent policy enforcement across sites by stretching VRFs and applying inter-site contracts. Shared Services with Stretched Provider EPGs: Allows shared services to be accessed across multiple sites using stretched Endpoint Groups (EPGs). Back to Top MultiPod MultiSite hybrid deployment Figure 7. Extending Cisco ACI Multi-Pod to Multi-Site. Using Cisco ACI Multi-Site and Multi-Pod as a single fabric offers several benefits, enhancing the overall network architecture. Here are some key advantages: Centralized Management: Both Multi-Site and Multi-Pod architectures allow for centralized management through a single APIC cluster, simplifying policy enforcement and configuration. Scalability: Multi-Pod enables the expansion of a single ACI fabric across multiple locations without the need for separate fabrics, making it easier to scale the network. Multi-Site allows for the interconnection of multiple ACI fabrics, providing scalability across geographically dispersed data centers. Resiliency and Fault Isolation: Multi-Pod architecture offers full resiliency at the network level across pods while maintaining a single fabric, ensuring minimal impact from failures. Multi-Site architecture isolates failure domains between sites, enhancing overall network resiliency. Disaster Recovery and Business Continuity: Both architectures support disaster recovery by enabling data replication and failover between sites or pods, ensuring business continuity in case of site failures. Consistent Policy Enforcement: Policies and configurations can be consistently applied across all sites and pods, ensuring uniform security and compliance. Operational Efficiency: Centralized management and automation reduce administrative overhead and operational complexity, making it easier to manage large-scale networks. Back to Top]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/designing_with_aci/1.gif" /><media:content medium="image" url="https://tomislavk.blog/images/designing_with_aci/1.gif" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Unlocking the Power of Cisco ACI 6.0</title><link href="https://tomislavk.blog/aci/aci-6-new-features/" rel="alternate" type="text/html" title="Unlocking the Power of Cisco ACI 6.0" /><published>2024-09-27T00:00:00+04:00</published><updated>2024-09-27T00:00:00+04:00</updated><id>https://tomislavk.blog/aci/aci-6-new-features</id><content type="html" xml:base="https://tomislavk.blog/aci/aci-6-new-features/"><![CDATA[<p style="text-align: justify;">
The Cisco ACI 6.0 release has been available for a couple of months now. Let’s check out what it brings to network engineers and IT professionals. Experience a new era of enhanced performance, security, and automation capabilities. In this blog, we’ll dive into the key enhancements of Cisco ACI 6.0 and explore how they can empower your network infrastructure.
</p>

<h2 id="cisco-aci-602-and-603-comparison-features-changes-and-enhancements">Cisco ACI 6.0.2 and 6.0.3 Comparison Features, Changes, and Enhancements</h2>

<ol>
  <li>Virtual APIC on VMware ESXi and Cloud</li>
  <li>VMM Integration with Nutanix AHV</li>
  <li>Nexus Dashboard - Connectivity analysis</li>
</ol>

<p><strong><span style="color:#074080">1. Virtual APIC  6.0(2)F</span></strong></p>

<ul>
  <li>No physical APICs.</li>
  <li>No configuration limitations you can administer it like a regular APICs.</li>
  <li>Scale is pretty much same as for physical APIC.</li>
  <li>Limitations not able to run applications such as ELAM, policy explorer.</li>
  <li>APICs can be connected to leaf switches directly.</li>
  <li>Or they can be connected remotely via L3 network.
During the initial setup, the wizard will ask you to choose how the APIC is connected to the network. Figure 1 below is an example.</li>
  <li>Virtual APIC Cluster Fully functional APIC that can manage up to 200 switches.</li>
  <li>6.0(2)F Cloud hosted APIC Cluster can only be deployed within AWS Cloud.</li>
</ul>
<p align="center">
<img src="/images/aci_6_new_features/2.png" alt="ACI 60" title="ACI 60" /> 
</p>
<p><strong>Figure 1</strong> ACI setup wizard</p>

<p><strong><span style="color:#074080">2. Integration with Nutanix AHV hypervisor  6.0(3)F</span></strong></p>
<ul>
  <li>APICs connect and authenticate to Prism Manager.</li>
  <li>Integration of Nutanix Acropolis Hypervisor (AHV) with Cisco Application Centric Infrastructure (ACI).</li>
  <li>This integration provides virtual and physical network automation and VM endpoints visibility in Cisco ACI.</li>
  <li>End to end network automation and end to end visibility.</li>
</ul>

<p><strong><span style="color:#074080">3. Nexus Dashboard - Connectivity Analysis 6.0(2)F</span></strong></p>

<ul>
  <li>Troubleshooting between two End points, src and dst IP addresses or src and dst MAC addresses.</li>
  <li>Visibility of what happening between control and data plane.</li>
  <li>Verification of control and data plane.</li>
  <li>Traces all possible forwarding paths between source and destinations.</li>
  <li>Identifies if there are problems in the path and what is causing issues.</li>
  <li>Helps to highlight real root cause, perform forwarding checks.</li>
</ul>

<p><strong><span style="color:#074080">4.Interface policy - simplify configuration</span></strong></p>
<ul>
  <li>This type of configuration is optional there is no need to change if you already master polices configuration. On that way you will keep everything under your control.</li>
  <li>This is more for new guys which is starting to use ACI Fabric.</li>
  <li>Guys with experience will not have so many benefits from this feature.</li>
  <li>It is compatible with previous manual configuration of polices.</li>
  <li>Not recommended for brown field deployments, I would like to recommend only for green field deployment.</li>
</ul>

<p><strong><span style="color:#074080">5.Weight-Based Symmetric PBR</span></strong></p>

<p>In 6.0 it was introduced Weight-based PBR it means that we can send more traffic to specific node.
Use case:<br />
•	On specific node we have connected Load Balancer.<br />
•	On specific node we have more powerful firewall in the group.<br />
•	Introducing new firewall, we can redirect small amount of traffic to new firewall for test purposes.</p>

<p><strong><span style="color:#074080">6.Stretched L3out SVI across remote leaves.</span></strong></p>

<ul>
  <li>Supported for stretching a non-vPC L3Out SVI across remote leaf switches
Use cases:</li>
  <li>Mobile packet core.</li>
  <li>Containerized workloads special at the Edge.</li>
  <li>Cloud native network functions CNF.</li>
</ul>

<p><strong><span style="color:#074080">7. Multi-Site support for vzAny PBR and L3Out-to-L3Out PBR use cases.</span></strong>
From ACI 6.0(4)F and NDO 4.2(3) following uses cases are supported:</p>
<ul>
  <li>vzAny-to-vzAny (Intra VRF).</li>
  <li>vzAny-to-EPG (Intra VRF).</li>
  <li>vzAny-to-L3out (Intra VRF).</li>
  <li>L3out-to-L3out ((Intra VRF) and inter-VRF).</li>
  <li>Standard EPG-to-EPG subnet under consumer still is required.
If you have plan to implement vzAny inside multi-site design, please check all details on link below:
<a href="https://www.cisco.com/c/en/us/td/docs/dcn/ndo/4x/configuration/cisco-nexus-dashboard-orchestrator-configuration-guide-aci-421/ndo-configuration-aci-use-case-vzany-pbr-42x.html" target="_blank">Cisco Nexus Dashboard Orchestrator Configuration Guide for ACI Fabrics</a>.</li>
</ul>

<p><strong><span style="color:#074080">8. Main Routing improvements Multi-Site support for vzAny PBR and L3Out-to-L3Out PBR use cases.</span></strong></p>

<ul>
  <li>BGP AS - Remove private AS from AS_PATH.</li>
  <li>Support for BFD on Secondary subnet IPv4/IPv6.</li>
  <li>BGP Additional Paths - Receive multiple paths for the same prefix without the new paths replacing any previous paths.</li>
</ul>

<p><strong><span style="color:#074080">9. Operating and Administering improvements.</span></strong></p>

<p>ACI ver.6.0(1)F</p>
<ul>
  <li>Simplifying interface configuration.</li>
  <li>Secure Erase (RMA).</li>
</ul>

<p>ACI ver.6.0(2)F</p>
<ul>
  <li>Auto firmware update for Cisco APIC on discovery - APIC will be automatically upgrade on version same as fabric.</li>
  <li>Installing switch SMU without reload.</li>
  <li>Troubleshooting of QoS Polices.</li>
</ul>

<p>ACI ver.6.0(3)F</p>
<ul>
  <li>Reduce of time of APIC upgrade.</li>
  <li>Transaction-based Logging.</li>
  <li>Memory-based Automatic Switch Image Selection 32/64 bit.</li>
</ul>

<p>ACI ver.6.0(4)F</p>
<ul>
  <li>Streamlined navigation and editing of the stat collection threshold from a TCA fault.</li>
</ul>

<p><strong><span style="color:#074080">10. Main Security improvements</span></strong></p>

<ul>
  <li>Cisco Nexus 9K switch secure erase.</li>
  <li>Support for a user group map rule for SAML and OAuth2.</li>
  <li>Support for TLS ver 1.3</li>
  <li>First hop security FHS support for VMM.</li>
  <li>TACACS external logging for switches.</li>
  <li>RSA Key 307 and 4096 support on X.509 certificates.</li>
</ul>

<p><strong><span style="color:#074080">11. Integrations.</span></strong></p>

<ul>
  <li>Enhanced LLDP TLVs for Azure Stack HCI.</li>
  <li>Policy mode for Cisco ACI and VMware NSX-T integration.</li>
  <li>VMM Domain support for VMware vSphere 8.0.</li>
</ul>

<p><strong><span style="color:#074080">12. Scale improvements.</span></strong></p>

<p align="center">
<img src="/images/aci_6_new_features/3.png" alt="ACI 60" title="ACI 60" /> 
</p>

<p align="center">
<img src="/images/aci_6_new_features/4.png" alt="ACI 60" title="ACI 60" /> 
</p>

<p align="center">
<img src="/images/aci_6_new_features/5.png" alt="ACI 60" title="ACI 60" /> 
</p>

<p>References: <br />
<a href="https://www.cisco.com/c/en/us/td/docs/dcn/aci/apic/6x/release-notes/cisco-apic-release-notes-611.html" target="_blank">Cisco Application Policy Infrastructure Controller</a> <br />
<a href="https://www.cisco.com/c/en/us/td/docs/dcn/aci/apic/all/cisco-aci-releases-changes-in-behavior.html" target="_blank">Cisco ACI Releases Changes in Behavior</a></p>]]></content><author><name>Tomislav Kranjec</name></author><category term="ACI" /><category term="aci" /><category term="fabric" /><category term="leaf" /><category term="spine" /><summary type="html"><![CDATA[The Cisco ACI 6.0 release has been available for a couple of months now. Let’s check out what it brings to network engineers and IT professionals. Experience a new era of enhanced performance, security, and automation capabilities. In this blog, we’ll dive into the key enhancements of Cisco ACI 6.0 and explore how they can empower your network infrastructure.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/aci_6_new_features/1.png" /><media:content medium="image" url="https://tomislavk.blog/images/aci_6_new_features/1.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Mastering Cisco ACI Physical Design</title><link href="https://tomislavk.blog/aci/physical-design/" rel="alternate" type="text/html" title="Mastering Cisco ACI Physical Design" /><published>2024-07-07T00:00:00+04:00</published><updated>2024-07-07T00:00:00+04:00</updated><id>https://tomislavk.blog/aci/physical-design</id><content type="html" xml:base="https://tomislavk.blog/aci/physical-design/"><![CDATA[<p style="text-align: justify;">
Let's dive into the world of Cisco ACI physical design. After all, we all know that without hardware, there is no cloud or networking.
</p>

<p style="text-align: justify;">
Dive into the world of Clos Topology, a concept born from a 1952 paper by Charles Clos, a researcher at Bell Laboratories. His revolutionary ideas on multistage telephone switching systems have transcended time, now serving as the foundation for building highly scalable data centers with cost-effective switches.
The Cisco ACI fabric is based on either a two-tier (spine and leaf switch) or three-tier (spine switch, tier-1 leaf switch, and tier-2 leaf switch) architecture.
In a Cisco Application Centric Infrastructure (ACI), each of the leaf, Fabric Extenders and spine switches has different functions.
</p>

<h2 id="leaf-switches">Leaf Switches</h2>

<ul>
  <li>Leaf switches are the ingress/egress points for traffic into and out of an ACI fabric.</li>
  <li>They connect directly to servers and other devices, facilitating rapid data transfer.</li>
  <li>Each leaf switch is linked to every spine switch, creating a mesh of high-bandwidth connections.</li>
  <li>This setup ensures that any data packet is only a couple of hops away from its destination, significantly reducing latency.</li>
</ul>

<h2 id="fabric-extenders-fex">Fabric Extenders (FEX)</h2>

<p>Fabric Extenders (FEX) in Cisco’s Application Centric Infrastructure (ACI) have several key functions:</p>
<ul>
  <li>Port Extension - FEX extends the ports of a Nexus switch, acting as a remote line card. This allows for the use of more cost-effective devices with a reduced set of features that are connected to the Leaf Switches.</li>
  <li>Agile Connectivity - FEX offers agile connectivity for rack and blade servers and for converged fabric deployments. It delivers innovation to the data center, reduces total cost of ownership, and gains architectural flexibility.</li>
  <li>Configuration and Management - All management is done on the parent switch; there is no console/vty access on the FEX. This simplifies the management of the network infrastructure.</li>
  <li>Cisco ACI leaf switch models with -G or -Tin the product name, such as Cisco Nexus N9K-C9348GC-FXP, N9K-C93108TC-FX, N9K-C93108TC-FX-24, N9K-C93108TC-EX, N9K-C93108TC-EX-24, N9K-C93216TC-FX2, and N9K-93108TC-FX3P.</li>
</ul>

<p>Discover the steps to configure Fabric Extenders (FEX) in Cisco ACI in Cisco comprehensive guide available <a href="https://www.cisco.com/c/en/us/support/docs/cloud-systems-management/application-policy-infrastructure-controller-apic/200529-Configure-a-Fabric-Extender-with-Applica.html" target="_blank">here</a>.</p>

<h2 id="spine-switches">Spine Switches</h2>

<p>Spine switches are Clos intermediary switches that have a number of key functions:</p>

<ul>
  <li>They are responsible for high-capacity data transmission across the network.</li>
  <li>They ensure that data packets travel efficiently from one leaf switch to another.</li>
  <li>The spine layer is crucial for maintaining the performance of the network as it scales, providing a robust framework that can handle increasing data demands without bottlenecks.</li>
  <li>Spine switches interconnect all leaf switches in a full-mesh topology.</li>
</ul>

<p>Together, they create an architecture that is highly standardized across deployments. This design allows for a highly scalable and efficient network infrastructure.</p>

<h2 id="two-tier-or-multi-tier-design">Two-Tier or Multi-Tier Design?</h2>

<p style="text-align: justify;">
Below Figure 1 illustrates the necessary components and cabling for an two-tier ACI fabric. It’s important to note that no cables should be connected between ACI leaf switches, as this is characteristic of Clos network design. Similarly, cross-cabling ACI spines will lead to the disabling of the cross-connected ports. The topology depicts a full mesh of cabling between the spine and leaf layers. 
However, it’s important to note that while the Spine-Leaf architecture can be implemented without ACI, with the switches working in NX-OS mode. I would like to highlight that ASICs are different for Leaf and Spine switches, so a switch like the Nexus N9K-93180YC-EX cannot run as Spine switches.  
</p>

<p align="center">
<img class="center" style="float" width="350" height="350" src="/images/phy_design/aci-PhysicalDesign.jpg" alt="phy-design" title="PHY" />  
</p>

<p><strong>Figure 1</strong> Two-Tier Topology Spine-Leaf classic interconnect between leaf and spine switches</p>

<p>In summary, I would like to recommend to check switch compatibility on the links below:</p>

<ul>
<li><a href="https://www.cisco.com/c/dam/en/us/products/switches/nexus-9000-series-switches/nexus-9300-10GbaseT-switches-comparison.html" target="_blank">Cisco Nexus 9300 1/10GBaseT Switches</a></li>
<li><a href="https://www.cisco.com/c/en/us/products/switches/nexus-9000-series-switches/nexus-9300-10ge-fiber-switches-comparison.html" target="_blank">Cisco Nexus 9300 1/10/25/40/50/100GE Fiber Switches</a></li>
<li><a href="https://www.cisco.com/c/dam/en/us/products/switches/nexus-9000-series-switches/nexus-9300-40GE-switches-comparison.html" target="_blank">Cisco Nexus 9300 40/100 GE Switches</a></li>
<li><a href="https://www.cisco.com/c/en/us/products/switches/nexus-9000-series-switches/nexus-9300-400-ge-switches.html" target="_blank">Cisco Nexus 9300 400 GE Switches</a></li>
<li><a href="https://www.cisco.com/c/en/us/products/collateral/switches/nexus-9000-series-switches/datasheet-c78-731792.html" target="_blank"> Cisco Nexus 9300 ACI Fixed Spine Switches Data Sheet</a></li>
</ul>

<p>If you plan to use Cisco Nexus modular switches for Cisco ACI fabric technical details you can find on below links:</p>

<ul>
  <li><a href="https://www.cisco.com/c/en/us/products/collateral/switches/nexus-9000-series-switches/datasheet-c78-729404.html" target="_blank"> Cisco Nexus 9500 Series Switches Data Sheet</a></li>
  <li><a href="https://www.cisco.com/c/en/us/products/switches/nexus-9000-series-switches/nexus-9500-chassis-comparison.html" target="_blank"> Nexus 9500 Chassis Comparison</a></li>
  <li><a href="https://www.cisco.com/c/en/us/products/switches/nexus-9000-series-switches/nexus-9800-models-comparison.html" target="_blank"> Nexus 9800 Compare Models</a></li>
  <li><a href="https://www.cisco.com/c/en/us/products/switches/nexus-9000-series-switches/nexus-9800-line-cards-comparison.html" target="_blank"> Nexus 9800 Line Cards comparison</a></li>
</ul>

<p style="text-align: justify;">
Starting from Cisco ACI 4.1, the fabric also supports a multi-tier (three-tiers) topology. This includes two tiers of leaf switches, allowing for vertical expansion of the Cisco ACI fabric. This is particularly useful for migrating a traditional three-tier architecture (core-aggregation-access), a common design model for many enterprise networks.
The ACI Multi-Tier is a beneficial solution for data centers aiming to reduce inter-row cabling and have low-bandwidth needs for top-of-rack switches. In this setup, Tier 1 leaf switches are placed at the end of each row, while Tier 2 leaf switches are positioned at the top of each rack. This strategy is particularly effective in managing cables and meeting bandwidth requirements.
</p>

<p align="center">
<img class="center" style="float" width="450" height="400" src="/images/phy_design/aci-PhysicalDesign 2.jpg" alt="phy-design" title="PHY" />  
</p>

<p><strong>Figure 2</strong> Multi -Tier Topology Spine- Tier 1 Leaf and Tier 2 Leaf</p>

<p align="center">
<img class="center" style="float" width="400" height="300" src="/images/phy_design/aci-Sec PhysicalDesign 2.jpg" alt="phy-design" title="PHY" />  
</p>

<p><strong>Figure 3</strong> Multi -Tier Topology Spine- Tier 1 Leaf and Tier 2 Leaf option between two data center buildings</p>

<p>The topology requirements may include various models of spine and leaf switches, please check below:</p>

<ul>
  <li>
    <p><strong>Spine:</strong> EX/FX/C/GX/GX2 spines (For example, Cisco Nexus 9332C, 9316D-GX, 9348D-GX2A, 9408 and 9500 with EX/FX/GX linecards).</p>
  </li>
  <li>
    <p><strong>Tier-1</strong> Leaf: EX/FX/FX2/FX3/GX/GX2 except Cisco Nexus 93180LC-EX.</p>
  </li>
  <li>
    <p><strong>Tier-2</strong> All EX/FX/FX2/FX3/GX/GX2.</p>
  </li>
</ul>

<p>In the scenario where server access is at 1G and there is not need for high bandwidth, it’s a viable choice to use the Cisco Nexus 93180FX3 or Nexus 9364C-GX as the tier-1 leaf and the Cisco Nexus 9348FXP as the tier-2 leaf.</p>

<p>Before you start to build and design a multi-tier topology in a Cisco ACI environment, please take into account the following:</p>

<p><strong><span style="color:#074080">1.Fabric Port Configuration:</span></strong> All inter-switch connections must be configured as fabric ports. This includes the connections between Tier-2 leaf switch fabric ports and Tier-1 leaf switch fabric ports.</p>

<p><strong><span style="color:#074080">2.Tier-2 Leaf Switch Connectivity:</span></strong> A Tier-2 leaf switch has the capability to connect to more than two Tier-1 leaf switches. This is in contrast to a traditional double-sided vPC design, which only supports two upstream switches. The maximum number of ECMP links supported by a Tier-2 leaf switch to a Tier-1 leaf switch is 18.</p>

<p><strong><span style="color:#074080">3.Endpoint Group (EPG) and Layer 3 Outside (L3Out) Connections:</span></strong> EPGs, L3Outs, Cisco APICs, or Fabric Extenders (FEX) can be connected to either Tier-1 or Tier-2 leaf switches.</p>

<p><strong><span style="color:#074080">4.Tier-1 Leaf Switch Connections:</span></strong> Tier-1 leaf switches can have both hosts and Tier-2 leaf switches connected to them.</p>

<p><strong><span style="color:#074080">5.Switch Tier Transition:</span></strong> Transitioning from a Tier-1 to a Tier-2 leaf switch (and vice versa) requires decommissioning and recommissioning the switch.</p>

<p><strong><span style="color:#074080">6.Compatibility with Cisco ACI Multi-Pod and Multi-Site:</span></strong> Multi-tier architectures are compatible with both Cisco ACI Multi-Pod and Cisco ACI Multi-Site.</p>

<p><strong><span style="color:#074080">7.Tier-2 Leaf Switch Connectivity Limitations:</span></strong> Tier-2 leaf switches cannot be connected to remote leaf switches (Tier-1 leaf switches).</p>

<p><strong><span style="color:#074080">8.Scale Considerations:</span></strong> The combined number of Tier-1 and Tier-2 leaf switches must not exceed the maximum number of leaf switches validated for a given release (400 per pod; 500 per Cisco ACI Multi-Pod as of Cisco ACI release 6.0(1)).</p>

<p>Reference for <a href="https://www.cisco.com/c/en/us/products/switches/nexus-9000-series-switches/nexus-9800-line-cards-comparison.html" target="_blank"> Cisco ACI Multi-tier Architecture</a>.</p>

<p><strong><em><span style="color:#074080">Fabric Port</span></em></strong></p>

<p style="text-align: justify;">
In Cisco's Application Centric Infrastructure (ACI), a fabric port is a type of port that is used for uplink connectivity within the fabric. These ports are typically used to connect different switches within the ACI fabric.
For example, in a multi-tier topology, all switch-to-switch links must be configured as fabric ports. This includes the connections between Tier-2 leaf switch fabric ports and Tier-1 leaf switch fabric ports.
</p>

<p><strong><span style="color:#074080">Fiber optics modules</span></strong></p>

<p style="text-align: justify;">  
Don't forget that based on specific switch model and uplinks design you will need to choose proper optical modules.
All details about compatibility matrix for Cisco Optics and devices you can find on below links:
</p>
<ul>
  <li><a href="https://tmgmatrix.cisco.com/">Cisco Optics-to-Device Compatibility Matrix</a></li>
  <li><a href="https://tmgmatrix.cisco.com/iop">Cisco Optics-to-Optics Interoperability Matrix</a></li>
</ul>
<p style="text-align: justify;"> 
If you struggling or you have some doubts about compatibility between switches and optical modules SFP SFP+ QSFPs I would like to recommend:
</p>

<p>
<iframe width="420" height="315" src="https://www.youtube.com/embed/5I19ePqzNhc?controls=0">
</iframe>
</p>

<p>
<iframe width="420" height="315" src="https://www.youtube.com/embed/FFhNGxmniR4?controls=0">
</iframe>  
</p>

<p><strong><span style="color:#074080">Taxonomy for Cisco Nexus 9000 Series Part Numbers</span></strong></p>

<p style="text-align: justify;">
For a comprehensive understanding and decoding of all Nexus Part Numbers names, kindly refer to Figure 4.
</p>

<p align="center">
<img class="center" style="float" width="800" height="400" src="/images/phy_design/taxonomy_nk9.png" alt="taxonomynk9" title="PHY" />  
</p>

<p><strong>Figure 4</strong> Cheet-sheet for decoding Cisco Nexus 9000 Series Part Numbers</p>]]></content><author><name>Tomislav Kranjec</name></author><category term="ACI" /><category term="aci" /><category term="fabric" /><category term="leaf" /><category term="spine" /><summary type="html"><![CDATA[Let's dive into the world of Cisco ACI physical design. After all, we all know that without hardware, there is no cloud or networking.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/phy_design/2.png" /><media:content medium="image" url="https://tomislavk.blog/images/phy_design/2.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Cisco ACI Fabric - APIC Day 1 configuration</title><link href="https://tomislavk.blog/aci/aci-apic-initial-setup/" rel="alternate" type="text/html" title="Cisco ACI Fabric - APIC Day 1 configuration" /><published>2022-12-01T00:00:00+04:00</published><updated>2022-12-01T00:00:00+04:00</updated><id>https://tomislavk.blog/aci/aci-apic-initial-setup</id><content type="html" xml:base="https://tomislavk.blog/aci/aci-apic-initial-setup/"><![CDATA[<h2 id="cisco-apic-initial-configuration-and-fabric-provisioning">Cisco APIC Initial Configuration and Fabric Provisioning</h2>

<p style="text-align: justify;">
This time I will go through configuration steps for provisioning switches on Cisco ACI Fabric, NTP, DNS and BGP Route Reflectors. Steps described in this post are applicable for Cisco ACI Fabric and Cisco ACI simulator. 
</p>

<p><strong>0.</strong> In your favorite browser address bar add <strong><em>https://oob.ip.address</em></strong>. Use IP address what you set during APIC initial configuration.</p>

<p><img class="center" width="800" height="400" src="/images/acisim_init_conf/login_screen2.jpg" alt="APIC Login" title="APIC Login" /></p>

<p><strong>Cisco ACI Fabric APIC ver 5.2 supported browsers:</strong></p>
<ul>
  <li>Chrome version 59 (at minimum)</li>
  <li>Firefox version 54 (at minimum)</li>
  <li>Internet Explorer version 11 (at minimum)</li>
  <li>Safari version 10 (at minimum)</li>
</ul>

<p><strong>1.</strong> After what you will login it will appear Cisco APIC welcome screen, looks nice. Just press <strong>Let’s go</strong> as this white button suggesting.
<img class="center" width="800" height="400" src="/images/apic_day_0_config/1.jpg" alt="APIC Welcome Screen" title="APIC Welcome Screen" /></p>

<p><strong>2.</strong> One more screen from APIC this one is important as it will provided you information about:</p>
<ul>
  <li>New features for installed APIC version of APIC.</li>
  <li>Updated scalability numbers.</li>
  <li>Very good resources and knowledge base for ACI fabric and APIC clusters.<br />
After what you reviewed all interesting things pres <strong>Start ACI Fabric Setup</strong> button.</li>
</ul>

<p><img class="center" width="800" height="470" src="/images/apic_day_0_config/2.jpg" alt="APIC Release notes" title="APIC Release notes" /></p>

<p><strong>3.</strong> Below we can see the most important sections which should be configured before any service configuration on ACI.</p>

<p>I would like to suggest following order:</p>
<ol>
  <li>Add leaf and spine to Cisco ACI Fabric.</li>
  <li>NTP server configuration.</li>
  <li>DNS server configuration.</li>
  <li>BGP RR configuration for Spine.</li>
</ol>

<p><img class="center" width="800" height="450" src="/images/apic_day_0_config/3.jpg" alt="APIC Basic service setup" title="APIC Basic service setup" /></p>

<p><strong>4.</strong> Add first leaf to Cisco ACI Fabric, for serial number we will use TEP-1-102, 101 and 103 as this is Cisco ACI simulator on real Cisco ACI Fabric you will have serial numbers in following format F1234A768. For node ID choose unique number, once when you tied node ID to serial number you will not be able to change on the fly. If you would like to change you will need to do decommissioning and commissioning with new node ID. Switch name you can change anytime if you will not like assigned during initial switch provisioning.</p>

<p><img class="center" width="600" height="s 200" src="/images/apic_day_0_config/4.jpg" alt="APIC spine leaf membership" title="APIC spine leaf membership" /></p>

<p><strong>5.</strong> Here you should pay attention  and check is it switch in <strong>Registering</strong> phase, if you notice some other messages please stop and perform tshoot.</p>

<p><img class="center" width="800" height="400" src="/images/apic_day_0_config/5.jpg" alt="APIC add leaf to membership" title="APIC add leaf to membership" /></p>

<p><strong>6.</strong> Once when is done we should see that switch is successfully <strong>Register</strong> as we can see below for leaf with node ID 101.</p>

<p><img class="center" width="800" height="350" src="/images/apic_day_0_config/6.jpg" alt="APIC add leaf to membership" title="APIC add leaf to membership" /></p>

<p><strong>7.</strong> Same you should repeat for all Spine switches too, below you can see <strong>Registering</strong> of spine with node ID 103.</p>

<p><img class="center" width="800" height="350" src="/images/apic_day_0_config/7.jpg" alt="APIC add spine to membership" title="APIC add spine to membership" /></p>

<p><strong>8.</strong> And Spine with node ID 103 has been successfully <strong>Register</strong>.</p>

<p><img class="center" width="800" height="350" src="/images/apic_day_0_config/8.jpg" alt="APIC add spine to membership" title="APIC add spine to membership" /></p>

<p><strong>9.</strong> Based on workflow from point #3 I will proceed with NTP configuration. You can choose time format from <strong>local</strong> or <strong>utc</strong>. Use <strong>plus</strong> sign for adding one or more NTP servers, one of them you can set like preferable.</p>

<p><img class="center" width="800" height="400" src="/images/apic_day_0_config/9.jpg" alt="APIC NTP Configuration" title="APIC NTP Configuration" /></p>

<p><strong>10.</strong> In the lab for NTP server I use public Google NTP server just for test.
<img class="center" width="800" height="450" src="/images/apic_day_0_config/10.jpg" alt="APIC NTP Configuration" title="APIC NTP Configuration" /></p>

<p><strong>11.</strong> Here I will add Google DNS server just for test. Usually you will use internal DNS. Don’t forget to add DNS records for leaf, spines and APICs.</p>

<p><img class="center" width="800" height="400" src="/images/apic_day_0_config/11.jpg" alt="APIC DNS Configuration" title="APIC DNS Configuration" /></p>

<p><strong>12.</strong> Here we can check status about what we done already. Below you can notice that still we have to configure BGP route reflectors.  To configure BGP just press button <strong>Begin</strong> which will redirect you to configuration page.</p>

<p><img class="center" width="800" height="430" src="/images/apic_day_0_config/12.jpg" alt="APIC setup overview" title="APIC setup overview" /></p>

<p><strong>13.</strong> Press <strong>plus</strong> sign and add minimu two spines per Cisco ACI fabric site.</p>

<p><img class="center" width="800" height="400" src="/images/apic_day_0_config/13.jpg" alt="APIC BGP RR config" title="APIC BGP RR config" /></p>

<p><strong>14.</strong> From drop down choose node id of your spine. As I am using Cisco ACI Simulator I have only one spine with node ID 103. For test I am using default AS number.</p>

<p><img class="center" width="600" height="250" src="/images/apic_day_0_config/14.jpg" alt="APIC BGP RR config" title="APIC BGP RR config" /></p>

<p><strong>15.</strong> Below you can see that spine with node ID 103 was successful registered like RR in Pod 1.</p>

<p><img class="center" width="800" height="300" src="/images/apic_day_0_config/15.jpg" alt="APIC BGP RR config" title="APIC BGP RR config" /></p>

<p><strong>16.</strong> Short overview all looks good as Proxy won’t be used.</p>

<p><img class="center" width="800" height="400" src="/images/apic_day_0_config/16.jpg" alt="APIC setup overview" title="APIC setup overview" /></p>

<p><strong>17.</strong> Summary page, last step for configuration setup.
<img class="center" width="800" height="430" src="/images/apic_day_0_config/17.jpg" alt="APIC setup summary" title="APIC setup summary" /></p>

<p><strong>18.</strong> I would like to recommend you to check <strong>Dashboard</strong> sections like below on print screen</p>
<ul>
  <li>Switches should be <strong>Healthy</strong>.</li>
  <li>Controllers should be <strong>In service</strong> and <strong>FullyFit</strong>.</li>
</ul>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Note
This is only zero day configuration for Cisco APIC. For MultiPod, Multisite, 
Remote Leaf and other Cisco ACI Fabric designs should be configured other parameters
and network objects.
</code></pre></div></div>
<p><img class="center" width="800" height="400" src="/images/apic_day_0_config/24.jpg" alt="" title="" /><br />
<br />
<br />
<strong>Bonus steps</strong> for those how like to have clean ACI fabric without lot of system notifications.<br />
Next few steps will describe how we can disable  messages from Cisco Smart Software Manage, this is mostly applicable for lab deployments and ACI Simulator as after 90 days should be reconfigured.</p>

<p><strong>19.</strong> From APIC notification center please choose Cisco Smart Software Manager (CSSM).</p>

<p><img class="center" width="800" height="400" src="/images/apic_day_0_config/18.jpg" alt="APIC notifications" title="APIC notification" /></p>

<p><strong>20.</strong> Press on fault notification F3057.</p>

<p><img class="center" width="800" height="400" src="/images/apic_day_0_config/19.jpg" alt="APIC notification" title="APIC notification" /></p>

<p><strong>21.</strong> As below on print screen click on <strong>Configure Network Settings</strong>.</p>

<p><img class="center" width="800" height="350" src="/images/apic_day_0_config/20.jpg" alt="APIC notification" title="APIC notification" /></p>

<p><strong>22.</strong> From drop down menu choose <strong>Offline</strong> click on OK and you are ready.</p>

<p><img class="center" width="500" height="400" src="/images/apic_day_0_config/21.jpg" alt="APIC notification" title="APIC notification" /></p>

<p>I have walked through most important parameters for Cisco ACI Fabric. Now you can start to play with Cisco ACI Fabric network objects or you can proceed with fine tunning for the production environment. 😎</p>]]></content><author><name>Tomislav Kranjec</name></author><category term="ACI" /><category term="aci" /><category term="fabric" /><category term="apic" /><category term="leaf" /><category term="spine" /><summary type="html"><![CDATA[Cisco APIC Initial Configuration and Fabric Provisioning]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://tomislavk.blog/images/apic_day_0_config/apic.jpg" /><media:content medium="image" url="https://tomislavk.blog/images/apic_day_0_config/apic.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>